

a new way to: inference. pre-training. post-training. quant. kerneling where no one has kerneled before.
Ottawa
Joined October 2025
- Tweets1.5K
- Following24
- Followers327
- Likes661





GPU capacity is expensive and difficult to secure. Learn how inference efficiency can increase AI serving capacity from the hardware you already have.
What he said 👇

To make models perform more efficiently, some choose to quantize them meaning they compress the model to a point where it gets a bit dumb (dumbify?).
We took a one of these quant models (FP8) and compared it to its fully intelligent original (BF16) and we achieved faster and more throughput by every measure.
You don't have to sacrifice model integrity.
23
You don’t have to buy more hardware to see faster inference.
In @SemiAnalysis_' AgentX benchmark, Backboard produces 10,525 tokens per second for each GPU in Qwen. SGLang produces 8,013.
That's 31% more work out of eight H100 GPUs at full bf16 precision against SGLang’s FP8.
This performance can reduce your GPU costs and keep you running the systems you already have.
ow.ly/6K2P5105cQM

We’d rather show you a narrower advantage than make you find it.
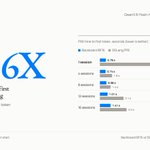
In SemiAnalyisis’ AgentX our p90 interactivity in Qwen is close to SGLang’s at four and eight concurrent sessions: we’re 1.1x ahead, not 12.8x.
The lead opens up at one, 12, and 16 sessions. The full tables are public, so you can judge for yourself.
This can still equate to faster AI without spending on new infrastructure.

Agents shouldn’t take long to get started. That’s the difference between getting work done and giving up.
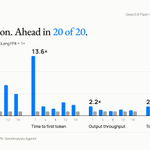
In a single session, SGLang's published p90 time to first token with Qwen is 10.6 seconds.
Ours? Just 0.78 seconds.
You can get near-instant agentic AI responses while saving money on hardware.

Full precision shouldn't be the slow option.
FP8 quantization makes a model smaller and faster to run, but at lower precision.
We ran a full BF16 Qwen model, with no quantization and no precision loss, and still posted consistently higher numbers than SGLang.
You can get the most accurate results without paying for more infrastructure.

BackboardIO retweeted

Why I care about inference efficiency:
Our best Gemma 4 12B throughput gain over vLLM was 34%.
At the same hourly GPU price, that implies about 25% lower GPU cost per output token, before Backboard fees.
For a provider with demand waiting, that extra capacity matters.
backboard.io/blog/gemma-4-12…

BackboardIO retweeted
Outperforming DeepInfer In Decode And Prefill
At 65,536 tokens per step, Backboard delivers 1.37× the prefill throughput of our DeepInfer run.
@SemiAnalysis_ @ArtificialAnlys @lm_zheng
backboard.io/blog/deepseek-v…

Time to first token is the wait before anything happens. For an agent chaining dozens of calls, that wait magnifies.
Backboard cuts that delay by an order of magnitude. We reach that first token in 0.78 seconds with one session in Qwen where SGLang takes 10.6. It’s up to 13.6x faster, and ahead at every concurrency level we tested.
Quicker answers and agents can translate to lower GPU costs and using only the infrastructure you have.
ow.ly/IJSu51059rJ

Interactivity is how fast tokens stream once generation starts. It's the difference between an agent that feels instant and one that stutters.
In AgentX, Backboard's p90 interactivity versus SGLang is up to an order of magnitude better: 12.8x in one session, 5.0x at 16 sessions.
See our full results in the blog post.
ow.ly/zmRx51053g1


Our benchmark rules are simple:
Benchmark what you built, not what you built for the benchmark. Hold the model, hardware, workload, and measurement constant. Publish the failures and the trade-offs alongside the wins.
Everything we share follows those rules.
BackboardIO retweeted
Gemma 4 12B: 104/104 wins against vLLM. 104/104 against SGLang in our InferenceX tests.
Every measured metric. Every tested load. One RTX PRO 6000 Blackwell. All engines running BF16.
@GoogleDeepMind @NVIDIAAI @BackboardIO

BackboardIO retweeted
By every metric (208 of them) @BackboardIO beat vLLM and SGLang on InfetenceX by @SemiAnalysis_ by 1.5X on @GoogleDeepMind Gemma4. More to come.
BackboardIO retweeted
Do you like money?
At 16 concurrent AgentX sessions, Backboard delivers 26% more output throughput while making the experience dramatically faster.
For a provider running 1,000 H100s, that's potentially $4.6M in annual net capacity value, assuming $4/GPU-hour and full utilization.
No additional GPUs. Just better economics from the infrastructure they already have.
And we're doing it at full BF16 precision.

Backboard delivered up to 12.8× better p90 interactivity in AgentX than SGLang.
In @SemiAnalysis_' agentic inference benchmark, Backboard running at BF16 (full precision) achieved not just that superior interactivity but 13.6× faster time to first token. and 1.3× higher total throughput than SGLang’s published FP8 results at 16 concurrent sessions on 8× H100 GPUs.
We’ve published the full results, including the data at all concurrency levels: ow.ly/hpgB510515m

Backboard delivered up to 12.8× better p90 interactivity in AgentX than SGLang.
In @SemiAnalysis_' agentic inference benchmark, Backboard running at BF16 (full precision) achieved not just that superior interactivity but 13.6× faster time to first token. and 1.3× higher total throughput than SGLang’s published FP8 results at 16 concurrent sessions on 8× H100 GPUs.
We’ve published the full results, including the data at all concurrency levels: ow.ly/hpgB510515m
The SGLang figures are based on the published AgentX reference, not a same-box rerun by us. @SemiAnalysis_, run our engine yourselves — same benchmark, same workload. @lm_zheng
2
17
BackboardIO retweeted

We're so bad at comms, but we're getting better. dev.to/jon_at_backboardio/we…

BackboardIO retweeted
We beat DeepInfer head to head, more to come, but hope @SemiAnalysis_ notices @BackboardIO soon, even though we’re a Canadian lab without hundreds of millions of dollars and thousands of contributors. A win is a win.
