

The swarm inference company
Mountain View, CA
Joined April 2024
- Tweets295
- Following408
- Followers31.5K
- Likes5.1K




Pinned Tweet
Introducing Fortytwo Engine
An inference API that runs open-weight models through Swarm Inference
• 7% higher scores on average vs. the base model
• Nearly 25% fewer tokens per task
• Same per-token price and speed
• Private by default
First model: Qwen3.8-27B
Try it: engine.fortytwo.network
Nemotron 3.5 Super VL is live on Fortytwo Engine
Same weights, turbocharged by Swarm Inference:
• Up to 45% higher scores on select benchmarks
• Up to 80% higher token efficiency per task
Available for free: engine.fortytwo.network
Fortytwo retweeted

We built Fortytwo Engine to compete on intelligence per dollar, but most inference providers we see compete only on price and speed, without revealing how much accuracy gets lost in those optimizations.
Thanks @fluence_project for inviting us to write about these issues

The same GPU costs about 2x more at a hyperscaler than at a GPU cloud. The four largest hyperscalers plan about $730B of capex in 2026.
Who’s winning the race for GPUs? We put prices, capex and supply side by side in The AI Compute Race Report, with @near_ai @gensynai @Compute_Labs @fortytwo @Theta_Network @PhalaNetwork @BoundlessHQ @gaib_ai @ionet 👇

We’ve cut Qwen3.8 27B pricing by 80%
Qwen3.8 27B on Engine:
• Up to 13% higher benchmark scores
• Up to 25% fewer tokens per task
Get your API key: engine.fortytwo.network

Qwen3.8-27B is free on Fortytwo Engine for 24 hours.
Same model. Swarm inference on top.
Starts today at 12:00 UTC.
Any task, any volume, no card.
Get an API key and point your agent at it:
engine.fortytwo.network

More Fortytwo Engine credits just landed in community mailboxes
Try our enhanced open models: build an agent, automate your work, or just experiment
10 days to activate your code
60 days to put your credits to work
Check your mailboxes or claim directly here: fortytwo.network/claim


Dear community,
We’ve got some credits for you to use on Engine!
Check your inbox or claim them here: fortytwo.network/claim
What are you going to build with the Fortytwo API?

Fortytwo Engine more than doubled Qwen3.8-27B’s score on @scaling01's LisanBench
Standalone BF16: 2,452
Fortytwo Engine swarm: 5,197 (+112%)
LisanBench tests strategic planning, memory and constraint following: build the longest word chain possible using single-letter edits, dictionary words and no repeats.
Both runs: 50 starting words × 3 trials, temperature 1.0, 100k-token cap, xhigh reasoning, leaderboard scoring.
What improved:
• Repetition loops observed in the standalone run; none observed on Engine
• Higher mean scores on 40/50 starting words
• Mean link validity: 92.2% → 97.1%
• Fully valid chains: 5.6% → 22.9% of recorded answers
• Answers after retries: 72/150 → 140/150
Against the October 16 leaderboard, these scores would place 28th → 14th, putting Qwen3.8-27B on Fortytwo Engine between GPT 5.4 (medium) and DeepSeek V3.2 Speciale.
These are our runs, not official leaderboard entries.
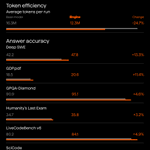
Qwen3.8-27B by @Alibaba_Qwen is now live on Fortytwo Engine.
Same model, with better answers:
• 24.7% fewer tokens per run
• DeepSWE: +13% accuracy
• GDP.pdf: +11.4% accuracy
• Same per-token price and speed
Test it on your own tasks:
engine.fortytwo.network

More details: unite.ai/fortytwo-launches-e…

Fortytwo retweeted

Ivan Nikitin (@inikitin) co-founder and CEO at @fortytwo says the AI race doesn't have to be won by whoever controls the biggest data center, chips, and energy supply.
Small specialized models are far more efficient and Fortytwo connects many of them into one network.
Working together they can beat frontier models while running on ordinary laptops.
Fortytwo retweeted
Two great days at @hub71ad Impact Defined 2026 in Abu Dhabi.
We showcased Swarm Inference at the Fortytwo booth and pitched it from the stage.
The strongest conversations were around sovereign AI: how enterprises and governments can get frontier-grade intelligence where their data already lives, using specialized models and swarm infrastructure instead of relying entirely on centralized AI providers.

Excited to be joining Hub71’s Cohort 18 in Abu Dhabi!
We’re working closely with new design partners across robotics, engineering, aviation, and supply chains to scale swarm intelligence for real-world domains.


The future of innovation starts here ✨
We're proud to welcome Cohort18 to Hub71, a new group of ambitious founders building solutions that will shape industries, solve global challenges, and drive the next wave of technological advancement.
Read more here: go.hub71.com/cohort18
#Hub71 #Cohort18 #InAbuDhabi
@persium_aq I @digistain I @matregenix I @LifeRubedo

Swarm Inference now supports vision.
Fortytwo can apply multiple specialized VLMs to the same image, compare their interpretations, and converge on a more accurate answer.
Industrial safety, satellite imagery, logistics, retail, robotics: anywhere visual accuracy matters.
Because the swarm uses efficient specialized models, Prime Vision delivers frontier-level analysis at a fraction of the cost of monolithic flagship VLMs.
Available now to select customers. General availability next month.

To stress-test Fortytwo Prime Vision, we built a new showcase: Fruit Counting.
One image. One prompt. Pass@1. 11 models.
The task sounds trivial: count bananas, apples, and oranges, including partially overlapping fruit.
But this is exactly where vision models still fail. They see the scene, but lose count, miss overlaps, or confuse similar objects.
Swarm Inference stays consistent by comparing multiple visual interpretations instead of trusting a single model’s first answer.
Showcase: showcase.fortytwo.network/?p…

2
19
1,744

The self-evolving network of AI models powering AGI for everyone
fortytwo.network/


