

Democratizing frontier AI R&D to accelerate science and technology.
San Francisco
Joined March 2026
- Tweets32
- Following0
- Followers11.4K
- Likes15



Today we're announcing our $1B Series A, led by @kleinerperkins and @clearlake.
We believe making frontier AI R&D more accessible is the most direct path to AI that solves humanity's most pressing problems across science and technology.

We are grateful to @BatteryVentures, Doerr Capital, @eladgil, @Google, @M13Company, @pearvc, and S32, among other new and existing investors, for participating in this round.
Read more here: bit.ly/48QIdUK

Huge thanks to @baseten! Fast, reliable rollouts and seamless weight syncs kept our RL run moving at scale. A great partner across the board.

.@mirendil is building self-accelerating AI R&D to solve humanity's most pressing problems. To scale RL training across a global fleet of thousands of GPUs, it runs frontier RL on Baseten.
We power their rollout fleet with new policies served in ~40 seconds, and sampling optimized for 1.9× higher throughput.
Learn more about our collaboration here: baseten.co/resources/custome…

Proteins, materials, medical scans: more and more of science runs on AI. Building it takes a team.
It doesn’t have to. One Mirendil researcher just pretrained Mirendil-Base in 3.5 months: bit.ly/4ssSbEV
We are building Lor to be a frontier AI lab for every scientist.

1
35
3,418
Lor is in private beta: free during the beta, on macOS, Linux, and web, running Claude, GPT-6, Gemini, open models, and our own Fern.
We’d love to work with the people who’ll push it the hardest. Join the waitlist: mirendil.com/lor-beta/

3
46
3,194
What you can hand off to Lor:
“Run these 12 ablations overnight and write a report.”
“Audit all files in this repo for security bugs & open a PR for each fix.”
“Reproduce Table 2 of this paper on 8 GPUs & explain where our numbers differ.”
Read more: bit.ly/4kl5e9l

1
2
212
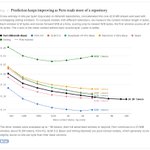
Introducing Fern, Mirendil’s first model: pretrained from scratch, with up to 10 million tokens of context.
That’s ~0.5M lines of code or days of an agent’s work - all in context at once.
Built for high-volume agentic work in AI R&D: auditing training data, debugging training runs from logs, and reading agent traces end to end. Fern’s next-token prediction keeps improving as context grows to 10M tokens.
Fern 0.1 is Mirendil-Base after a short round of post-training. It’s the first and smallest of three models, with two larger ones now being pretrained.
We’ll ship frequent updates and make the model available soon.

After a short round of post-training, here’s where Fern 0.1 stands on agentic benchmarks. This is our first version, with frequent updates ahead.

1
33
3,982
Read more and request early access here: mirendil.com/news/introducin…

Mirendil retweeted

We ran @mirendil's new base model on Baseten's private codebases; that is, code it's never seen. Mirendil-Base-Large had the lowest bits per byte (a tokenizer-independent measure of perplexity) of any model we tested.
We're excited to be the inference partner to serve Mirendil models. Congrats to the Mirendil team on this launch!
