

the world's most popular way to build on open models https://teapawt.org/t.co/1JpLwJ9Bdv
California, USA
Joined August 2023
- Tweets8.9K
- Following618
- Followers188K
- Likes15K


Pinned Tweet
Kimi K3.1 Pro from @Kimi_Moonshot is now available on Ollama Cloud.
🔒 Hosted in the US with full zero data retention.
2.8T total parameters with 104B activated, designed for coding, 3D creation, financial research, and other agentic tasks.
Run it on Ollama Cloud:
ollama run kimi-k3.1-pro:cloud
ollama retweeted

AI is using more and more of the world’s energy. But how much economic value are we getting from AI?
We’re introducing Joules-to-GDP (J2G), a framework that measures how well AI turns energy into economic value and shows which tasks, models, and hardware give the best return.
Across 44 occupations in finance, engineering, law, administrative work, and more in @OpenAI's GDPval, we arrive at three findings:
1) The tasks with the highest economic value are not the tasks with the highest economic value per joule. For example, CAD design earns ~10% more per task than building websites, but the latter earns ~27% more value per joule.
2) The most powerful model isn’t always the best use of energy. Gemma 4 31B delivers 56% of GLM 5.2’s net value with 23% of the energy, for 2.5x the value per joule.
3) More chips don’t guarantee proportionate returns. Moving the same model from 1 to 8 NVIDIA H100s uses 3.2x the energy but cuts completion time by only 22%, with about the same value.
With @SnorkelAI, we’re also releasing GDPWorks, a benchmark for economically valuable tasks across 36 additional occupations.
Joint work co-led by @amirzeinaalii and @Avanika15, with @Mersad_Abbasi, @Jon_Hartley_, John Hennessy, @HazyResearch, and @Azaliamirh.
More details below 🧵

Kimi K3.1 Pro rolling out on Ollama Cloud shortly.
US based. Zero data retention.

Releasing the model weights of Kimi K3.1 Pro: huggingface.co/moonshotai/Ki…
We'll keep advancing open intelligence.

We sat down with South Korea’s Vice Chair of AI, @JungWooHa2, in Seoul this week to talk about open source adoption, the critical role open models play in cybersecurity and broadening AI access throughout Korea, and the importance of our partnerships across the Korean AI ecosystem to grow our community.
@jmorgan

ollama retweeted

Some numbers here - @ollama...
Model Warm TPS Cold TTFT
gemma4:e4b 122.8 8.65s
qwen3-coder:30b 90 10.25s
gemma4:26b-a4b 86.9 13.03s
gpt-oss:20b 60.7 9.93s
qwen3.8:latest 25.3 14.84s
It feels really quick for a laptop running local models.

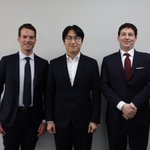
Our CEO @jmorgan was invited to @SeoulNatlUni to give a lecture on open model adoption for more than 200 students. Professors Jae W. Lee, Tae-Wan Kim and the entire team at SNU’s AI Institute are doing incredible work to advance Korea as a global AI leader. Thank you for hosting us!


Enterprise teams around the world (including Korea, where we'll be next week!) are using Ollama to transition their workflows to open models.
@togethercompute @vipulved @jmorgan
Recent model updates from the past two weeks 👇
In Ollama’s cloud ☁️:
- Beam (free for a limited time!)
- Muse-spark-open
- MiniMax-m3.1-flash
- Mistral-large-4
- DeepSeek-v4.1-flash:1017
- Clef (Decision)
Local 🦙:
- Bonsai-2
- EmbeddingGemma-2
- Flint
- Nemotron-3.5-bolt
- Nemotron-3.5-super
- Phonon (Text-to-Speech)
Decision models: Clef-flash, D1, D1-omni, D3, Kev, Laya, Nimble, Nimble-v3, Pplx-decider, Strands-decider, Tev1
Try any of them after downloading Ollama:
ollama run <model_name>
forgot to include LFM3! ollama.com/library/lfm3

여러분, 안녕하세요! 🇰🇷
We are days away from our first trip to Seoul!
Come meet us and @friendliai on Nov 5th.
We would love to see you there!
Register below ⬇️
luma.com/ollama-friendliai-m…

Run the best frontier open models on Ollama's cloud today @CrusoeAI @mchiang0610
ollama retweeted

Two companies, one goal: open models that work for builders at any scale.
@jmorgan of @ollama and @vipulved of Together AI on where open models win, how to spend tokens wisely, and what developers want next.
📽️: youtube.com/watch?v=ZAGVED3p…

ollama retweeted

LFM3: new generation with six edge models
I'm super happy with LFM3-1.7B, it's an absolute (agentic) monster


Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
