

The voice layer for agents. Real-time, accurate, natural voice APIs: TTS, STT, turn-taking & voice design. Devs: build → https://teapawt.org/t.co/BMTX2dOALw
Joined September 2025
- Tweets333
- Following38
- Followers6K
- Likes625


Pinned Tweet
A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
gradium.ai/phonon🧵
Ask a voice agent something it has to look up, and you’ll usually hear silence while it searches.
Some time ago we built a voice agent with @KeenableAI that searches the live web mid-conversation and answers without the pause. Congrats to the Keenable team on launching 1.0 last week.
Try our demo and ask it for this week’s latest AI news:
gradium.keenable.ai

Keenable 1.0 is live
Two months of learning from agent queries made Keenable the best web search API for agents: #1 on Artificial Analysis and NEEDLE.
1.0 adds 100M knowledge cards and dynamic snippets that cut tokens by 50% on research tasks.
keenable.ai/blog/keenable-1.…

Last week we saw an iconic red bridge in two cities.
Neil spoke at @Vapi_AI's VapiCon in San Francisco, while Alexandre joined @AgoraIO to talk about scaling voice AI and was on stage at @WebSummit in Lisbon.
Next:
→ Nov 18, Helsinki: @neilzegh joins @mattturck live at @SlushHQ
→ Nov 28–29, Berlin: Big Berlin Hack with @techeurope_, register: gradium.link/big-berlin-hack


We can’t wait to see what you’ll build with Gradium.
Registration for the Gradium × @TensorTonic contest is open: tensortonic.com/contests/gra…

Exciting announcement
We're running a 30 day contest with @GradiumAI at TensorTonic.
Build a voice app on Gradium's text-to-speech API. Voice is turning into the default way people talk to software, and this is a month to build something real on it with the team behind one of the strongest text-to-speech models available today.
> 2M Gradium credits in prizes
> A chance to interview for ML roles at Gradium
> Internship interviews at TensorTonic
> Exclusive merch for the top 5
> TensorTonic Plus for the top 10
Starts 20 Nov. Registration is live: tensortonic.com/contests

Welcome to our weekly community spotlight.
Rosalie Wessels and Christian Zimmer won the Agentic AI Hack in Zurich with ∑cribe, a tutor for handwritten notes that you can talk to, powered by Gradium.
Hear their story of building it with Gradium Text-to-Speech and Speech-to-Text models.
Join our community to explore other projects or submit yours: gradium.link/community

180
Describing a voice in writing is harder than it sounds. It’s much easier to say it out loud.
That’s why we have an agent you can just talk to. Let’s say you need a British narrator. Add whatever details you have in mind, maybe he’s in his fifties with a warm, unhurried manner of speaking, and Gradium Voice Design brings him to life. Ask for “a bit lower” and it changes just that, keeping the same speaker.
The code is open source: github.com/gradium-ai/gradbo…
Thanks @GoogleCloud_FR for having us at Google Startup Day!
@neilzegh shared what drives us at Gradium: real-time voice models that turn every text interaction, including with your agents, into a natural, fast and pleasant conversation.
Merci Google Cloud !
People don’t want another chatbot. They want a real conversation.
German insurtech Jampai is making that happen with voice AI. Our voice Jette is in their ads, and it’s the same voice customers hear when they call.
Watch our full Q&A with Michael Langer: youtu.be/jyzO0hIrMEg #VoiceAI


Nov 10 · @honualx at @AgoraIO, Lisbon
→ luma.com/wqg33o39
Nov 11 · @honualx at @WebSummit, Lisbon
Nov 12 · @neilzegh at VapiCon (@Vapi_AI), SF
Use code NEIL20 for your ticket.
→ vapi.ai/vapicon-2026
Nov 18 · @neilzegh at @SlushHQ, Helsinki
→ slush.org/2026-speakers/neil…
See you there!

Phonon ranks first on the @huggingface Open TTS Leaderboard with the lowest Time to First Audio.

A small, on-device TTS models is competing with models up to 100× their size, and taking first place on specific benchmarks!
@GradiumAI's new Phonon model offers a concrete example.
On the Open TTS Leaderboard, Gradium reports:
- First place on intelligibility in German and Spanish.
- Top-three intelligibility in every language it evaluated.
- Leading CPU streaming results on time-to-first-audio.
These results also show why it’s useful to compare TTS models on more than a single overall ranking.
For the Open TTS Leaderboard, @EricBezzam separates several dimensions:
- Intelligibility, measured through word/character error rates.
- Generation throughput and time-to-first-audio.
- Predicted naturalness scores.
- Speaker similarity for voice cloning.
Leading on intelligibility in a particular language is a specific result, and so is leading on CPU response latency; but neither establishes that a model is best across every use case.
For on-device applications, Phonon’s combination of size, intelligibility, and CPU latency seems really relevant. For other (heavier?) workloads, language coverage, throughput, voice similarity, or delivery may be more important.
Leaderboard:
huggingface.co/spaces/hf-aud…
Gradium’s post: huggingface.co/blog/phonon-t…

Two weeks ago, we opened up Phonon: text-to-speech that runs locally.
240,000+ downloads later, it's 1st in German and Spanish and top 3 in every language we evaluated on the Open TTS Leaderboard.
Thanks @huggingface for the support! Full story: huggingface.co/blog/phonon-t…
Our friends at @SurrealDB built a notes app on Phonon that analyzes your notes and reads the findings back to you, all on-device.
Phonon, our on-device TTS + SurrealDB Agent Memory.
Open source: github.com/surrealdb/surreal…
Come take a look inside our Paris office.
@blwiertz from Tech: Europe chatted with our co-founders and the team about Gradium’s origin story, Kyutai, our friends next door, raising money as Europeans, and opening in San Francisco.
Stay for the voice design demo at the end.
youtu.be/-EDmwk2-S4c

Gradium retweeted

phonon by @GradiumAI is just such a good local text-to-speech model. imo noticeably better than kokoro.
with int8 weights it's only 44 MB!
on a fresh page load with the model cached you can have speech in one of many voices in literally less than the blink of an eye!


26x real time on an iphone. in safari. from a model that's under 40 MB brotli'd, with the same voices and quality as @GradiumAI's own runtime
every word is timestamped, so captions and read-alongs just work.
blixt.xyz/phonon/ (open source, apache-2.0)
Welcome to our weekly community spotlight.
Congratulations to the winners of the @active_builders x Gradium hackathon:
1st: Mirror Voice
2nd: Thread
3rd: Parley
Together, the three projects use Gradium voice cloning, speech-to-text, and TTS.
activebuilders.dev/hackathon…

2nd place: Thread by Andre Ani.
You think out loud, and Cara, Thread’s voice assistant, turns your ideas into a visual mind map. Gradium handles the speech-to-text and Cara’s spoken replies, so you can keep talking while the board grows.
Demo: share.descript.com/view/oFoz…

1
4
157
3rd place: Parley by @radiumcoders.
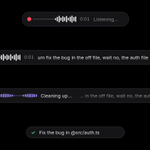
You hold a key and speak, and Parley sends a cleaned-up version of your prompt to Claude Code. Gradium transcribes your speech and reads Claude’s replies aloud. Claude Haiku cleans up the transcript before Parley sends it.
Demo: youtube.com/watch?v=AXHbLjNj…

4
111