





It is the best open weights model from US or Europe on aggregated benchmarks.

Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.


Claude Opus 5.5 pricing:
$5 input / $20 output
Cache write:
$5 (5 min) / $8 (1 hour)
Cache read: $0.20
1M context window, June 2026 cutoff.
It's live on Claude Code v2.1.280.
I also got it in my Claude Code, but if you try to chat with it, it says the model doesn't exist yet.
Soon they will officially announce it.
Now waiting for GPT-6 Sol


we are definitely getting astra senior now

We might be getting a DOUBLE DROP today.
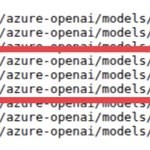
Opus 5.5 is dropping. Now GPT 6 Sol, GPT 6 Luna, and GPT 6 Astra Minor just showed up in Microsoft's Azure config overnight.
OpenAI demoted GPT 5.6 Sol to "workhorse" in the same commit. You do not do that unless the replacement is ready.
We are finally about to get intelligent models we can actually use on our subscriptions.
The biggest day in AI this year might be today.


Daz ✦ retweeted
In case you're wondering, Qwen Image 2.1 is quite uncensored. It has decent anatomy understanding and can do various positions.
I put together a Google Colab for running the Q4_K_M GGUF version.
colab.research.google.com/dr…


Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2…
- GitHub: github.com/QwenLM/Qwen-Image…
- Model Scope: modelscope.cn/models/Qwen/Qw…
- Hugging Face: huggingface.co/Qwen/Qwen-Ima…

In case you're wondering, Qwen Image 2.1 is quite uncensored. It has decent anatomy understanding and can do various positions.
I put together a Google Colab for running the Q4_K_M GGUF version.
colab.research.google.com/dr…
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2…
- GitHub: github.com/QwenLM/Qwen-Image…
- Model Scope: modelscope.cn/models/Qwen/Qw…
- Hugging Face: huggingface.co/Qwen/Qwen-Ima…
Has anyone tried building Mirofish with JEV?
Mirofish handles simulation and collective decision-making, which @typesafeai JEV seems built for. Curious if anyone has explored this stack yet.
Daz ✦ retweeted
Here's a quick animation from my portfolio! Check out more of my work at devansh.aurat.ai
Here's a quick animation from my portfolio! Check out more of my work at devansh.aurat.ai
A hell of a last-minute demo video prep.

Here's what we built:
Name: 🔭 scout
Description: Autonomous DeFi research agent: Graph + OpenSEO scores, x402 micropayments, Privy, ENS identity
Github: github.com/RohitSah23/scout
Public URL: ethglobal.com/showcase/scout…
@8Dazo @deepnsb @ETHGlobal @graphprotocol @ensdomains @privy_io

ALT Screenshot of ETHGlobal 2026 Online Submission Page.


Claude opus5 is been mogged soo hard 🤯

