
I test AI models and agents. 3D / gamedev on the side.
Joined March 2025
- Tweets3K
- Following438
- Followers444
- Likes1.8K
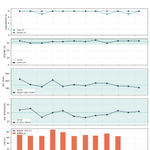





My Grok Bot tests itself every 2 hours, 24/7. Easy questions with an answer key, hard tasks scored out of 35, a style check and a headless Blender test.
Since 1:49am today the easy ones finish in ~12s. Before that it was 65-87s. Three runs in a row, the last one 11.7s.
Quality didn't move. Hard tasks 33/35, Blender 8/8, style the same.
So 5-6x faster for the same result. New model? Faster infra? No idea, the changelog still says v1.0.1. But something changed under the hood tonight.

35
If you need a Bot to check if you pay for subscription you don’t use - they you are retarded and should not have rights to vote
Nothing more to discuss about
48


I'm in Poland, EU.
Grok's bot came first, for everyone world wide (i think) Cool and fast, but still Grok its now just Grok 4.7. Overthinks way too often, big IQ drop last week, kept failing at what I asked. Least issues with "Im not allowed to help with that"
Then Dot on the Business plan csme. Dots is just one Dot... More proactive than Grok - searches, catches bugs. But sounds very AI.
Except voice mode - Sol voice - my wife thought I called a hooker, not an AI🫣 Missing multiple conversations. And Dot chats show up in my regular ChatGPT chats. Why they mix those two?!
Now Claude Duet on Teams. Super cool. Separate topics, five at once is not a problem, shows what's going on in the background. Warmest of them all. Very nice UI, with visible its / our to-do list.
Buuuut shopping recs suck - clothes, appliances, never anything I liked. Mostly "pay for the logo" stuff. Or my fav: "I can't search for that right now...". While Opus refuse to do some tasks, duet seem to be willing to still do it.
Muse doesn't work in the EU, and tbh I don't care. Never was into FB / IG, and Meta gets enough of my data through WhatsApp.
Google - still waiting for something. Could surprise me. So far... waiting. Impatiently.
This week: Duet > Dots > Grok bot.
2
207
Whoever is currently reponsible for @onedrive is a retarded studpid f...
Its even worse than Copilot
How is it possible to f.. up once solid app to total shit level.
49
How to use Claude Duet in Europe:
To turn it on with a Team plan >>>
Step 1 (org admin)
claude.ai → click your name (bottom left) → Organization settings → under Products, pick Claude Duet → turn on “Enable for your organization”.
Step 2
Back in Claude, click your name again and choose “Get apps and extensions”. The Claude Duet card is at the top.
Step 3
Android: download the app. Desktop: “Try on web”, it runs in your browser. iPhone: not available in the EU yet- use web app on iphone.
1
3,344
How to use Claude Duet in Europe:
To turn it on with a Team plan >>>
Step 1 (org admin)
claude.ai → click your name (bottom left) → Organization settings → under Products, pick Claude Duet → turn on “Enable for your organization”.
Step 2
Back in Claude, click your name again and choose “Get apps and extensions”. The Claude Duet card is at the top.
Step 3
Android: download the app. Desktop: “Try on web”, it runs in your browser. iPhone: not available in the EU yet- use web app on iphone.
Currently half of X posts
“Oh my free AI doesn’t give me the top, most expensive model”
“Oh my $20 plan is out of tokens after I used a $50 model for 2 hours”
It’s like reading the retard section in a hospital for the mentally ill.
596
Fable 5.2 is fucking awesome.
Sonnet with Chrome use took 10 minutes to finish the task.
Fable built a new connection to an external website (no API from them).
Now Sonnet finishes the same task in 11 seconds.
I need at least 2 minutes myself, plus another 1-2 minutes to add the output to the hub.
The task now costs 0.017$. That's over 22x cheaper than me and 11x faster.
Max 2 years and I'll have to look for a new job.
Time to change.
115
After the recent issues with Grok Bot, I was honestly scared it would stay crippled forever.
Today it’s working great again.
Speed is amazing - using it feels much better than just a few days ago.
I’ve also set up some tests to see if Grok 4.8 might be getting tested on my account. speed, performance and quality checks every 30 minutes for the next 2 hours, then every hour after that.
If there’s a clear jump in any of the stats, I’ll know right away. Could be a sign of a model change - not proof, but at least something to go on.
Feels like the only way right now to catch when something actually changes :)
What matters to me - the old Grok @bot is back :)
102
I have asked my main bot to prepare a test of his own performance and repeat it every 2h - must be measured by speed and quality
I will know when new grok is out :)

Elon Musk just confirmed that Grok 4.8 was not built on top of the old system. It was built by tearing that system out.
The team dropped JAX and SGLang, then rewrote the entire reinforcement learning and inference stack from scratch in C and C++.
Pre-training is finished. The supervised fine-tuning data needed a major cleanup before it was mostly right. Grok 4.8 is now in reinforcement learning, and the evals are starting to climb.
Elon said 4.8 will bear no resemblance to 4.7, “thankfully,” and admitted it is not incredible yet. But this time the foundations are built right, and he expects it to evolve into something special.
Most labs ship a bigger number on the same old plumbing and call it a breakthrough.
Rewriting the whole stack costs months up front. But every model after it trains faster, runs cheaper, and stands on a base built for where things are going, not where they were.
Upgrades make the next model better. Foundations make every model after it better.
A soft rollout to Grok Bot users starts later this week.

1
91
Looking for some seriously good prompts to put Fable 5.2 to the test.
I’ve got a spare Max account sitting idle. Time to give it something interesting to do.
Got a wild idea, a tricky challenge, or something other models keep failing at? Drop it in the comments. If we build something worth sharing, I’ll put it online.
Let’s see what the latest and greatest AI for us plebs can actually do :)
1
51
Let’s have some fun
Free Fable reset included - at least in a team plan.

Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
1
51