
Generative Models & 3D @googleai @berkeley_ai
California
Joined February 2019
- Tweets2.9K
- Following2.8K
- Followers996
- Likes91.5K




Adam Abecid retweeted

Microsoft AI CEO Mustafa Suleyman says Google Co-Founder Larry Page told him he planned to achieve immortality by uploading his mind to a “successor species” 😳
Adam Abecid retweeted

Genie 4 is here 🌍
It’s our most interactive world model yet, bringing real-time text controls, audio, Gemini reasoning, plus better physics and photorealism.
Enjoyed talking about this with
@OfficialLoganK, @drivascos, and Hang Qi on Release Notes, full episode now on YouTube youtu.be/LOP8ul3KqQI

Introducing Genie 4
Raia Hadsell, Diego Rivas, and Hang Qi from Google DeepMind join ho...
youtube.com
Adam Abecid retweeted

Fresh take on diffusion distillation: the student learns mean flow by matching the teacher with the sum of a straight-line prediction and a curved zero-integral path at random sub-intervals. For sampling, just throw away the curved part.
Not that simple IMO😁 but very clever!

Excited to introduce Simplified Matching Distillation (SMD) for few-step diffusion🧵
No auxiliary score model. No adversarial training. No generator modification.
You will get:
• Photorealistic appearance
• High-quality dynamics
• Memory-efficient training
• Mode covering with diverse outputs
SMD works well across images, video, joint audio–video, and 3D gen, validated across model scales up to 33B parameters.
Besides, SMD supports:
- Multi-teacher capability merging (like OPD in LLM)
- Cross-model capability transfer
- Bidirectional teacher to causal distillation
Full release. Paper, code, model and data.
Project Page: zjwfufu.github.io/SMD-Page/
Paper: arxiv.org/abs/2610.18472
Code: github.com/zjwfufu/SMD
Model Card & Data: huggingface.co/zjwfufu/SMD
Demo Video 👇
1/7 Introducing DeXplicit: making physical state explicit in dexterous manipulation world models.
Given an initial scene and a proposed hand trajectory, DeXplicit 3D forecasts how objects move, articulate and deform. The DeXplicit renderer turns that geometry into future video.
The intermediate 3D state makes the physical response inspectable and provides a control signal for visual generation. Joint-aware actions, coherent object motion and transported appearance connect the two stages.
6/7 Appearance should travel with the object.
We attach initial-image descriptors to persistent 3D points and project them into future views. Depth ordering handles occlusion; initial visibility determines which appearance is available; projected confidence and coverage guide visual completion. The DeXplicit renderer combines this transported evidence with geometry and hand controls.

1
2
234
7/7 Explore DeXplicit, inspect its 3D forecasts and build on the code and weights.
Start with the DeXplicit 3D model, render its predicted geometry with the DeXplicit renderer, or fine-tune on your own interactions. The standard inference and renderer-training recipes use predicted 3D conditions.
Project: dexplicit.github.io/
2
225
Adam Abecid retweeted

Can explicitly learning future point motion improve the model that generates those future images?
We introduce VPM (Video-Point Model), a 4D world model that jointly forecasts future multi-view videos + persistent 3D point trajectories.
Short answer: yes. Teaching a video world model to forecast 3D point tracks makes its videos more faithful & 3D-consistent, and makes robots better.
🌐 Project: rootyjeon.github.io/video-po…
🧵 [1/6]
Adam Abecid retweeted

Simple, efficient, scalable diffusion RL without likelihood ratios?
Meet RVM: Reward-based Velocity Matching
🎯 Rewards directly in velocity space
⚡ Cheap video fine-tuning
🧩 Unifies recent objectives
🎬 Fixes the static-video problem by dynamic motion reward
How it works 🧵
1/8 Introducing Beckmann World Models (BWM): adapting Beckmann transport into fast, one-step action-conditioned world models.
Predicting the next video state from recent observations, proposed actions in one denoising step function call.
Our final RGB model predicts four PushT frames in 24.7 ms on one A800 GPU.
7/8 Across 60 predicted frames, the complete RGB recipe reduces rollout MSE by 68% on PushT and 57% on Robomimic Can versus a same-backbone U-Net trained with pixel MSE (MSE U-Net).
It also improves MSE, moving-region MSE, and LPIPS over our local DriftWorld controls on both tasks.
These comparisons are completed training for five epochs.


1
1
416
8/8 We extend one-call prediction to 256×256 RT-1 and Bridge-V2 video in frozen VAE latents.
This extension uses conditional DINO and latent-feature drifting. Applying those losses to predictions from detached generated histories improves perceptual quality.
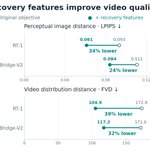
Against same-parent continuations with matched added updates, recovery refinement lowers LPIPS by 34% / 24% and FVD by 39% / 32% on RT-1 / Bridge-V2. Inference retains one generator call per frame.
Joint work with @shoagarwal and @junepyosuh.
Project page: abecid.com/beckmann-world-mo…

1
410