Software developer
Paris
Joined January 2012
- Tweets6.3K
- Following3.4K
- Followers569
- Likes18.8K




AlphaMFPEFM retweeted

OVH annonce Olala mini 7A1B
OVH sa première famille de LLM. Premier représentant de cette famille, Olala mini 7A1B est un modèle compact bâti sur une architecture inédite.
Olala : le modèle innovant dans l’attention hybride
Olala mini repose sur une architecture de 7 milliards de paramètres (7B) avec un milliard activés répartis entre 256 experts par couche, l’attention hybride avec Differential-TPA et Mamba-3, au format BF16. Seule une fraction du modèle est sollicitée à chaque requête, ce qui le rend plus rapide et moins gourmand en mémoire. Conséquence directe: le modèle fonctionne sur un GPU doté d’un minimum de 8 Go de mémoire, il atteint 160 tokens par seconde sur une RTX A4500, et même sans GPU, sur un simple processeur, à 50 tokens par seconde. Sa fenêtre de contexte atteint aujourd’hui 32 000 tokens. Olala mini sera disponible en open source sur Hugging Face, sous licence Apache 2.0.
Entraîné avec l’aide publique européenne et en fonctionnement chez Qwant
Olala mini a été entraîné sur trois supercalculateurs publics européens, Jupiter, MeluXina et Jean Zay, équipés de GPU GH200, A100 et H100. Ce soutien, qui représente l’équivalent de 7 M€ en heures de calcul, a été déterminant, et OVH tient à en remercier les pouvoirs publics. L’initiative publique s’est révélée un succès à plus d’un titre : elle a fait émerger une équipe d’exception en intelligence artificielle et a donné naissance au Lab Agentique d’OVH: OVHai LLM. Olala mini est publié avec ses poids, son modèle de base pré-entraîné, son rapport technique et sa documentation de conformité à l’AI Act. Qwant l’a déjà adopté pour sa fonctionnalité de réponse flash, avec des gains significatifs : des réponses 20 % plus rapides et des coûts de fonctionnement divisés par trois par rapport au modèle précédemment utilisé.
En route vers la v1.1, puis la v2.0
Attendue d’ici la fin de l’année, la version 1.1 portera la fenêtre de contexte à 128 000 tokens et améliorera ses performances en raisonnement mathématique. Avec la version 2.0, OVHai LLM entend développer des modèles spécialisés dans trois domaines. D’abord, l’agentique pour les entreprises : à terme, Olala alimentera OVHai Workspace, dont la version chiffrée nécessitera des modèles capables de tourner en local, directement sur le poste de travail. Ensuite, le DevOps cloud, avec des déclinaisons adaptées aux développeurs, aux architectes et aux équipes d’exploitation qui assurent la continuité de service 24h/24. Enfin, la cybersécurité, dans ses volets défensif comme offensif. Olala v2.0 dépassera les 100 milliards de paramètres.
corporate.ovhcloud.com/fr/ne…


AlphaMFPEFM retweeted

AI can solve a Millennium Prize Problem. It can’t grade a college physics exam.
On real handwritten answers, the best frontier model matches the instructor only 57% of the time.
After grading 6M student answers from 200+ universities, we’re releasing GradeBench (1/8)🧵
AlphaMFPEFM retweeted

We're teaming up to accelerate open-source Al.
OpenRouter is now integrated into Hugging Face directly. Same token, same endpoint, plus live model stats on the Hub and an inference widget we redesigned together.
The best of open, in one place. huggingface.co/blog/openrout…

AlphaMFPEFM retweeted

Two new entrants just reshaped the Text to Image price frontier
Until now, nothing between $10 and $34 per 1k images ranked above Muse Image on AA-Image-T2I v2.1.
➤ Seedream 5.5 is now the best model under $30, at $20 per 1k images
➤ Canva Craft is now the cheapest model in the top 10, at $30 per 1k images
AlphaMFPEFM retweeted

We’re working with @ApolloResearch, @METR_Evals, @TransluceAI, and @GoodfireAI on embedded assessments: giving outside experts deep access to our internal models and systems to investigate alignment and test our safeguards.
These assessments build on our ongoing alignment and safety research, bringing independent scrutiny to how we identify and manage risks in our systems.
openai.com/index/our-first-p…


AI Model releases to watch for in the next days :
- GPT-6.2 Astra/Sol
- Grok 4.8
- Qwen 4
- GLM-5.5
- DeepSeek V4.1 Pro
- Fable 5.5 ? (At least we got Fable 5.2)
- OpenAI's mysterious Bel?
Interesting days ahead !
3
5
390

Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task
Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46)
Key takeaways:
➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo.
➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index.
➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index
➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4.
➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%).
Key model details:
➤ Context window: 1M tokens
➤ Multimodal: Text and image input with text output
➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price)
➤ Availability: @Alibaba_Qwen 's first-party APIs

10
AlphaMFPEFM retweeted
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task
Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46)
Key takeaways:
➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo.
➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index.
➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index
➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4.
➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%).
Key model details:
➤ Context window: 1M tokens
➤ Multimodal: Text and image input with text output
➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price)
➤ Availability: @Alibaba_Qwen 's first-party APIs
AlphaMFPEFM retweeted

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀


AlphaMFPEFM retweeted

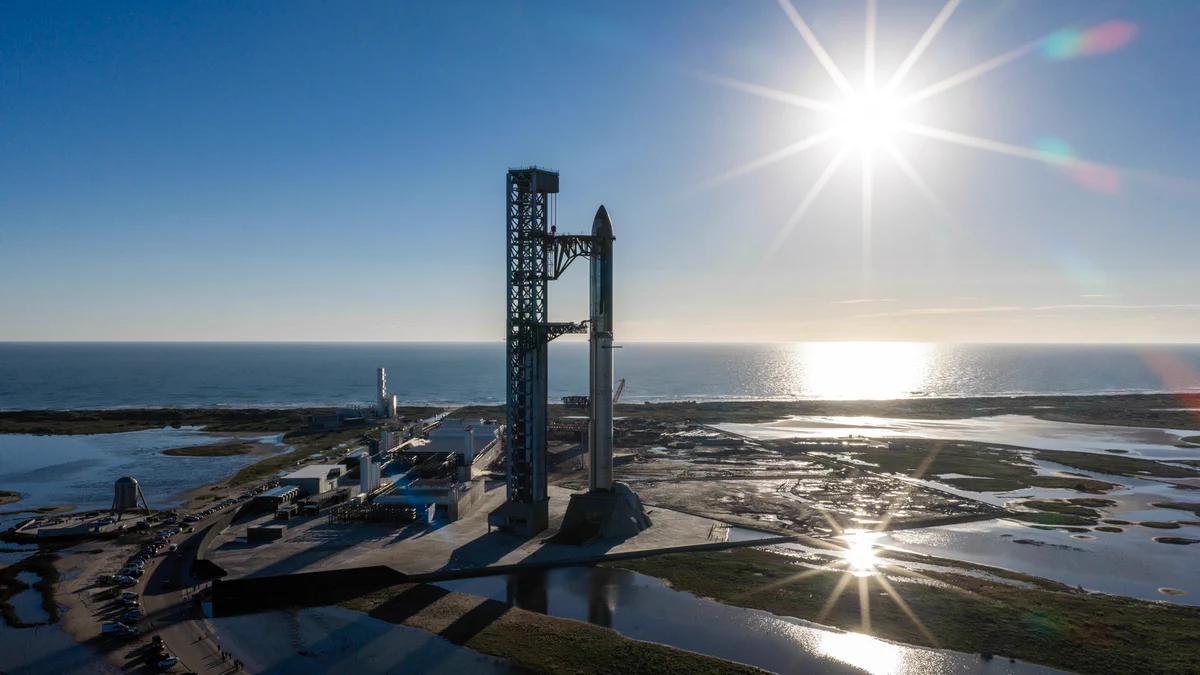
JUST IN: Paris foundry Atelier Missor shares images of SpaceX’s Starship lifting off behind its new Prometheus statue at Starbase.


AlphaMFPEFM retweeted

Yes, the green flame is caused by burning copper from depleting fuel in the regenerative cooling circuit and going oxygen-rich (closer to stoichiometric temperature) in the main combustion chamber.
Slight underperformance of engines on this flight is the reason. The booster is meant to land with tiny residuals, so the solution is to improve engine performance and performance consistency (underway with Raptor V3.2), as well as adjust flight software to do MECO1 about one second earlier to ensure enough propellant for boostback and landing (tiny change).
These early ships and boosters are already outdated by improved designs in production or on the test stand, so this booster loss does not change our timeline to reach high volume, fully reusable Starship flights.
AlphaMFPEFM retweeted

On Friday, November 13, Starship lifted off from Starbase, Texas on its 15th flight.
On Saturday, November 14, Starship returned to Starbase, Texas, and changed everything → spacex.com/launches/starship…

AlphaMFPEFM retweeted

I’ve decided to leave NVIDIA. There are a few things I want to say.
As a robotics engineer at NVIDIA, I have seen Jensen as much more than the company’s CEO.
I admire his willingness to invest in a future that was not yet obvious. He committed to CUDA long before the deep learning boom and positioned NVIDIA for AI before it became everyone’s priority. Those decisions helped build the infrastructure that powers today’s AI.
I have seen that same vision in physical AI: investing in robotics, sharing open-source tools and projects, and building computing platforms that bring AI into the physical world. This is the work I do every day—and a future I believe in.
But what matters most to me is the culture he helped build.
Engineers are encouraged to explore, take risks, and learn from mistakes. Jensen reads employees’ Top 5 emails, follows their work, and engages directly. In a company this large, that connection matters. It makes an individual engineer feel that their ideas can still be heard.
That is why this has been so disappointing.
I do not have all the facts surrounding the allegations, and I cannot prejudge the investigation. My admiration for Jensen does not put him above scrutiny.
What I find difficult to accept is having to come to terms with his departure before receiving an explanation that helps me understand it. What this means for our direction, our culture, and the people doing the work remains unclear to me.
I have felt that engineers’ perspectives matter here. On this decision, I have not felt heard. That gap has been more painful than I expected.
I understand that some information cannot be shared immediately. But that does not erase the feeling of being left outside a decision that affects the company we help build every day.
A company’s greatness comes from its leadership, its governance, and the people who turn its ambitions into reality. Employees’ trust and sense of belonging are part of that, too.
Jensen’s vision and the engineering culture he shaped were important reasons I wanted to stay. His departure led me to decide that my own chapter here should also come to a close.
I leave with sadness and gratitude. The colleagues I have worked with, and the work we believed in together, will always matter to me.
These are my personal views.

AlphaMFPEFM retweeted
Watch Starship Flight 15
teapawt.org/i/broadcasts/2brajgZlO…