

founder/ceo @applied_will @buena_ai prev Strategic GTM, Scale AI @superteamPOL member
🇺🇸🇵🇱
Joined February 2017
- Tweets1K
- Following775
- Followers281
- Likes43.5K

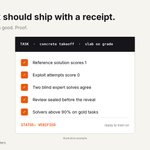




Hot take: most "reward hacking" is a data problem.
The model found a shortcut because the task allowed one.
Fix the task. Grade the graders.
1
2
89

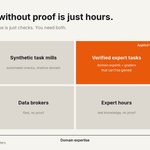
Others sell hours of expert labeling.
What labs need is a verified task: the reference solution passes, exploits fail, and two experts solved it blind.
Sell the proof, not the hours.
2
47
From our construction benchmark (34 synthetic quantity sheets, mean of 3 runs):
Claude Haiku 5.5, text only: 38%
Same model, with the sheet images: 100%
Same model. The input changed, not the intelligence.
If your eval drops the drawings, you're grading the wrong thing.
38
Construction has decades of real data sitting in plan sets, bids and change orders.
None of it trains a model until someone who has done the work turns it into a task with a checkable answer.
That's the job.
25
gm. new week, same rule: grade the graders.
if a model's best scores land on tasks no other model can solve, check the tests before calling it a breakthrough.
1
2
39
At Breakpoint. Who should I meet in London?
@Applied_will builds and verifies RL tasks for AI labs. Looking for:
- investors who get post-training
- people running RL or evals
- P.E.s and estimators
Also anyone whose reward curve looks too good. #BP26
4
190

Started estimating concrete as a teenager.
Then strategic BD at Scale AI, selling frontier data to AI labs.
Now I build @Applied_will: verified RL tasks, starting with construction.
Raising our pre-seed. In London this week. VCs and angels, my DMs are open.
8
8
180
The frontier I care about isn't a leaderboard.
It's a building that goes up safer, faster and to code because the AI that helped design it learned from the people who actually build them.
That's the long game.
1
36
I'm a self-taught engineer. I built the Applied Will platform myself: recorded browser, blind pairs, sealed reviews, payouts.
When you learned your trade on jobsites, you build for the person doing the work.
1
38

Concrete estimating taught me more about AI training data than most papers:
1. Read every sheet
2. Measure twice
3. The mistake hides in the shape you assumed was a rectangle
4. If nobody checked it, it isn't done
1
1
22
Saturday thought: every building you walked into today was checked against a code before anyone poured concrete.
That's the bar I want for AI that touches the physical world. Checked before it ships.
Grade the graders.
1
23
Unpopular opinion: a broken RL task is worse than no task.
No task = no signal.
Broken task = signal that rewards cheating.
Grade the graders.

2
21
Reward hacking checklist for RL environments:
1. Does the reference solution score 1?
2. Do obvious exploit attempts score 0?
3. Can two people solve it blind and agree?
4. Was the review locked in before anyone saw the answer?
Can't say yes to all four? Grade the graders.
1
3
45
Before I wrote code I estimated concrete. Takeoffs, quantity sheets, plan sets.
Construction is a great RL domain: the answers are numbers you can check, and mistakes cost real money.
It's also a domain most labs can't verify in-house. You need people who've done the takeoff.
1
2
30
The best data in the world is useless for RL if nobody can check the answer.
Domain expertise turns a file into a task.
Verification turns a task into training signal.
You need both.

11
gm to everyone whose reward curve went straight up overnight.
check the grader before you celebrate.
1
3
79