




Pinned Tweet
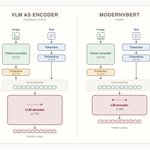
⚡ A lot of representation models still start from a massive generative VLM.
We trained an encoder from scratch instead: native on text and images, multilingual, and built to be fast from the beginning.
I’m super proud to share NeoMME with my friend @tonywu_71. 260M and 800M, no vision tower. We also fine-tuned a visual document retriever on top: NeoMME-Retriever.

Aurélien Lac retweeted

all modalities supported with many new output functions. enjoy d1.2 🚀
blog: liquid.ai/blog/d1-2


Today, we release d1.2 and d1.2-ultra, the state-of-the-art omnimodal decision models. d1.2 and d1.2-ultra both can process text, images, and audio with new output capabilities.
> #1 on the @ArtificialAnlys Decision Index (75)
> Read a value from the input (text, number or date)
> Find every passage of a kind in a text (spans)
> Locate things in a picture (box for one, boxes for every instance)
> Estimate a number (number with a range)
> Pick every option that applies (choice)
1/ 🧵

Big release today: d1.2-ultra and d1.2 are now live on the Liquid API ⚡️
They’re of course stronger than our previous iterations and come with super useful new capabilities:
> Same typed answers from our open d1-2B and d1-Omni-2B: extract a number, a date or a name out of a document with the exact place it came from, bounding boxes around what you describe in a photo, estimates with a range, and select several options at once.
> Audio 🎧: send a clip and ask about it, or just ask your question out loud!
Today, we release d1.2 and d1.2-ultra, the state-of-the-art omnimodal decision models. d1.2 and d1.2-ultra both can process text, images, and audio with new output capabilities.
> #1 on the @ArtificialAnlys Decision Index (75)
> Read a value from the input (text, number or date)
> Find every passage of a kind in a text (spans)
> Locate things in a picture (box for one, boxes for every instance)
> Estimate a number (number with a range)
> Pick every option that applies (choice)
1/ 🧵
We track hundreds of public and private evals internally, and d1.2-ultra is ahead of every decision model we’ve tested on them. But most of the work went into making it more reliable on real tasks, and able to handle more kinds of input, like audio.
1
5
101
We want decision models to be as useful as possible, so please share your feedback, it really helps!
Start using our models: console.liquid.ai

4
74
Aurélien Lac retweeted

Introducing 𝙻𝚒𝚚𝚞𝚒𝚍𝙲𝚘𝚍𝚎𝚌, our ~74M-parameter streaming audio codec powering LFM3-Audio-2B and LFM3-Omni-2B.
An audio codec turns speech into tokens a language model can predict, then converts those tokens back into audio. We built ours around two requirements: tokens that are easy to predict and fast conversion back into speech.
On a single CPU thread on an Apple M4 Max, LiquidCodec runs at approximately:
> 361× real time for encoding
> 87× real time for decoding
Both measurements use FP32 precision.
1/ 🧵
Aurélien Lac retweeted

What is an 𝗮𝘂𝗱𝗶𝗼 𝗰𝗼𝗱𝗲𝗰?
(And why our audio team built their own)
𝗪𝗵𝗮𝘁 𝗶𝘀 𝗮𝗻 𝗮𝘂𝗱𝗶𝗼 𝗰𝗼𝗱𝗲𝗰?
1. Turns speech into tokens
2. Turns the tokens back into audio
𝗛𝗼𝘄 𝗱𝗼𝗲𝘀 𝗮𝗻 𝗮𝘂𝗱𝗶𝗼 𝗰𝗼𝗱𝗲𝗰 𝘄𝗼𝗿𝗸?
→ Encode: turn raw audio into feature vectors
→ Quantize: map those vectors into discrete tokens
→ Decode: reconstruct the waveform from the tokens
𝗪𝗵𝘆 𝗯𝘂𝗶𝗹𝗱 𝗼𝘂𝗿 𝗼𝘄𝗻?
Our earlier audio models used a third-party tokenizer.
But over time, its token quality and design choices started to limit us.
𝗟𝗶𝗾𝘂𝗶𝗱𝗖𝗼𝗱𝗲𝗰 is a ~74M-parameter streaming codec with:
• 𝗛𝗶𝗴𝗵-𝗳𝗶𝗱𝗲𝗹𝗶𝘁𝘆: reconstructed audio is closer to the original.
• 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗲𝗱 𝗳𝗼𝗿 𝘀𝗽𝗲𝗲𝗱: It's fast, even on-device.
Learn more about how our audio team built it in our newest engineering blog:
liquid.ai/blog/liquidcodec

Introducing 𝙻𝚒𝚚𝚞𝚒𝚍𝙲𝚘𝚍𝚎𝚌, our ~74M-parameter streaming audio codec powering LFM3-Audio-2B and LFM3-Omni-2B.
An audio codec turns speech into tokens a language model can predict, then converts those tokens back into audio. We built ours around two requirements: tokens that are easy to predict and fast conversion back into speech.
On a single CPU thread on an Apple M4 Max, LiquidCodec runs at approximately:
> 361× real time for encoding
> 87× real time for decoding
Both measurements use FP32 precision.
1/ 🧵
Very nice update!
While working on multimodal embeddings with NeoMME, @tonywu_71 and I got 255x smaller embeddings while keeping >95% of nDCG@10, using token pooling + asymmetric quantization, with no pooling-aware training at all.
Training for it could push this much further, especially for images, where so many patches are near-empty.
Bonus point: v6.3 now supports our late-interaction-kernels 🙌
github.com/hcompai/late-inte…


🤗 I've released Sentence Transformers v6.3 and wrote a blogpost to highlight its key new feature: token pooling-aware training!
Train multi-vector models to preserve retrieval quality with fewer document vectors. Here's how 🧵
huggingface.co/blog/token-po…


Aurélien Lac retweeted

As a reminder, these were the compression results @Aurelien_L_ and I got by combining token pooling with asymmetric quantization with NeoMME.
teapawt.org/tonywu_71/status/20955…


Aurélien Lac retweeted

I got a 1.9B model to watch a restaurant camera and tell staff which tables need cleaning 🍽️
It runs on my laptop. No cloud, and it generates zero tokens.
Built over a weekend with @liquidai d1-2B
Aurélien Lac retweeted

The anomaly of the LightOn R&D alumnis need to be studied honestly
@iacopo_poli really created something special
IFYKYK


Aurélien Lac retweeted
LFM3 is here! this is an insanely elaborate release, get yourself a coffee ☕️ spend a few hours going through the blog where we tell you everything about it.
The amount of useful intelligence you can pack inside 2B parameters is really insane!
the highlights for me:
> LFM3 architecture got out of our propriety automated hardware in the loop architecture search algorithm optimized for 14 different types of processors. This is exactly the vision we embarked on: building an intelligence fabric on the fragmented device world.
> LFM3-VL-2B is truly a beast performing on par with GPT 5.6 Luna and Gemini flash ultra! at 2B parameters, wtf!!
> It is sooo easy and chip to fine-tune LFM3 instances. you can now truly build specialized intelligence for anything.
> LFM3 is enjoyably fast to train, and deploy.
> LFM3 omni 2B packs all modalities in one model enabling reliable spacial intelligence on device!
> It is now the era of products. lets build together 💫🚀
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
The first models of the LFM3 family are out today!! And of course they come with 2 new decision models ⚡
Meet d1-2B and d1-Omni-2B, built on LFM3-VL-2B and LFM3-Omni-2B.
On top of using these much stronger base models, we worked on adding new capabilities that imo make these decision models way more useful. They can now extract text, numbers and dates from a document, draw bounding boxes around objects, count things with a range, and pick several options at once. Still in one forward pass.
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
These models are a third smaller, faster (3.8 ms vs 9 ms per decision on an MI325X), and they beat our previous d1-3B on most of our private evals and public benchmarks.
But we mainly spent our time making d1-2B much more useful and reliable than d1-3B. And we’re not done iterating.
Please send us feedback! The decision model space is new and moves fast, and we want to make these models as useful as possible.
1
5
153
Expect the d1 models on our API to get the same treatment soon 👀
In the meantime, enjoy the d1 models:
huggingface.co/LiquidAI/d1-2…
huggingface.co/LiquidAI/d1-o…
And all the rest of the LFM3 family:
huggingface.co/collections/L…
More details in our blog post: liquid.ai/blog/lfm3

1
5
155
Aurélien Lac retweeted
Powered by our new d1.1, I built a Telegram bot that sends me a photo when someone is in my office while I am not around
d1 just got an upgrade! Meet 𝚍𝟷.𝟷.
It brings significantly better decision quality than d1, getting closer to d1-ultra while running faster and costing less than half as much.
> built for fast, structured decision-making
> $0.02 / 1M input tokens
> lower latency than d1-ultra
Available today on the Liquid Console: console.liquid.ai
Coming soon to OpenRouter and Vercel.
