

Researcher at @GippLab (@uniGoettingen) and @polizei_nrw_lka who loves #NLP, #AI and food. I also enjoy drinking tea while coding!
Göttingen, Germany
Joined March 2023
- Tweets136
- Following45
- Followers27
- Likes163



Pinned Tweet
🚀 Excited to share our EMNLP 2025 Demo Paper!
MALLM: Multi-Agent Large Language Models Framework
Conduct your experiments on agents discussions, and decisions.
🎥 mallm.gipplab.org
👋 See our poster in Session 11 (Thu, Nov 6 · 16:30–18:00, Hall C)
#EMNLP2025
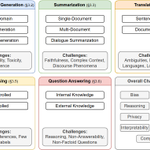
"Text Generation: A Systematic Literature Review of Tasks, Evaluation, and Challenges" is out now in JAIR! 🎉
We reviewed 257 papers (2017–2025), exploring core tasks, evaluation methods, and open challenges of text generation.
📄 Read the review: jair.org/index.php/jair/arti…


New Article: "Text Generation: A Systematic Literature Review of Tasks, Evaluation, and Challenges" by Jonas Becker, Jan Philip Wahle, Bela Gipp, and Terry Ruas jair.org/index.php/jair/arti…
Jonas Becker retweeted

Introducing Voice Arena STT Leaderboard.
LibriSpeech is older than the transformer.
FLEURS is people reading translated Wikipedia sentences aloud.
This is still how the industry ranks speech models. In 2026.
Today we're releasing the Voice Arena STT Leaderboard - a human-verified benchmark for STT accuracy on real, spontaneous conversation, across 7 languages: 🇺🇸 US English, 🇮🇳 Hindi, 🇧🇩 Bangla, 🇧🇷 Brazilian Portuguese, 🇻🇳 Vietnamese, 🇷🇴 Romanian & 🇸🇦 Arabic 🧵
US English Leaderboard ⬇️

🧠 Turns out, even benign AI agents can accidentally become misinformation machines.
Our new preprint studies how false or misleading context spreads inside multi-agent LLM systems—and why debate alone doesn't always fix it.
📄Read: arxiv.org/abs/2606.16710

🚀 Presented at #EACL2026: "Stay Focused: Problem Drift in Multi-Agent Debate"
We identify and mitigate performance drift in ongoing multi-agent interactions.
Key insight: longer debates ≠ better answers - staying focused matters more.
📜 Paper: aclanthology.org/2026.findin…

We will present our work "Stay Focused: Problem Drift in Multi-Agent Debate" at #EACL2026 this week.
🗓️ Our session is Friday (Poster Session 6, 11:00-12:30).
If you are around, feel free to stop by so we can have a chat or just say hi.
Paper: aclanthology.org/2026.findin…
🚀DimStance: Multilingual Dimensional Stance Analysis
🧠 Stance ≠ just Favor / Against
📏 Models stance on valence (low → high) & arousal (calm → active)
📢English, German, Chinese, Nigerian Pidgin, and Swahili
🌍 Politics, Environment
arxiv.org/abs/2601.21483
#SemEval2026
🚀 Stay Focused: Problem Drift in Multi-Agent Debate
✅ Accepted at #EACL2026
🗣️ MAD drifts from the original problem over turns
🔎 Analysis across reasoning, knowledge & instruction-following
🛠️ DRIFTJudge (detect) & DRIFTPolicy (mitigate)
📄 Preprint: arxiv.org/abs/2502.19559

🚀 MALLM: a plug-and-play framework for multi-agent debate.
✅ Accepted as #EMNLP2025 Demo
🔧 144+ configurations out of the box
🔎 Find the best multi-agent setup for your research
📄 Preprint: arxiv.org/pdf/2509.11656
🧪 Demo: mallm.gipplab.org
Jonas Becker retweeted

GippLab attending #ACL2025NLP in Vienna this week!
📄 We presented three papers 🙌
🔗 Find the titles and links to all papers in the comments below👇
#ACL #ACL2025 #ACL25

Jonas Becker retweeted

What a nice birthday gift: ACL Best Resource Paper Award and SemEval Best Task Award. Thanks to all the collaborators who made this possible!


❓ What is Problem Drift in multi-agent debate?
This example shows how agents start with a good solution. However, it gets worse with longer debates.
One agent induces a logical error in the debate. The other agents agree without skepticism, leading to the wrong solution.

More examples and experiments are available in our new preprint "Stay Focused: Problem Drift in Multi-Agent Debate"
arxiv.org/abs/2502.19559
Stay Focused: Problem Drift in Multi-Agent Debate
Multi-agent LLMs are prone to making errors during longer interactions.
Check out how we define this "problem drift", investigate its reasons, and test detection and mitigation strategies at test-time.
arxiv.org/abs/2502.19559
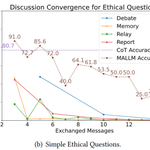
The ethical alignment of Multi-Agent LLMs (MALLM) collapses during ongoing discussions.
This raises concerns about AI safety, highlighting how multi-agent settings come with novel safety challenges that weren't relevant in single-agent scenarios.
Paper: arxiv.org/pdf/2410.22932

🚀MALLM🚀 - Conduct your own multi-agent research by using our new framework for problem-solving:
github.com/Multi-Agent-LLMs/…
MALLM comes with a dataset loader, easy yet configurable discussion formats, and an integrated evaluation pipeline. 🥳

Multi-Agent LLMs for Conversational Task-Solving 💬
Contributions:
1) Taxonomy of multi-agent systems for task-solving
2) Multi-agent framework for your studies
3) Identifies three problems with multi-agent systems: Performance, Alignment, Monopolization
arxiv.org/abs/2410.22932
📑 Text Generation: A Systematic Literature Review of Tasks, Evaluation, and Challenges
Explore recent advances in text generation since 2017, focusing on five core sub-tasks and highlighting key research gaps.
🔗 Read the paper: arxiv.org/abs/2405.15604
🧵 1/8
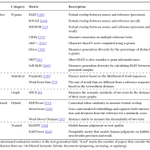
7/8 📊 Evaluation:
Researchers heavily rely on automated metrics.
We find that most works use n-gram overlap metrics like BLEU, ROUGE, and METEOR.
We raise awareness about other metrics to complement evaluation (statistical, graph-based, model-based).