


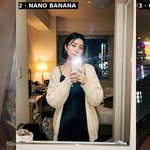





Tokyo it-girl, 1am, hotel mirror.
GPT Image: glossy lips, Shibuya 109 glowing outside.
Nano Banana: messy room, real pores. Camera roll energy.
Grok Imagine: rainbow flare, razor bob. Pure moodboard.
My pick: Nano Banana.
Who are you following? 1, 2 or 3?
Prompt below 👇
Candid iPhone flash mirror selfie of a fictional 24-year-old Tokyo it-girl in a small Shibuya hotel room at night, oversized cream knit cardigan over a black satin slip dress, silver hoop earrings, glossy black bob haircut, phone with a pastel case held in front of her chest, harsh direct flash bouncing off the mirror, warm tungsten lamp behind her, neon city lights through the window, real skin texture with visible pores, slight motion blur, Instagram photo dump aesthetic, vertical 4:5 composition.


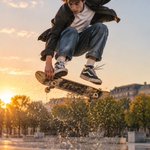
看看运动状态下,两个模型的渲染效果如何:
Image 1: GPT-image-2.5, Image 2: Grok-imagine2
GPT freezes harder: sharper hair, jacket hem, and water droplets, with stronger golden rim light. Grok freezes clean too, but the skater sits smaller in the frame and the light feels flatter. Which freeze looks more real to you? Prompt: High-speed frozen-motion photograph of a skateboarder caught mid-ollie above a wet city plaza at golden hour, a strict test of motion freeze. Subject: a young athlete airborne at the peak of the jump, knees tucked, one hand reaching toward the tilted skateboard, shoelaces, jacket hem, and hair all suspended mid-motion with every strand and fold razor-sharp; beneath the board, a spray of water droplets kicked up from the wet pavement hangs frozen in the air, each droplet a distinct sphere catching the light, with fine dust particles suspended beside them. Environment: a sunlit stone plaza with long shadows, a blurred row of trees and low buildings far behind, puddle reflections glinting on the ground below. Light: warm low backlight at 3500K rimming the skater and droplets in gold, against cool shadowed pavement. Camera: fast-shutter sports photography equivalent to 1/4000s, 85mm lens, f/4, eye-level tracking angle, vertical 9:16 composition, the skater centered against open sky, shallow depth of field keeping the background soft while the subject and droplets stay tack-sharp. Color: Eastmancolor film look, natural contrast, subtle film grain. Mood: explosive, weightless, split-second. Photorealistic action photography, ultra-detailed, high resolution. No motion blur on the subject, No smeared droplets, No deformed hands, No deformed feet, No extra limbs, No text, No watermark, No oil painting, No anime, No 3D render.


好想去看稻城亚丁的雪山海子啊
Image 1: GPT-image-2.5, Image 2: Grok-imagine2 Prompt: Breathtaking high-altitude landscape photograph of Daocheng Yading in early November, where late autumn meets the first snow on the eastern edge of the Tibetan Plateau in Sichuan. Environment: a still turquoise alpine lake at around 4,000 meters, ringed by golden autumn meadows and snow-dusted larch and pine, under a clear, thin high-altitude sky in the early morning. Subject details: the glassy lake fills the lower third and mirrors the snow-capped sacred peaks behind it with near-perfect symmetry; a scattering of dark wet boulders and a fringe of frost-touched golden grass anchor the near shore; a thin skin of ice edges the lake where shadow lingers, and a single trail of footprints crosses a small snow patch on the far bank. Atmosphere particles: faint mist drifting off the water, fine snow crystals glinting in the first sunlight, and thin high clouds streaking the blue sky. Light: low warm morning sun at 3800K striking the peaks from the left, casting long cool-blue shadows across the meadow, with warm gold and cold blue in direct contrast. Background layers: near shore and lake in the foreground, golden meadow and dark forest in the middle ground, three towering snow peaks and pale sky in the far distance. Camera: low viewpoint at the lakeshore, 24mm wide-angle lens, f/11, deep depth of field, vertical 9:16 composition on the rule of thirds, the reflection centered and undistorted. Color: Eastmancolor film look, restrained natural saturation, subtle film grain, crisp high-altitude clarity. Mood: silent, vast, and sacred. Photorealistic landscape photography, ultra-detailed, high resolution. No people, No buildings, No text, No watermark, No oil painting, No anime, No 3D render, No oversaturation, No deformed reflections.


Stronger video understanding means more detailed picture rendering, and the video is more realistic.

Tencent Hy just released Hy4, which adds vision understanding and computer use for the first time. I tested it in WorkBuddy by handing it a 7:19 clip and asking for a shot-by-shot breakdown plus a style card. The prompt was fussy: don't invent dialogue, captions, or brands; keep what you can see separate from what you infer; if a shot changes partway through, split it.
I expected a paragraph about "cinematic texture" and "a relaxed pace". Hy4 went and opened the file first.
@tencenthunyuan @tencentai_news @workbuddy_ai workbuddy.ai
video: youtube.com/watch?v=fXZLWf-I…
prompt:🔗 github.com/smlayero/Model-Te…


