

Tweets about mostly applied Causal Inference, ML Causality tools (especially Python), and a little Causal Discovery.
Joined May 2023
- Tweets364
- Following71
- Followers109
- Likes150


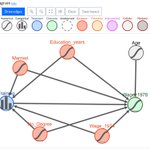


CausalWizard is now fully open-source at github.com/drawlinson/causal…
For convenience, use the hosted version at causalwizard.app/features/ or clone the repo and run the web-app locally.

The code allows you to choose from a wide variety of methods including:
- Linear regression
- Various propensity score methods
- Generalized linear models
- Double ML
18
The web-app allows you to draw causal diagrams, identify methods for estimating causal effects and then train a variety of models using these methods.
25
Causal Wizard retweeted

I just posted a new paper on arXiv:
“Active perception and disentangled representations allow continual, episodic, zero-shot and few-shot learning”
The core idea: stop forcing fast learners to generalize. Delegate generalization to a perceptual system.
arxiv.org/abs/2602.19355

Causal Wizard retweeted

Cool! This reminds me of the fixed-point phenomenon discussed in arxiv.org/abs/2210.12867#:~:… and Fixed point reusing arxiv.org/abs/2204.08442 ! In the latter one, it also actually mentioned the deep supervision step. It’s intriguing that TRM and HRM aren’t explicitly trained with the DEQ method, yet the models still learn to converge toward fixed points, which represents the final answer. Still much to explore about why.

Causal Wizard retweeted
HRM-Agent: Using the Hierarchical Reasoning Model in Reinforcement Learning
Paper: arxiv.org/abs/2510.22832
The Hierarchical Reasoning Model (HRM) has impressive reasoning abilities given its small size, but has only been applied to supervised, static, fully-observable problems.

HRM-Agent: Using the Hierarchical Reasoning Model in Reinforcement Learning
Paper: arxiv.org/abs/2510.22832
The Hierarchical Reasoning Model (HRM) has impressive reasoning abilities given its small size, but has only been applied to supervised, static, fully-observable problems.
Our paper is simply a proof-of-concept and our model is the simplest possible RL agent version of HRM. We're looking forward to working with more sophisticated recurrent reasoning models like HRM and TRM on more complex problems.
Code: github.com/LongDangHoang/HRM…

The original HRM paper by Wang et al can be found here : arxiv.org/abs/2506.21734

9
603
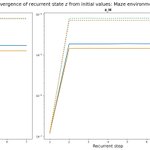
We wanted to know if you can train a Hierarchical Recurrent Model (HRM) to navigate using only RL. Does it make use of computation from previous environment time-steps? Turns out the answers are "yes" and "yes":
medium.com/@causalwizard/hrm…

By popular request, Causal Wizard now supports Double ML:
causalwizard.app/inference/a…
We're a bit unsure whether the configuration we've chosen is sufficiently flexible. Let us know what you think! #causality #epitwitter #causaltwitter #econtwitter
Specifically, we're using #sklearn 's GradientBoosting models for Double ML models y and t, and LassoCV for the final model. The intent is for Double ML to be a alternative to regression models when variable interactions are nonlinear.
90