

PhD candidate @PrincetonCS audio ML. @CCRMA/@Stanford, @BrownUniversity
Princeton, NJ
Joined November 2016
- Tweets275
- Following454
- Followers1.9K
- Likes2.1K
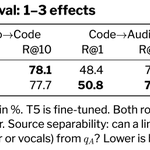
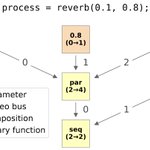
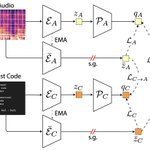


To be presented at ISMIR 2026 ☮️ PEACE, a joint embedding of audio effects programs written in Faust and their corresponding "wet"/"processed" audio.
It enables audio-to-code retrieval when given a library of programs and their embeddings.
Joint embeddings have applications beyond retrieval, and the paper couldn't address all of them experimentally. Think about CLIP/CLAP and make the analogy to rich understanding of digital signal processing code (DSP) and music.
Read the paper: arxiv.org/abs/2610.03405
and codebase: github.com/DBraun/PEACE
More findings from the paper 🧵

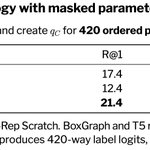
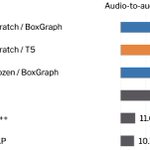
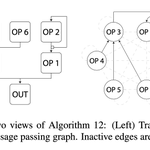
We also train both code encoders to enable a new kind of effect chain retrieval that ignores the parameters of the effects. For T5, we mask tokens as in standard language modeling. For BoxGraph, we randomly replace parameter nodes with learnable embeddings. At inference, either model can "mask" the parameters to create embeddings that (hopefully) represent chain topology alone. For 21 effects, this means 420 permutations of length-2 programs, so a gallery of 420 code embeddings. BoxGraph beats T5 and approaches the performance of a supervised AFx-Rep architecture trained on the same data that uses logits to select the likeliest chain. This gives me hope for "zero-shot chain retrieval": give out-of-domain audio trained on VSTs but retrieve Faust programs that produce similar audio. This will require more high-quality Faust effects to be included in the training data of models such as PEACE, so this is a high-priority for me. Check out the Faust Libraries for more context: github.com/grame-cncm/faustl….

Thanks for reading everything! I want to thank my advisor Adam Finkelstein, the National Science Foundation, the Faust community (especially Stéphane Letz, Yann Orlarey, @JOSmithIII).
Chain retrieval listening demo: dirt.design/PEACE-map/chain-…
and on Desktop (not mobile), check out the cross-modal embedding explorer: dirt.design/PEACE-map/
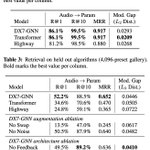
You know CLAP and may know SLAP. Allow me to introduce SynAPSE: FM Synthesizer Audio-Parameter Shared Embeddings. It's a joint embedding of Yamaha DX7 presets and audio. It also investigates a quirky question: is it possible to encode FM topologies not seen during training? 🧵

Our method uses the non-contrastive training objective from SLAP (h/t @Juj_Guinot @howariou @elio_elioo). Like SLAP, we observe a small modality gap. We know text-to-audio relied on CLAP. What's next for SynAPSE? 🤔

Thanks for reading. The code and weights are online: github.com/DBraun/SynAPSE
arXiv: arxiv.org/abs/2608.18226
Interactive retrieval demo (don't try on mobile): dbraun.github.io/SynAPSE
See you at DAFx 2026 where I'll present on 9/2!


