

AI silicon, co-designed with the models it runs. First up: the frontier model's co-processor. Only the math.
Joined October 2026
- Tweets12
- Following0
- Followers261
- Likes4



Exstill retweeted

How efficient can AI inference really get?
Our first technical report brings together ML and silicon co-design, exploring 10M+ chip designs.
Pre-silicon results vs. NVIDIA B300:
• 110× faster token generation
• 690× lower energy
arxiv.org/abs/2611.18859
A thread 🧵

At Exstill, we've evaluated over 10 million combinations of neural network and silicon architectures, searching for the lowest energy × delay at fixed model quality, power, and area.
Why design the model and chip separately when we can optimize them together?
Part 4 of our technical series:
exstill.ai/posts/04-ten-mill…

1
60
Exstill retweeted

In October I said the work around the frontier model had earned silicon of its own. @vithursant19 and I built it. @ExstillAI is out of stealth.
Our belief: AI compute is nowhere near as efficient as it could be. Most of what you pay to run AI isn't the math. It's the mismatch.

Every token has a cost. We think you should be able to account for it.
On Exstill's pre-silicon design:
• “pilot” after 117 tokens: 48 µs, 401 µJ
• “machine” after 16,024 tokens: 50 µs, 520 µJ
Every cycle. Every microjoule. Across the full model.
Part 3 of our technical series explores what AI chip performance numbers actually tell you, and why the methodology behind them matters.
exstill.ai/posts/03-how-to-r…

2
64
Exstill retweeted
This is exactly the tradeoff we’re tackling at Exstill.
Specialization unlocks enormous efficiency gains, but the challenge is building hardware that remains useful as models and workloads evolve.
Our approach is to co-design a shared model architecture with the silicon it runs on, then specialize through training and distillation.
One architectural foundation, different learned capabilities, silicon built for both.
exstill.ai


Jeff Dean says he's bullish on specialized hardware because a handful of workloads will be a lot of the world's compute
"I'm pretty bullish on more and more specialized hardware, because I think that's the way you really get much more efficient systems."
"And we now have workloads where there's like a handful of workloads that are going to be a lot of the compute in the world."
"And so if you think about that, that is crying out for specialization."
"The problem with specialization is if what you want to do changes in the future, then the thing you've lovingly crafted in hardware for maybe two years is no longer perhaps as relevant."
Exstill retweeted
The interesting shift is from how much a model knows to what it can actually accomplish. Smaller models with the right tools and fast feedback loops could change the economics of AI entirely. @ExstillAI

Andrej Karpathy:
“A 1B model can be much more effective than most current LLMs.
90% of current models waste a ton of capacity and money on remembering stuff that doesn’t matter.”
here is his 5 core thesis about Small LLM’s:
1. the intelligence was never the knowledge. Strip the memorized internet, keep the reasoning. What’s left is the cognitive core, and it’s small.
2. the core might fit in ~1B params. Maybe less. “Plenty of room at the bottom.” We’ve been paying for a library when we needed a brain.
3. size stopped being the bottleneck. What makes an agent work is the tools it can call and how tight the feedback loop is, not parameter count.
4. intelligence lives in the system, not the weights. A raw LLM is a CPU with no OS. Small core + good harness > giant model alone.
5. you can own it. A model on your hardware is one no one can rate-limit, price-hike, or deprecate on you.
in 12 months the gap between teams shipping on-device and teams paying per-token frontier bills won’t be capability.
TwIL an 8.8B model at 90%+ of frontier isn’t a benchmark flex.
It’s the thesis Karpathy’s been repeating all year, made real.
study more on this below ↓
Exstill retweeted
Meta's Muse Ember reinforces where we believe AI is heading: frontier models handle the hardest reasoning, while smaller models take on the repeated work inside agents.
At @ExstillAI , we're building the other half of that equation: dedicated silicon co-designed to run small, specialized models alongside frontier AI, making their inference radically faster and more efficient.
exstill.ai/

2/ you can pair the small and big models for the hardest problems: wonder can plan, ember can handle the volume. available now on muse code and API.
research.meta.ai/blog/muse-e…

Exstill retweeted
2/ you can pair the small and big models for the hardest problems: wonder can plan, ember can handle the volume. available now on muse code and API.
research.meta.ai/blog/muse-e…
Exstill retweeted
1/ announcing our smallest, most efficient little model is here: muse ember 🔥
built for work that agents repeat all day, it gets you more intelligence per dollar than Haiku, Luna, and all other flash models at any reasoning setting and does it at a third of the cost or less!

How much of the next token is actually math?
On an NVIDIA B300, we measured 994 mJ/token for one user, 361 mJ with 12 sharing it. The arithmetic alone: 0.89 mJ.
Our co-designed chip projects 0.52 mJ/token at matched quality (pre-silicon).
Part 2: exstill.ai/posts/02-everythi…

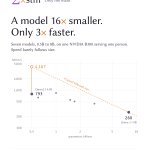
A model 16x smaller. Only 3x faster.
That's what we measured on an NVIDIA B300 serving a single user.
Frontier models get most of the attention, but the smaller models working around them increasingly determine how long users wait.
They draft tokens, screen prompts, route requests, and power multi-step agents. Each operates in the critical path of inference.
Yet they're running on hardware primarily optimized for much larger models and higher throughput.
We think these workloads deserve silicon of their own.
Today, we're kicking off an eight-part technical series exploring the research and engineering behind Exstill, from GPU inference bottlenecks to ML–silicon co-design and our first co-processor.
Part 1: The work around the frontier model.
exstill.ai/posts/01-the-work…

We're coming out of stealth.
The limits of AI compute are inherited, not fundamental.
At Exstill, we're designing AI models and silicon together to push inference efficiency toward its limits.
Our first step: the frontier model's co-processor.
Founded by Valavan Manohararajah and Vithu Thangarasa (@vithursant19), we've been building toward this moment for a while, and we're excited to finally share what we've been working on.
We're just getting started.
Explore what we're building: exstill.ai