
Strategy | innovation | knowledge creation in science, engineering, and technology | organization | cognitive science | AI
San Francisco
Joined July 2011
- Tweets36.9K
- Following1.9K
- Followers2.7K
- Likes39.9K



Pinned Tweet
Let me try and articulate what is see is a genuine tension between Bayesian subjective credences across theories of the world and what constitutes a probability calculus within a possible world bundle.
Brian Gordon retweeted

A piece of advice Hubert Dreyfus gave the grad class:
“The important thing is to ask a sincere question. Otherwise, you won’t know when you’ve got your answer.”
Brian Gordon retweeted

What people call intelligence can be seen as two distinct things
1. how much scale you have
2. how much ability to scale you have
Most peole think of intelligence in terms of (1). Someone like Francois Chollet thinks of intelligence mostly in terms of (2)
The models are weakly good at (2) on their own but not there yet. Labs themselves (and the entire ecosystem that feeds them scaling inputs) remain critical for (2), where the input and output is a thing called “Claude” or “GPT”
Many are implicitly building for a world where (2) doesn’t itself have scaling laws leading to automation, where models remain relatively static objects only capable of a bit of extra test time logical depth. Status quo bias and cope imo
The Models Will Eat Their Harnesses
Brian Gordon retweeted

me: kinda fucked up how many people are offloading their whole lives to muse or instinct or grokbot or whatever
claude: yeah


Without being a lawyer or knowing anything specifically relevant to the S-1, I would still suggest that it’s naive to think law just applies as opposed to evolving to meet the changing technological landscape. Reading Mary Parker Follett and Demsetz would strongly suggest this.

The most important risk factor for Anthropic is the rule of law actually being applied.
"Any determination that we are liable under such theories, or any judicial or regulatory expansion of tort, product liability, or consumer protection law, or criminal liability, as applied to AI models, could result in significant liability and require us to change how we design and offer our models, platform, and applications."
Brian Gordon retweeted

Kevin: I’m struggling with ongoing claims about independent AI discovery.
This looks more like AI free riding (intentionally or not) on human lines of attack: Navier–Stokes, now Yang–Mills. Worth checking what folks working on these problems say, e.g. xitter.cf/__alpoge__/status/2114…


Brian Gordon retweeted

The point of intellectual work is not just to arrive at answers no one else has found yet. The process of working through something can change the questions we ask, and open up possibilities we hadn’t even considered. Why would AI reaching the same conclusions make that any less worthwhile? Poverty mindset.

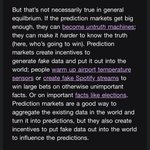
Wisdom of the crowd effects work by aggregating dispersed information into signal about underlying features of the world clouded by (some kinds of) uncertainty. They also incentivize strategic misinformation provision and mkt manipulation, degrading signals & epistemics.

Brian Gordon retweeted
Because equity has unlimited upside, these pitches attract a more compliant kind of capital than debt markets, where losses loom far larger. Ultimately governance seeks to be moving to debt mkts, when, where, and if ‘go/no go’ funding decisions arise. So pointillist governance?

There are task classes where this seems like it’s the inevitable equilibrium.

wrote about AI AS THE INFINITE WORK MACHINE, creating a world where we're all just constantly deploying agents to fight against everyone else's agents, running constantly to end up in the same place:
bloomberg.com/news/newslette…


Tempered by the fact that agents just aren’t great at this (at least yet).

Brian Gordon retweeted

Surprised this isn’t a more standard take in some circles. It’s great that text data had a ton of built in complexity we didn’t know would be there. But for bio, we almost certainly need qualitatively new ways to measure things. New instruments etc.


Brian Gordon retweeted
It would be shocking if say the total surplus appropriated by Alphabet under an alternative ‘secrecy and max appropriability’ policy was even a fraction of what Alphabet alone has already reaped under the OSS/academic norm policy regime.
This decision was downstream of a commitment to open source and academic norms around research. And arguably, it vindicates both counterfactually, so far at least: faster adoption, more competitive mkt, more innovation around the core technical advance, greater total surplus.


