
ML research with practical impact.
Joined December 2019
- Tweets37
- Following67
- Followers476
- Likes25






Something new! I joined @genesismolai to work on AI for drug discovery. After years in machine learning research, drug discovery felt like an impactful place to apply my expertise. It’s also a field with lots of exciting problems and plenty of room to explore ML methods.

#NeurIPS2025 Mixing different datasets to train your LLM?
✨ We can help you find the perfect blend!
📈 Few small-model experiments → scaling law fit → your optimal mixture.
🎯 Easy + efficient.
Chat with us 💬 Poster #3414. Thu, Dec 4, 11am


#ICLR #TrainLLMBetter Tomorrow, #soup of experts, an #hypernetwork conditioned on a simple description of the test distribution: adaptation without retraining (Modularity workshop Sunday). arxiv.org/abs/2502.01804
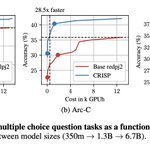
Still on today... CRISP Importance Sampling for LLM pretraining.

1
287
#ICLR #TrainBetterLM I am at ICLR, come to our posters for improved language model training!
Recycle gradients for faster neural net training with AdEMAmix iclr.cc/virtual/2025/poster/… (Fri Apr 25, 10 am).
1/3

2/3
Importance sampling for better pretraining distribution with CRISP iclr.cc/virtual/2025/poster/… (Sat Apr 26, 10 am).
1
2
156
3/3
Mixture of experts on high latency networks with No Need to Talk iclr.cc/virtual/2025/poster/… (Thu Apr 24 3pm).
Joint work with @MatPagliardini, @NasFilippova,@PierreAblin @olivia61368522, Skyler Seto, @angeloskath, Ronan Collobert
2
144
New paper! arxiv.org/abs/2410.03735
Clustered importance sampling to build specialist Language Models (LMs)
🤔 Build a specialist LM with very little specialist data
💡How? Generalist data + efficient, scalable importance sampling
w/ @Olivia61368522+SkylerSeto+@PierreAblin
1/4

🚀Easy with clustered importance sampling:
1️⃣ cluster the generalist dataset,
2️⃣ resample the clusters w/ their prior from tiny specialist data,
3️⃣ Done! 🏁
3/4
1
1
242
⦿ Efficient, scalable approach on LM and Q&A domains.
⦿ Single & multitask.
⦿ Pretraining & continued pretraining.
⦿ Ablations on data size, model size...
arxiv.org/abs/2410.03735
4/4

194
Ademamix optimizer for jax/pytorch:
change one line of code, train your model faster.

🎇Official pytorch/jax implementation of Ademamix🎇
github.com/apple/ml-ademamix
Drop-in replacement for AdamW, much faster LLM pre-training! 🚀🚀🚀🚀

Faster, better model training by reusing old gradients (>10k steps ago) with negligible extra computation? Count me in. arxiv.org/abs/2409.03137

Stop discarding your old gradients! Introducing AdEMAMix, a novel (first-order) optimizer capable of outperforming Adam. Let’s have a thread on momentum and the surprising relevance of very old gradients. A joint work with @GrangierDavid and @PierreAblin #ml #optimization
1/🧵

At ICML? Learn about our efficient projected language models!
Adding capacity to a traditional language model improves
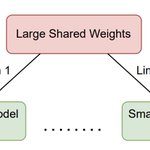
accuracy but increases inference cost. How to avoid this? We propose a novel architecture, projected networks (PN).

2/2 PN is a high capacity network whose parameters can be linearly projected into a small network. This strategy enables both high capacity and efficient inference. See details at our poster on Friday morning and afternoon. openreview.net/forum?id=Wi88…
icml-fm-wild.github.io
199
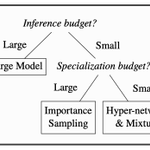
New language model work! In practice, LMs often face a double constraint (i) small inference budget + (ii) little application-specific data: (i) means small specialized models for inference; (ii) means using auxiliary generic data e.g. for pretraining 1/2 arxiv.org/abs/2402.01093

2/2 Findings: when the application-specific training budget is large, importance sampling is great. Otherwise, asymmetric models (big at train, small at inference e.g. mixture of experts or hyper-networks) are attractive, better than the popular distillation strategy.
1
1
259
Efficient bilevel algorithm for training data selection arxiv.org/abs/2311.11973
#bilevel #data_selection #DomainAdaptation #distshift #llm #NeurIPS2023 Online algorithm for filtering large (pre)training sets with maximal impact on the targeted task. (1/3)

Large models are often trained on massive web datasets and a bit of target-task data. In this setup, it is 👍 to spend more train effort on specific parts of the large set. Our online algorithm maintains an auxiliary cheap filter model when training the large model. (2/3)
1
3
546
Our analysis proposes a simple test to check if our method applies to your problem. Chat with us at our poster at #neurips2023 DistShift workshop next week. Joint work with Pierre Ablin, Awni Hannun. (3/3)
3
425