

Invite-only cult of developers making futuristic remote work culture possible, today. Founded in 2016. Apply at https://teapawt.org/t.co/Oequ6RCskD
100% Remote
Joined April 2016
- Tweets2.7K
- Following34
- Followers497
- Likes579




Qwen4-Max cuts input and output rates 25% from Qwen3.8-Max.
In Qwen’s launch chart, it leads on DeepSWE but trails Opus 5.5, GPT-6.1 Sol, GPT-6 Astra and Kimi K3.1 on Terminal-Bench.
We break down the benchmarks, pricing and open-weight plans.
blog.invidelabs.com/qwen4-ma…

51
Two engineers make progress, but neither knows who decides the first release. When a customer changes the priority, only one hears about it.
Our guide shows how to fix that, plus hiring, onboarding, delegation, feedback and growth.
blog.invidelabs.com/build-st…

24
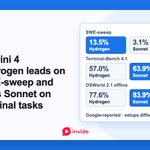
Google’s Gemini 4 Hydrogen scores 13.5% on SWE-sweep versus Claude Sonnet 5.5’s 3.1% in Google’s selected results. Sonnet leads on Terminal-Bench 4.1.
The tests used different setups and sources. We look at the benchmarks, API pricing and cost per task.
blog.invidelabs.com/gemini-4…

36
A year after coding-agent adoption, a 655-firm study estimated:
• PRs opened: +35.7%
• PRs merged: +26.0%
• Time from submission to merge: +56.1%
How to spot where your PRs stall and decide when adding reviewers will help.
blog.invidelabs.com/ai-agent…

21
Claude Fable 5.2 cuts input and output token prices by 20% from 5.1. But at max effort, it cost about twice as much per task on one independent index.
We look at effort settings, Mythos access, Claude plans and API migration changes.
blog.invidelabs.com/claude-f…

1
31
Can an LLM improve another model by editing its weights?
GPT-6 Astra's reported Qwen edit reduced reasoning loops. Stronger unedited baselines complicate the math gains.
How weight-space programming works, and what this experiment shows:
blog.invidelabs.com/llm-weig…

1
1
79
OpenAI kept Git. Anthropic replaced it internally.
Their agent workloads led to different designs. We compare Pando, Scion and newer hosting and review tools, including ways to improve your workflow without changing forges.
blog.invidelabs.com/source-c…

18
Linux TCP flaw CVE-2026-98432: Anthropic reported remote root through an MPTCP listener.
RHEL fixes are out. Ubuntu LTS fixes remain in testing. Disabling MPTCP leaves the kernel bug unresolved.
Patch status and what to check: blog.invidelabs.com/linux-tc…

179
Gemini 4 Carbon tops Artificial Analysis Index v5.0 at 59, ahead of Opus 5.5 at 58 and Argon at 50.
Broader developer access is undated. We compare the benchmarks, pricing and available models to test while waiting.
blog.invidelabs.com/gemini-4…

23
GPT-6.1 Terra halves Sol's token prices. But on Artificial Analysis's index, it used nearly twice the output tokens and cost 44% less per task.
We break down the pricing, safety results and what to check before switching.
blog.invidelabs.com/gpt-6-1-…

1
31
Node2Shell can allow code execution when a Node.js app decompresses untrusted Brotli data, including fetched responses.
Updating Express or Next.js alone won't fix it. Check affected versions, patch Node.js and restart workers.
blog.invidelabs.com/node2she…

56
Updating WordPress or Laravel alone won't fix PHP2Shell.
These PHP engine flaws can let unauthenticated attackers run code. Amazon reports exploitation in the wild.
Our guide covers affected versions, distro backports, containers and worker restarts.
blog.invidelabs.com/php2shel…

1
123
Mistral’s Voxtral 3 adds a voice-agent SDK from $0.04/min with Small 4.
Phone access is enterprise-only, with inbound calls only. Voxtral 2 upgrades also lose word timestamps.
What the SDK handles and what developers still need to build:
blog.invidelabs.com/voxtral-…

18
OpenCode says its Console breach affected 1.4% of Console users, with saved provider API keys potentially exposed.
Users report unexpected bills. We cover how to revoke and replace affected keys, the refund response, and what remains unclear.
blog.invidelabs.com/opencode…

1
63
🏜️ Workation place of the month Oct 2026
📍 Moustache Pushkar - Rajasthan 🇮🇳
Gardens, pool, rooftop views and free Wi-Fi near Pushkar Lake.
✈ Kishangarh Airport (KQH) ~38 km
💸 ~₹3,850 for 7 nights (estimate)

ALT Moustache Pushkar pool

ALT Moustache Pushkar communal lounge

ALT Moustache Pushkar garden

ALT Moustache Pushkar dorm
34
Jev gets experimental image input. Version 1.14 can locate objects in images, but it returns a box even when the object isn’t there.
We cover the presence check, version flags and SDK changes.
blog.invidelabs.com/jev-1-14…

42
Meta's Muse Wonder Full scores 56 on AA's index at Max, versus Opus 5.5's 58 at Max with default fallback.
Full requires Muse Code Power or Maximum. API users get regular Wonder at $4/$20 per million input/output tokens.
Our breakdown: blog.invidelabs.com/meta-mus…

27
What does a coding harness do around the model?
We map the architecture, then use Pi 1.0 to examine tool execution, steering, and context. A runnable test shows how rerunning a failed script can repeat a completed action.
blog.invidelabs.com/coding-h…

Claude Haiku 5.5 cuts prices from $1/$5 to $0.10/$0.50 per million tokens, but only for prompts up to 100K.
Above that: $0.50/$2.50.
Even a short answer to a long prompt pays the higher output rate.
blog.invidelabs.com/claude-h…

13
When everyone is discussing Grok Bot vs Muse vs Dots, we organized a hackathon with experienced engineers to build their own AI Agent/Assistants in just 12 hours.
And many built AI Agents/Assistants to delegate a significant chunk of their work to AI
blog.invidelabs.com/ai-agent…

32