

tinkering | Analytics Grad & Analytics Lead @georgiatech
Philadelphia, PA
Joined March 2026
- Tweets4.2K
- Following180
- Followers611
- Likes29.5K




Pinned Tweet
NEW SOTA DECISION MODEL: SubQ Snap
SubQ Snap absolutely crushed the S1 Bench, beating Jev!! Insane.
1,999 decisions, 0 errors. Macro accuracy 0.825, the best full run the bench has ever recorded. Jev scores 0.775. Mercury Decide, the previous best API model, scores 0.802.
Subset scores: paws 0.940, vitaminc 0.917, boolq 0.910, massive 0.909, aegis2 0.856. Only helpsteer2 lags at 0.416, and that subset drags everyone down. To be fair, none of the other decision models do well on helpsteer2... And it seems to have done better than Jev.
Subquadratic claimed 61.7 vs Jev's 57.9 on their own Decision Index. On an independent battery it is not even that close. It beat its own benchmarks by a lot.
It didn't hit the speed benchmark on my bench but the accuracy more than makes up for it. About a second per decision, and the entire 1,999-question battery cost roughly 3 cents of input tokens, output free. To be fair, I felt it was the fastest but my agent said it was a bit slower. Nevertheless, this is the SOTA decision model.
Hosted API only and still a preview model, so the open questions are weights and what the 384K context does on long inputs. But as a decision model, this is the new bar.
This is my new go to decision model.
Full results: bench.jakecuth.com
subq.ai
VOXEL TEST: Kimi K3.1 Pro spent 3.27M tokens and 17m 29s on the same prompt Kimi K3 finished in 13m 37s with 272k tokens.
Same brief for both: build a 3D voxel diorama of the Battle of Teutoburg Forest with motion and fire.
K3 shipped one single HTML file. Night storm, burning wagons, done.
K3.1 Pro shipped a full app: 3 camera views, a fire intensity slider, its own accessibility pass.
12x the tokens. Was the bigger build worth it, or is the lean single file the better ship?


BENCH LEADERS: SubQ Snap 1.1 still leads text decisions at 0.825 across 1,999 questions, and d3 leads vision at 0.862 across 496.
Text
Snap 1.1: 0.825
Jev 1.14.0: 0.770
Vision
d3 (26B): 0.862
d3-mini (5B): 0.860
d3-flash: 0.845
What moved: the Oct 22 rematch changed nothing at the top. Snap 1.1 matched its preview mark exactly, and Jev 1.14 scored flat against 1.13.
The catch is counting, 0.50 to 0.66 for the whole vision family, and the 5B mini sits one question behind the 26B flagship.
Full boards at bench.jakecuth.com
What should I bench next?

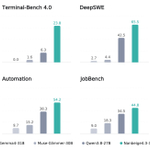
NEW OPEN MODEL: Nanbeige4.3-33B just scored 65.5 on DeepSWE against Qwen3.8-27B's 42.5, the biggest coding-agent gap I have seen at the 30B scale.
It is a 33B dense model on a plain Llama architecture, Apache 2.0 weights out now, with a 512K context window. Nanbeige built it as a teacher first: the plan is to distill its agent skills into smaller models, starting with a 3B.
Numbers from the launch, all vendor-run on the same harness:
DeepSWE 65.5 vs 42.5 for Qwen3.8-27B
Terminal-Bench 2.1 80.9 vs 73.0
Terminal-Bench 4.0 23.8 vs 6.3
It does lose SWE-Bench Pro, 60.3 to 61.7.
The catch: every number here is from Nanbeige's own model card, nothing independent yet, and 33B dense still needs real hardware, about 66 GB in BF16 before quantizing.
At 33B and Apache 2.0, is this the open coding agent you would actually run locally, or does the Qwen ecosystem still win on tooling?
xitter.cf/nanbeige/status/211432…
huggingface.co/Nanbeige/Nanb…


🚀Excited to announce Nanbeige4.3-33B!
To push the performance ceiling of small agents, our strategy in Nanbeige4.3 starts with building a powerful teacher first.
Nanbeige4.3-33B delivers SOTA agentic performance among open models at ~30B parameters:
* Strong results on agentic coding and cowork benchmarks.
* When integrated into mainstream agent harnesses, it tackles real-world tasks with cost-efficient inference.
* It will serve as a teacher for upcoming smaller Nanbeige models, starting with Nanbeige4.3-3B.
huggingface.co/Nanbeige/Nanb…
huggingface.co/Nanbeige/Nanb…
#LLM #Agent

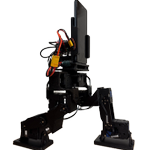
ROBOT BUILD: UCLA's PhoneBot walks, tracks people, and gets back up from a faceplant for about $400 in hardware, using a spare Android phone as its eyes, balance sensor, and brain.
The robot stands 48.3 cm tall and weighs 1.8 kg with the phone in. It has 13 servo joints, six per leg plus one in the torso, so the camera can turn without the feet moving.
The phone runs the vision and the walking policy and sends commands over Wi-Fi, with no electrical connection to the body. Swap the phone, keep the robot. The team tested four Android phones, including a 2017 Honor 9.
The catch: $400 is hardware only, the phone is not included, and the CAD and build files are released CC BY-NC, so noncommercial use only.
At $400 plus a phone already sitting in a drawer, is this cheap enough to make a walking humanoid a weekend build?
phonebot.dev/
xitter.cf/Alacritic_Super/status…


Cuth retweeted

Winner announcement in 24 hours! We'll randomly draw 100 eligible winners with help from @grok. Make sure you follow us, like & repost to be in the running. Good luck! 🍀


NEW OPEN-WEIGHT LEADER: Moonshot's Kimi K3.1 Pro scored 55.1 on the Artificial Analysis Intelligence Index, 4th overall and the best open model, 2.5 points behind Claude Opus 5.5.
It is a post-trained Kimi K3: 2.8T total params, 104B active, 1M context, text and image in. Live now in the Kimi app, Kimi Work, Kimi Code and the API, with a Highspeed version that runs 2 to 3x faster.
Numbers that matter:
Terminal-Bench 4.0: 65.7% from Moonshot, just under Opus 5.5 at 66.4%. Artificial Analysis measured 67% on its own run, up from 13% for K3.
Price: $2 in / $10 out per million tokens. AA puts it at $2.11 per task vs $5.98 for Opus 5.5.
The catch: the weights are not out yet. Moonshot says they land by November 4 and no license has been published, so for now this is an API model, and most launch numbers are still Moonshot's own.
Does an open model this close to the frontier change what you would pay for a closed one?
xitter.cf/Kimi_Moonshot/status/2…
kimi.ai/blog/kimi-k3-1-pro

Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on Kimi.ai, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: platform.kimi.ai
🔗 Tech blog: kimi.ai/blog/kimi-k3-1-pro

Ban alliterated models so only assholes can get them on the dark web and nobody can use them for patching. Genius.
Cuth retweeted
Most impressive thing I’ve ever seen.
I would like to invest my entire net worth in Cognition now
Cuth retweeted

Seriously, this is such an insane release, I did not expect this:
Kimi K3.1 Pro beats every listed US frontier model on 6 of 14 benchmarks in Moonshot’s evaluations.
At $2 per million input tokens and $10 per million output tokens, its standard token rates are 50% below Opus 5.5 ($4/$20 !!) and 80% below GPT-6 Astra ($10/$50!!)
In other words: SOTA much cheaper, local running (with enough compute)


Holy shit: Kimi k3.1 pro is on par or even outperforms Opus 5.5 and GPT-6 astra on key benchmarks!!
They just announced K3.1 Pro, a 2.8T-parameter multimodal model with a 1M-token context window that it claims rivals leading proprietary models in coding and agent tasks, with open weights promised by November 4.
China is back!!


TanStack AI 1.0 is stable: the open-source agent toolkit grew from 4 to 23 provider adapters in under a year, so one codebase can now swap models, frameworks, and sandboxes without a rewrite.
It builds chat, voice, image generation, subagents, computer use, and coding agents like Claude Code and Codex into apps, across 9 UI frameworks and 11 sandbox providers.
Free and open source under MIT, no paid tiers, and the quick start runs in about five minutes.
The catch: the core APIs are stable and production ready, but the new agent harness is still experimental 0.x and can change.
With 23 providers behind one stable API, how much of an agent stack still needs to be tied to one model company?
tanstack.com/blog/tanstack-a…
xitter.cf/tan_stack/status/21135…


TanStack AI 1.0 is officially stable! 🎉
Build chat, voice, image generation, agents, and harnesses into your apps, with your choice of models, UI framework, and infrastructure.
Your AI, your way.
tanstack.com/ai

Wildly misguided take. This is just like when Microsoft used to sue security researchers for reporting bugs. Bad actors will always be able to grab abliterated models off the dark web or strip the guardrails themselves. Banning them from open source just guarantees the good guys can't use them to fight back.
We need bug bounties with massive prizes sponsored at the national and international level.
