
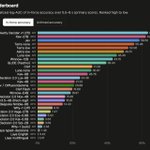
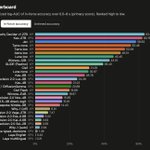

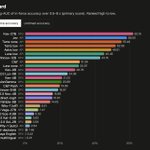
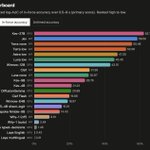
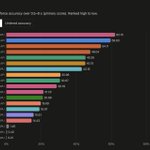


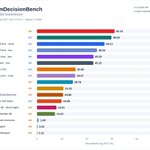
We benchmarked @perplexity_ai’s Perplexity Decider 27B on StreamDecisionBench across voice-controlled presentations, IDE debugging, assembly instructions, and support-call workflows.
Decider ranks #1 on our primary metric, in-force accuracy, with 63.37% normalized log-AUC. Its untimed accuracy is 70.00%.
While the model thinks, new speech, logs, and events keep arriving. The application keeps using its previous decision until a newer response arrives. We measure how often the decision actually in use is correct, including time spent waiting and acting on outdated information.
Explore the results: jacoblincool.github.io/Strea…

A bit more on how we designed SDB.
One thing we spent a lot of time on was task selection. Existing evaluations often reuse LLM benchmarks, but those can mix tasks that should be answered immediately with tasks that genuinely benefit from more reasoning.
For us, speed needed to matter to the task itself. Presenter control, live debugging, assembly coaching, and call assist all sit close to a human in the loop. If a decision arrives seconds late, the user may already have moved on.
We also tried to avoid tasks that reduce to semantic similarity. There are already plenty of benchmarks for clustering, classification, and semantic matching. We were more interested in tasks where following the given rules and instructions actually matters.
At the same time, we wanted the tasks themselves to stay on the fast side. Our operational check was whether a strong frontier model could solve them almost immediately.
Astra does not have a no-reasoning setting, so we used its lowest setting. Across three passes it reached 99.86% mean untimed accuracy. In the original pass it used 773 reported reasoning tokens over 480 requests, about 1.6 per request, effectively answering without deliberation.
That is the kind of task we wanted for SDB. Not necessarily the hardest task, but the right task for decision models, where judgment and speed both matter.
We are still benchmarking new decision models as they come out. Right now we are running @perplexity_ai’s Decider and @fastinoAI’s GLiDE.
More results soon.

If a model is going to make decisions inside a live application, static accuracy is not enough.
StreamDecisionBench evaluates the decision actually in force as the state keeps evolving.
We tested decision models, general LLMs, and open-weight models.
Here’s the leaderboard. 👇

That model was Kev.
We first tested Kev-4B. Its result was promising enough that we went back for Kev-9B and Kev-27B.
Kev-27B reached 62.15 on SDB, the only open-weight model we tested so far in the same range as Jev at 59.63.
Really impressive work, @jaredpalmer.
What should we test next?
We’ll keep adding new APIs and open-weight models to SDB. If we missed one, reply or open an issue.
We’re also looking forward to evaluating OpenAI’s Decisions API once it’s broadly available.
Details + leaderboard + code: jacoblincool.github.io/Strea…
Excited to share that BUILD-AND-FIND has been accepted to #NeurIPS2026!
As agents take on long-term codebase maintenance, working code is only part of the story. We ask whether future agents can recover the intent behind earlier design choices and how much effort that takes.

BUILD-AND-FIND uses a builder and finder protocol. One agent builds a repo, and another recovers the intended design choices.
We measure recovery quality and inspection effort, with the latter reflecting repository-level understandability.
📄 arxiv.org/abs/2605.06136

I've played with WebMCP for the last 3 days, and I think it has huge potential when the browser is directly part of the harness.
But it's clearly an evolving standard. The biggest gap is multimodal resources: it only works with strings.
That's what Hear My Site tries to solve.
The demo uses WebRTC + @CloudflareDev Workers & Durable Objects. Media stays P2P. The server never handles audio or transcripts, only signaling and short-lived credentials.
hear-my-site-meeting-demo.ja…
The core is also open source and available as a framework-agnostic browser package on npm: hear-my-site
Give it browser-owned audio streams and a Gemini or OpenAI live transcription provider, and it exposes live transcripts to agents through WebMCP.
npmjs.com/package/hear-my-si…
Built Agent Trace Privacy Scrubber for #BuildSmall: a local-first Gradio app that sanitizes agent traces before sharing. Secret redaction, optional PII filtering, Modal backend. Built with help from Codex.
Demo: youtu.be/Go2AcwcE72M
Code: github.com/JacobLinCool/Agen…

Trace Field Notes for #BuildSmall: upload a Codex/Claude/Pi Agent log for a field report on where it got stuck, detoured, recovered, or overclaimed. Built with Codex, MiniCPM + Nemotron.
Demo: youtu.be/1QNZlqkl8zo
Code: github.com/JacobLinCool/trac…

Built Hackathon Advisor for #BuildSmall: a live atlas of hackathon Spaces + tiny-model coach for originality gaps.
MiniCPM, llama.cpp, Nemotron ASR, Modal, and Codex helped ship it.
Demo: youtu.be/Gq-FUiL-ZPw
App: build-small-hackathon-hackat…
Code: github.com/JacobLinCool/hack…
Built Lost & Found Desk for #BuildSmall: a caption-first lost-and-found desk for events.
MiniCPM-V captions found items; MiniCPM5 + Nemotron Embed help staff review matches. Codex helped harden deploy/docs/tests.
Demo: youtu.be/AsOM7K0tL-s
Code: github.com/JacobLinCool/Lost…
