

Graduate student in Taiwan. Leader of KohakuLab. Researcher/Dev in ComfyOrg
Taiwan
Joined May 2021
- Tweets3.7K
- Following1K
- Followers4.2K
- Likes29.3K


Pinned Tweet
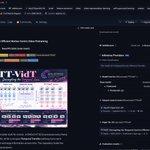
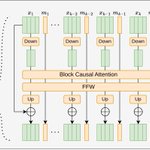
TT-VidT is accepted at #NeurIPS2026 🎉
A temporal-decoupled methodology in video pretraining to provide real "motion" info extracted from the video and only requires small scale training to reach high quality results.
Huge thanks to all collaborators, @NVIDIAAI and @spellbrush

Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75

For those who don't know:
1. This unlock the "nerfed FP32 accumulator" stuff
2. you can rent a A6000/6000 ada to test the mmapeak to know what I'm saying (or check the FP16 accumulation speed of 3090/4090)
3. no unlock core, no overclock, it just remove the nerf
And as this unlock only happen in tensor core:
1. not help mining, not help gaming
2. only help AI usage (potentially DLSS but not guranteed)
琥珀青葉@KohakuLab retweeted
Confirmed that 3090 unlock is successful
with 360watt power wall, I got 75T -> 135T (measured in Pytorch)
Which is insane
I used github.com/Zagitta/gpu-unloc… with commit a9b0c75

琥珀青葉@KohakuLab retweeted

Something exciting is coming. 👀✨
We've been working on an anime-focused 2B pretrained DINOv3 model!
Our internal evaluations show promising improvements across a wide range of anime-related downstream tasks.
We're now making the preparations for release.
Stay tuned! 🚀


琥珀青葉@KohakuLab retweeted
I made FP16 fixed version of MOSS-image
It support any FP16 compute card (such as V100/2080ti) without any issue. and if your lora or PEFT model only trained QKVO/MLP layers, it can be used directly without issue!
huggingface.co/KBlueLeaf/MOS…


KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***

I made FP16 fixed version of MOSS-image
It support any FP16 compute card (such as V100/2080ti) without any issue. and if your lora or PEFT model only trained QKVO/MLP layers, it can be used directly without issue!
huggingface.co/KBlueLeaf/MOS…
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
琥珀青葉@KohakuLab retweeted
The style lora test on Moss-image-base
with 100step only

KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
The style lora test on Moss-image-base
with 100step only
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
琥珀青葉@KohakuLab retweeted
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***
KohakuTPU's new compute unit successfully make the attention MFU improved to around 40% (from 28%) with less LUT, less BRAM and less DSP, but also slightly less flexibility (as it is row wise operation unit)
but as most nn never need ability beyond the sru I guess it is fine...
Finally I will target 24 matrix core + 8vector core
The MFU number above is 16 + 8 so 24+8 may have lower MFU.
And as the RV64IMA cpu I have support OS, I will implement KohakuAccel OS as well!
The design have tinygrad support, have its own DSL and IR/Copmiler.
If you have interests, plz check: github.com/KohakuBlueleaf/Ko…
