

@LambdaAPI
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- Web
Account-level information from X, not a live location or the device used for a specific post.
The Superintelligence Cloud
San Francisco, CA
Joined July 2012
- Tweets2K
- Following249
- Followers21.1K
- Likes2K


Pinned Tweet
AI infrastructure is the largest industrial buildout of our lifetime. Lambda is assembling the leadership team to match the opportunity ahead.
Today, Lambda welcomes global infrastructure operator Michel Combes as CEO and former AT&T Communications CEO John Donovan as Chairman of the Board.
Co-founder Stephen Balaban takes on the CTO role full-time, shaping the technology that will define the next decade of AI compute.
Read the exclusive from @business: bloomberg.com/news/articles/…

Lambda retweeted

NVIDIA introduces the OpenShell Reference Architecture to help businesses run AI agents under control.
The open design combines accelerated compute for agents with hardware-isolated security for deployment at scale.
Announced at GTC Berlin: nvda.ws/4zBujkE

Lambda retweeted

Scale AI securely across global infrastructure while maintaining full control of your models and data.
At #NVIDIAGTC Berlin, we’re introducing Confidential Bare Metal with NVIDIA Confidential Computing, enabling model builders to run sensitive AI workloads on dedicated third-party infrastructure securely.
@googlecloud is extending Confidential Bare Metal support to A4X Max instances, and @cohere plans to integrate it into Cohere Model Vault. ➡️ nvda.ws/4ixVneZ

ALT NVIDIA Confidential Computing Expands, Enabling Frontier Model Builders to Securely Scale Across Global Infrastructure
Featured in the #NVIDIAGTC Berlin keynote: 19 NVIDIA HGX B200 nodes running in the power budget of 16 with NVIDIA DSX MaxLPS. We're glad we got to build this proof of concept with @NVIDIA.


That's Lambda in the NVIDIA GTC Berlin keynote.
We're building with @NVIDIA on secure, efficient AI infrastructure, including an NVIDIA DSX MaxLPS proof of concept, plus support for Confidential Bare Metal and the NVIDIA OpenShell Reference Architecture.
#NVIDIAGTC


Find us at booth 7022 all week. Book a time with the team: lambda.ai/gtc-berlin-book-a-…


Heading to @stacresearch Summit NYC on Oct 21? Lambda's a platinum sponsor this year.
Catch Jessica Nicholson and Devina Jain at 10:20 a.m. for "FSI at Lambda: research at the edge, performance in production." Then Quinn Kennedy gives the five-minute version of how Lambda got here at 2:25 p.m.
We'll have our audited STAC-AI LANG6 results with us. Find us between sessions.
Book time with the team: lambda.ai/stac-ny-book-a-mee…


Three weeks of Build-a-Claw hackathons across Europe, and today the winners took the stage in Berlin.
Congrats to Sebastian Kwiedor and HOAIclaw, an AI advisor for German SMEs that keeps company data local and completed 3,200+ scheduled jobs with zero failures in production.
And to Pasha Abdulaev and Kautionskralle, which helps German renters recover their deposits by tracking deadlines and drafting objection letters.
We’re glad to support a community building with agents, open models, and physical AI.

Moving from prototype to production? Lambda is at @NVIDIA GTC Berlin 2026, booth 7022.
Our team is there all week to talk about scaling compute infrastructure for ML workloads. If you're working through capacity, deployment, or production-readiness decisions, book a time with us.
lambda.ai/gtc-berlin-book-a-…

Lambda retweeted

🚀 Introducing Next-Concept Modeling (NCM): our new paradigm for fast, parallel, coarse-to-fine text generation.
Compared to strong diffusion language models (DLMs) at similar parameter size, NCM achieves:
⚡ Up to 31× faster generation on downstream tasks like summarization and machine translation with comparable or better quality.
🏎️ 10–21× faster unconditional generation across TinyStories, LM1B, and OpenWebText, with comparable or better generative perplexity and using 3–5× fewer training tokens.
🧩 Better performance on reasoning tasks like Sudoku, outperforming both AR and diffusion baselines with fewer sampling steps.
With @ishanskhare, @IddahMlauzi, @ekellbuch, @simran_s_arora, @Azaliamirh, and @HazyResearch.
More details in the thread 🧵👇
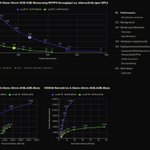
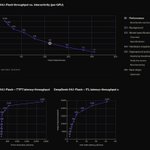
Nemotron 3.5 Super VL is the latest open model from @NVIDIA with vision built in natively (120B total, 12B active per token, 1M-token context, text + image + document + GUI + video input).
We benchmarked both deployment paths on Lambda with @sglang_proj:
* NVFP4 on 1× NVIDIA Blackwell GPU, 1,860 tok/s peak (C16), 587 tok/s/user (C1)
* BF16 on 2× NVIDIA Blackwell GPUs, 1,669 tok/s peak (C16), 530 tok/s/user (C1)
One NVIDIA Blackwell GPU at NVFP4 out-throughputs two NVIDIA Blackwell GPUs at BF16 on the same 8,192-in / 1,024-out workload, roughly 2.2× the per-GPU throughput, because Blackwell runs FP4 natively.
Both deployments run speculative decoding with multi-token prediction (EAGLE, 5 steps, 6 draft tokens).
Model card and full deployment instructions at lambda.ai/inference-models/n…


Lambda retweeted
Today, we’re open sourcing the full NVIDIA Run:ai platform as part of the NVIDIA DSX AI Factory Platform.
Developers, platform teams, and partners can build on production-grade AI workloads and GPU orchestration to improve GPU utilization, increase workload throughput, and bring AI factory solutions to market faster.
Deploy the integrated NVIDIA Run:ai platform or adopt individual components to fit your needs.
See what’s included, how to get started, and how to contribute: nvda.ws/4hRTubt

ALT NVIDIA Run:ai Is Now Open Source as Part of NVIDIA DSX AI Factory Platform
NVIDIA just open-sourced Run:ai. Good news if you'd rather not be locked into one way of scheduling GPUs.
Run:ai is one of several orchestrators you can run on Lambda, alongside Slurm, Kubernetes, and SkyPilot. You pick how to allocate and share your GPUs. We keep them healthy underneath, node-level auto-remediation ships in Lambda Kubernetes Service today.
We've supported Run:ai on Lambda since 2022. Open source makes it easier to package, test, and keep it current as a managed option.
Read more: lambda.ai/blog/runai-on-lamb…


Today, we’re open sourcing the full NVIDIA Run:ai platform as part of the NVIDIA DSX AI Factory Platform.
Developers, platform teams, and partners can build on production-grade AI workloads and GPU orchestration to improve GPU utilization, increase workload throughput, and bring AI factory solutions to market faster.
Deploy the integrated NVIDIA Run:ai platform or adopt individual components to fit your needs.
See what’s included, how to get started, and how to contribute: nvda.ws/4hRTubt
ALT NVIDIA Run:ai Is Now Open Source as Part of NVIDIA DSX AI Factory Platform