

Local AI - Software Engineer - (https://xitter.cf/t.co/B1ewJUrT6s) - ([email protected]) - مهندس برمجيات
vmbr0
Joined December 2020
- Tweets3.2K
- Following987
- Followers1.3K
- Likes1.5K




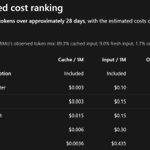


glm5.3-flash and deepseek4.1-flash-1017 are currently the best value for the money considering their intelligence ranking and price strictly thru openrouter.
literally.


interesting

VideoJev-4B brings direct decision-making to video understanding. Qwen3.5-4B based video decision model for temporal grounding and multiple-choice video QA.
🤖 modelscope.ai/models/MCG-NJU…
📄 modelscope.ai/papers/2610.18…
🏆 Video QA leader at its scale: Ranks #1 among sub-6B models on LVBench, Video-MME, LongVideoBench, and MLVU.
⚡ Direct decisions, not long generations: Scores candidate answers and time spans directly, making video QA and event localization easier to integrate into workflows.
🎬 Find the moment, pick the answer: Locates when an event occurs in video and answers multiple-choice questions with calibrated probabilities.
🧠 Long-video ready: Supports up to 256K context in the official video QA evaluation setup.
🛠️ Ready for local use: Released with BF16 weights, training and evaluation code, plus a quick-start demo.
📜 Apache 2.0.


Le TechLead🔰 retweeted

Lots of unjustified hype around DeepSeek DeepInfer. Let me tell you why you shouldn't waste your time on it: 1/n 🧵
- It only targets V4.1‑Flash, not even DeepSeek V3, V3.2 or V4.0. Supporting Qwen and other models also needs a full model and kernel port.

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4


i wish strata stuck with qw3.8-flash and just got better and better, that would have been better than spreading itself thin by supporting other miserable models like 3.6 which made it not only not sustain its good performance (.1.43) but actually degrades.
yesterday i a/b tested 0.2 beta against .1.43 and it was sad
sticking to 43


whether your priority is cost or speed, you have pretty good options
im leaning into haiku now, of all models hahahahaha


i analyzed the cost of 10m tokens consumption from api providers of comparable cheap but smart models.
ranked:
1- deepseek4.1-1017 on deepinfra thru openrouter
2- haiku5.5 !!!
3- direct deepseek api
4- xiaomi mimo v2.6-pro ♥

ds4.1-1017 jump is wow
but man mimo-v2.6-pro is HOT🔥
also i dont know based on what @ArtificialAnlys gets the cost numbers but qw3.8-flash is definitely the cheapest of them all thru the qwen-token-plan and not costly as this graph shows, that's from my experience. speed of qw3.8-flash though is definitely not on par with the others i must confess, mimo is so fast.
btw ds4.1-1017 pricing thru openrouter (not the official api as in this graph) is often 50% cheaper!!
my next main provider (within a week) might be either mimo or that, UNLESS qw4-flash comes out and cause an earth quake with the intelligence/cost ratio which is highly likely tbh.


