
A postdoc at @imperialcollege, working on NLP and Language Models. | Prev @AlibabaGroup @IP_Paris_ @Inria_Saclay
Paris
Joined May 2019
- Tweets18
- Following95
- Followers45
- Likes37

Lihu Chen retweeted

To learn more:
Website: agentcoma.github.io
Preprint: arxiv.org/abs/2508.19988
A big thanks to my brilliant coauthors @LihuChen, @ana_brrr, @_joestacey_, @srahmanidashti and @MarekRei!
Note: We welcome submissions to the #AgentCoMa leaderboard from researchers 🚀
Thanks for having me. Hope to see you in Paris😁

Our invited speaker @LihuChen from @imperialcollege led the team meeting this week! He presented his research on
"Exploring Factuality and Interpretability in LLMs: Confidence Estimation and Key Neuron Analysis". Thanks for your insightful presentation!

2
260
Lihu Chen retweeted

Mitigating racial bias from LLMs is a lot easier than removing it from humans!
Can’t believe this happened at the best AI conference @NeurIPSConf
We have ethical reviews for authors, but missed it for invited speakers? 😡

Lihu Chen retweeted

Congratulations @LihuChen for your awesome paper identifying query-relevant neurons in LLMs for long form texts!
The paper is accepted at AAAI 2025
arxiv.org/abs/2406.10868

📢 Exciting News! 📢
I'm thrilled to announce that our paper, "Identifying Query-Relevant Neurons in Large Language Models for Long-Form Texts," has been accepted to AAAI 2025! 🎉
📄 paper: lnkd.in/gn3NFuHN
💻 code: lnkd.in/ghW97C7F
#AAAI2025

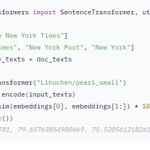
🚀 I'm happy to share that our lightweight model on HuggingFace, PEARL, has reached 10K downloads per month!
PEARL is a lightweight model that can create powerful embeddings for short text tasks, give it a try!
huggingface.co/Lihuchen/pear…

1
68
Lihu Chen retweeted

Here is a little 🧵 about our new #EMNLP2024 paper!
arxiv.org/pdf/2305.13214
In this paper we use LLM-generated facts as atoms in atomic inference systems (for NLI).
So first of all, what is atomic inference, and why should you care about it?

Lihu Chen retweeted

🎉 Exciting Opportunity for Students working on KGs and Generative AI! 🎉
GenAIK is excited to announce that @nfdi4ds is providing €2000 in travel grants (€1000 each) for two students to attend GenAIK2025! Submission deadline: Nov 5, 2024.
Website: genetasefa.github.io/GenAIK2…
Happy to share that our work "Reconfidencing LLMs from the Grouping Loss Perspective" is accepted by #EMNLP2024 Findings! 🚀
A key takeaway: existing LLM uncertainty methods are biased against certain groups, like specific nationalities.
Preprint: arxiv.org/abs/2402.04957

Lihu Chen retweeted

The Role of Small Language Models in the LLM Era
Something a lot of AI researchers and devs wonder about is how can small language models (SLMs) be used.
This paper address this question in a systematic way by closely examining the relationship between LLMs and SLMs.
Common applications of SLMs include data curation, training stronger models, efficient inference, evaluators, retrievers, and much more.
Include great insights for practitioners to better understand the value of these SLMs.

Lihu Chen retweeted
🔊Workshop on “Generative AI and Knowledge Graphs (GenAIK)” will be co-located with COLING 2025, in Abu Dhabi, UAE. Call for papers is now open!
genetasefa.github.io/GenAIK2…
#GenAI #knowledgegraphs #COLING2025!
@GenAsefa @em_alam @lysander07 @heikopaulheim @albertmeronyo @LihuChen
Lihu Chen retweeted

We built a super tough benchmark to test whether models can browse the web to correctly attribute scientific claims.
The GPT-4o-powered agent gets 35%.
Also- the first author is my brother
@_jasonwei + @JerryWeiAI: we're coming for you 🤠


Lihu Chen retweeted
✨ embedder for short strings, useful for table string entries (string matching, entity linking or clustering, fuzzy join) 🤖
huggingface.co/Lihuchen/pear…
Adds to transformer models a character-level model and a model of the phrase type. Yet very lightweight (33.4M or 109M params)
👇

📢📢 If you require semantic similarity computation for strings, our PEARL model might be useful.
It offers powerful embeddings suitable for tasks like string matching, entity retrieval, and fuzzy join.
📕paper: arxiv.org/pdf/2401.10407.pdf (EACL)
🤗model: huggingface.co/Lihuchen/pear…

1
125
Lihu Chen retweeted

A recent LLM hallucination benchmark is making rounds, and people are jumping to conclusions based on a table screenshot. The eval is so problematic in many ways. In fact, a trivial baseline can achieve 0% on hallucination. I cannot help but don my Peer Reviewer hat:
- The study only evaluates "factual consistency" of the summary against the original article, but NOT the quality of summary itself. Here's a trivial baseline that will always achieve 100% factuality: a model that simply copies a few sentences from the article. No hallucination at all.
This is similar to the well-known Helpfulness vs Safety tradeoff. A model that's 100% safe will reply "sorry I cannot help" to all requests. It's meaningless.
- The evaluation relies on using another "judge LLM" to decide whether hallucination occurs or not, but the README contains very little detail about (1) how the judge is prompted and (2) how well it truly captures fallacies.
Does it just spit out a single binary answer "right/wrong"?
Or does it perform a more nuanced reasoning of which fact is being hallucinated, and why?
What are the rules?
How well is it aligned with humans, and when does it not align?
How is hallucination even defined in this protocol?!
For example, let's say the model injects some extraneous but true facts. The article only mentions "Paris", but the model says "Paris, capital of France". Does that count as hallucination?
- In fact, the study might even penalize models that give better summary, because they tend to paraphrase and distill more. That makes the Judge's job very difficult. Bad LLMs will simply copy stuff, and are somehow much easier to score.
- This is reminiscent of the retracted MIT paper that uses GPT-4 to score its own response on math problems, and then makes very clickbaiting conclusions like "GPT-4 is on par with MIT undergrad students".
Please, ALWAYS read the evaluation protocol before jumping to conclusions. This holds universally true for LLM tasks and any other ML systems.
Source: github.com/vectara/hallucina…

Lihu Chen retweeted
🎉📜#EMNLP findings: The locality and symmetry of positional encodings, for language models.
We show that what matters in positional encodings is their locality and symmetry.
openreview.net/forum?id=6c2s…
These are important when accounting for position in language models
1/4


Lihu Chen retweeted

4 - Lihu Chen showcased AcroBERT 🔠, a model that disambiguates acronyms. If you have that friend that tries to sound smart by throwing a bunch of acronyms in the conversation, you can check out the demo and break them down
▶️ huggingface.co/spaces/Lihuch…

