
CS PhD student @Stanford advised by @tengyuma & @tatsu_hashimoto. Former CS and Math undergraduate @Harvard. Website: https://xitter.cf/t.co/zDpmBGVhkR
Joined July 2023
- Tweets218
- Following376
- Followers1.2K
- Likes832




Pinned Tweet
Self-play led to superhuman Go performance, why hasn’t it for LLMs?
In practice, long run self-play plateaus like RL. We study why this happens, and build a self-play algorithm that scales better. It solves as many problems with a 7B model as the pass@4 of a model 100x bigger.
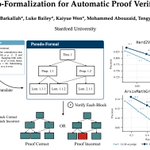
AI-generated proofs are abundant. We need better ways to scale (1) verification and (2) human understanding.
So we’ve updated our Pseudo-Formalization paper with a new benchmark for frontier math proof verification and are releasing Pseudo-Formal versions of the OAI math dump.

Finally, we find Pseudo-Formal proofs easier to read and understand than AI written proofs. You can explore Pseudo-Formalizations of openai/math proofs at pseudoformalization.github.i…. Below is the no Siegel zeros proof pseudo-formalized.

Thanks to the great collaborators on this project @Slim77235, @wen_kaiyue, Mohammed Abouzaid, and @tengyuma.
Luke Bailey retweeted

Some papers on stabilizing LLM rl with PPO:
- SAO (GLM team): arxiv.org/abs/2607.07508
- Best Practice Critic Optimization: arxiv.org/pdf/2608.23566
- EasyPPO: arxiv.org/pdf/2609.36802
Some recent approaches to training critics without an explicit value head:
- TEMPO (from xiaohongshu): studio.dots.ai/dots/tempo-bl…
- AC2: arxiv.org/pdf/2609.39247v2

Luke Bailey retweeted

AI-generated scientific output is scaling beyond available human review capacity. Scaling scientific discovery requires scaling verification.
We introduce OSVerify, a framework for one-sided verification: rejecting as many invalid solutions as possible while preserving rare valid ones for expert review.
We used OSVerify to referee 11 recent OpenAI math preprints, identifying 5 major and 13 minor issues, all verified by human experts.
Our key insight: checking a proposed error can be easier than judging an entire solution. Instead of directly judging solution correctness, OSVerify decouples verification into error proposal (searching for potential errors) and error validation (checking whether they are real and substantial).
On competition and research mathematical benchmarks, OSVerify reduces invalid solutions requiring expert review by 46% on average compared to voting under the same low-FNR constraint, or 57% with an RL-trained validator.
Verification can also guide discovery. OSVerify can be integrated into existing scientific discovery workflows. Paired with an agentic math solver, it helped resolve 3 open conjectures in the Langlands program and contributed to resolving the Manin constant conjecture. All proofs were confirmed by mathematicians.
Our broader goal is to provide verification-based evaluation signals for scientific discovery, enabling test-time scaling and self-improvement even when reliable automatic evaluators are unavailable.
Project: osverify.github.io/
Paper: osverify.github.io/assets/pa…
GitHub: github.com/OSVerify
[1/n]

Luke Bailey retweeted
Awesome class

Deep learning is often taught as a sanitized collection of facts and math. But work at the frontier of AI is messy and empirical.
Our new class, Deep Learning Alchemy, aims to teach the art and science of deep learning in the hands-on spirit of Language Modeling From Scratch.
Students build intuition by running experiments on small LMs, then test it through prediction quizzes: given an unseen code diff, can you predict what happens?
deep-learning-alchemy.github…
My co-instructor @kothasuhas and I think there's significant demand for classes that treat students as serious learners who want to be assessed for what they’ve learned, and so we're trying a new exam-heavy approach to the class (7 exams, 85% of the grade, with the remaining 15% in-person discussion assessments).
We’ve designed the class so students can use AI agents to run their experiments and do their assignment, but they then have to demonstrate that mastery on exams without access to the assignment, and any partial credit on the exam has to come through citations to the assignment, incentivizing them to know what’s in their write-up.
The same assignments and quizzes are public for anyone to try (lecture recordings will be released through @StanfordOnline with some delay). We have some very fun assignments and quizzes covering both classic topics (like NQM, run-to-run stochasticity, and scaling laws) and new and timely topics like muP or hyperball. Made by some real experts like @TristanThrush and @wen_kaiyue
Try some quizzes below!

Luke Bailey retweeted

Deep learning is often taught as a sanitized collection of facts and math. But work at the frontier of AI is messy and empirical.
Our new class, Deep Learning Alchemy, aims to teach the art and science of deep learning in the hands-on spirit of Language Modeling From Scratch.
Students build intuition by running experiments on small LMs, then test it through prediction quizzes: given an unseen code diff, can you predict what happens?
deep-learning-alchemy.github…
My co-instructor @kothasuhas and I think there's significant demand for classes that treat students as serious learners who want to be assessed for what they’ve learned, and so we're trying a new exam-heavy approach to the class (7 exams, 85% of the grade, with the remaining 15% in-person discussion assessments).
We’ve designed the class so students can use AI agents to run their experiments and do their assignment, but they then have to demonstrate that mastery on exams without access to the assignment, and any partial credit on the exam has to come through citations to the assignment, incentivizing them to know what’s in their write-up.
The same assignments and quizzes are public for anyone to try (lecture recordings will be released through @StanfordOnline with some delay). We have some very fun assignments and quizzes covering both classic topics (like NQM, run-to-run stochasticity, and scaling laws) and new and timely topics like muP or hyperball. Made by some real experts like @TristanThrush and @wen_kaiyue
Try some quizzes below!
Luke Bailey retweeted

Which optimizer is best? It turns out the answer can change with batch size!
We perform a comprehensive sweep and find the best BSZ scaling rule depends on settings and can't be derived from early theories like SDE or convex bound!
Luke Bailey retweeted

I've been thinking a lot about making robot learning scalable. To me, that means learning on the job, and using the human help still needed efficiently.
In Mulligan ⛳️, we focus each data-collection round on the initial states where the robot fails. This happens in deployment, with the robot doing the task and a person stepping in when needed.
On 3 real tasks and 2,550 blind evals, it improves on uniform collection at the same budget.
I wish more AI papers could be as thorough in their evaluation as this one! Lars spent many a long night running countless evals to show that, without a doubt, Mulligan is a great method

I've been thinking a lot about making robot learning scalable. To me, that means learning on the job, and using the human help still needed efficiently.
In Mulligan ⛳️, we focus each data-collection round on the initial states where the robot fails. This happens in deployment, with the robot doing the task and a person stepping in when needed.
On 3 real tasks and 2,550 blind evals, it improves on uniform collection at the same budget.
This is such an awesome paper. A beautiful way to measure information from an oracle, here ingeniously applied to test AI research ideation. There is a whole host of other things priced guidance can be applied to which people should explore!

Luke Bailey retweeted

Can LLMs generate novel research ideas? We propose Priced Guidance to quantify this via compression!
We lower bound P(LLM forecasts a future paper’s idea X). Instead of sampling ideas until X is matched, the LLM plays “20 Questions” to recover X, charging each hint by surprisal.

Luke Bailey retweeted
Always thought GRPO-style RL can't be optimal. With billions going into self-play & RSI, the underlying RL methods need to be efficient.
Very exciting project 🔥:
1. Using critics to supervise policy
2. Exploiting easy resets for LLMs
3. Sharing params between Q & policy
