


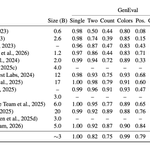

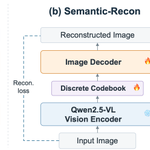
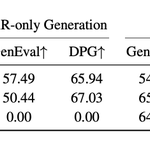


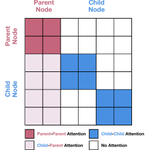
We build a hierarchy in semantic space: text → semantic → pixel. AR learns what to draw; diffusion learns how to draw it.
Like LLMs: pretrain for knowledge, post-train for behavior.
Know, then Draw: A New Learning Paradigm for Visual Generation 🧵
arxiv.org/abs/2610.37626


[8/n] This work was done during my internship at @AdobeResearch
Huge thanks to my amazing mentors @hanwenjiang1 @HaoTan5 @ChongjianG30781 and my advisor Zhuowen Tu
Yucheng Mao retweeted

[1/n] 作为这场训练“投毒”事件最直接的受害者,2024年那几个月漫长的训练排查、对峙与质疑,对我而言是一段炼狱般的经历,也是一场对意志和技术的锤炼。
感谢好友们最艰难的时候支持陪伴。也感谢当时所有并肩作战的同事们。

Yucheng Mao retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Yucheng Mao retweeted

How to scale long-horizon agentic RL Envs? 🤔
We introduce Tev-Gym: 1,170 envs with dense progress rewards. Trained on it:
🔥 Tev-27B matches GPT-6 Astra & Claude Opus 5 on ALE-CM (computing and math domains) at Pass@5.
🚀 Tev-320B tops open models on Terminal-Bench 4.0-CM at Pass@1, only 0.02 behind GPT 5.6 sol.
(1/n)
#RSI #RL #RLEnv
Yucheng Mao retweeted

Video-Index 1.1 comes! Happy to see agentic video understanding reach higher accuracy with far less context. Letting the model decide what to watch beats feeding it 512 fixed frames. What is the next vision task that is still hard for agents? 🤔

New Blog: Towards the Agentic Era of Video Understanding
For complex tasks, agents have become the default. Nobody uses chat mode for that work anymore: people hand it to Claude Code, Codex or Antigravity (yes sometimes🤣), which open files, run commands and check their own results. We think video understanding should benefit from this too.
So we are releasing Video-Index 1.1 with an agentic evaluation setup (which should be by default!). more in the threads🧵

Yucheng Mao retweeted

We put FLUX 3's native layout control to the test on OverLayBench, our benchmark for layout-to-image generation with dense overlaps. The results blew us away. 🔥 On our hardest split, @bfl_ai's FLUX 3 Image Klein hits 54.94 O-mIoU vs. 37.82 for the previous best (+17.12).


Yucheng Mao retweeted

What’s missing from robot foundation models? An explicit understanding of WHY motions work: why move in this direction, why place the object in this way, how hard to grasp the object. This motion-level reasoning bridges instructions to actions—and provides knowledge that can generalize across embodiments and scenes.
Pure behavior cloning supervises WHAT actions to take, but leaves models to infer WHY those actions work. This becomes especially limiting when learning from large-scale heterogeneous data, including egocentric human data, where humans and robots can take very different actions to achieve the same physical effect. We need models to extract the intent behind those motions, rather than simply recite them. Why leave that knowledge buried in trajectories when we can teach it explicitly?
Introducing EgoLAP: a shared language for human and robot motion. Language actions teach HOW to move; motion-level reasoning teaches WHY the motion works. Together, they unlock, to our knowledge, unprecedented gains in zero-shot performance for robot foundation models without additional robot demonstrations.
arxiv.org/abs/2610.08726
ego-lap.github.io/
I've long believed hierarchical representations are one of the most promising paths forward for vision problem. QuadTok is our first step: a tokenizer for adaptive image representation and generation.
Paper: arxiv.org/abs/2610.10497
Code: github.com/myc634/QuadTok
Details below.

ALT QuadTok overview. A dog image is reconstructed with 64 to 192 tokens, with orange overlays marking finer tokens. Below are generated images and a supplied quadtree used to guide the spatial layout of a generated bird image.
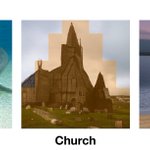
5/6 The tree also acts as a spatial control interface: refine a target region, then generate under that topology. The frozen ImageNet model tends to place the subject there, with no layout-specific fine-tuning. Highlighted regions show the supplied layout.

ALT Zero-shot spatial layout examples for jay, tiger shark, church, breakwater and Indian cobra. Orange regions mark where the supplied quadtree is refined. Generated subjects tend to align with these regions using the frozen ImageNet-trained model.
6/6 An early exploration of spatially grounded hierarchies for vision. Would love to hear your thoughts!
Thanks to the MLPC group at UC San Diego (@mlpcucsd)!