
Building the future of Decision Intelligence.
Joined February 2023
- Tweets29
- Following3
- Followers800
- Likes14




Nolano.ai retweeted

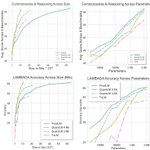
🚀 New Paper: Scaling Laws and Efficient Inference for Ternary Language Models.
Thrilled to share that our work was presented at ACL 2025! We explore ternary LMs (TriLMs), studying their scaling laws and efficiency compared to traditional FloatLMs. 🧵
1/6

Our work has been accepted as a Spotlight (top 5.1%) at ICLR 2025.

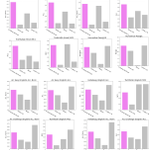
🎉 Thrilled to share that our paper "Surprising effectiveness of pretraining ternary language models at scale" earned a spotlight at #ICLR2024! We dive into Ternary Language Models (TriLMs), systematically studying their training feasibility and scaling laws against FloatLMs.
1/5


Nolano.ai retweeted

A little Xmas present 4 you!🎁🎄🎉 Excited for the first release of our open-source Robin vision-language models built by the team at @irinarish’s @cercaai lab @ @UMontreal as part of our INCITE project tinyurl.com/yc3jzudt. Blog/models/code: tinyurl.com/robinv10 🧵

We are pleased to introduce Hi-NOLIN, the best performing 9B Hindi-English Bilingual LLM.
Blog: blog.nolano.ai/Hi-NOLIN/

At 60% training completion, it is already outperforming BLOOM and Pythia 9B across most Hindi, English and Coding benchmarks and closes the gap to LLaMa on Coding and English tasks.

Help Guide Us What Open Source Model Should We Train Next! docs.google.com/forms/d/e/1F…

1/ Introducing LoRD: Low-Rank Decomposition of Monolingual Code LLMs for one-shot compression.
Paper: arxiv.org/pdf/2309.14021.pdf
7/ Our findings suggest that LoRD is a promising new paradigm for compressing LLMs, offering significant reductions in model parameters without sacrificing model quality or differentiability, and enabling faster inference on modern hardware.