

Opensource and openweight software will dominate the future. The MLX kernel optimization guy.
Joined January 2026
- Tweets737
- Following127
- Followers107
- Likes285


Pinned Tweet
I'm moving all MTPLX and other projects updates to my personal account @TheDavidTai.
Please give it a follow if you want the latest updates on the fastest kernels.
It was recommended I organize my accounts. I'm going to use this account for more formal work related projects going forward.
Watch the absolute carnage in real time:
leaderboard.opensource.wtf/b…
xitter.cf/TheDavidTai/status/208…


Updated mtplx-moe to the latest release. Mostly bug fixes from @Youssofal_'s branch.
github.com/OpenSourceWTF/mtp…

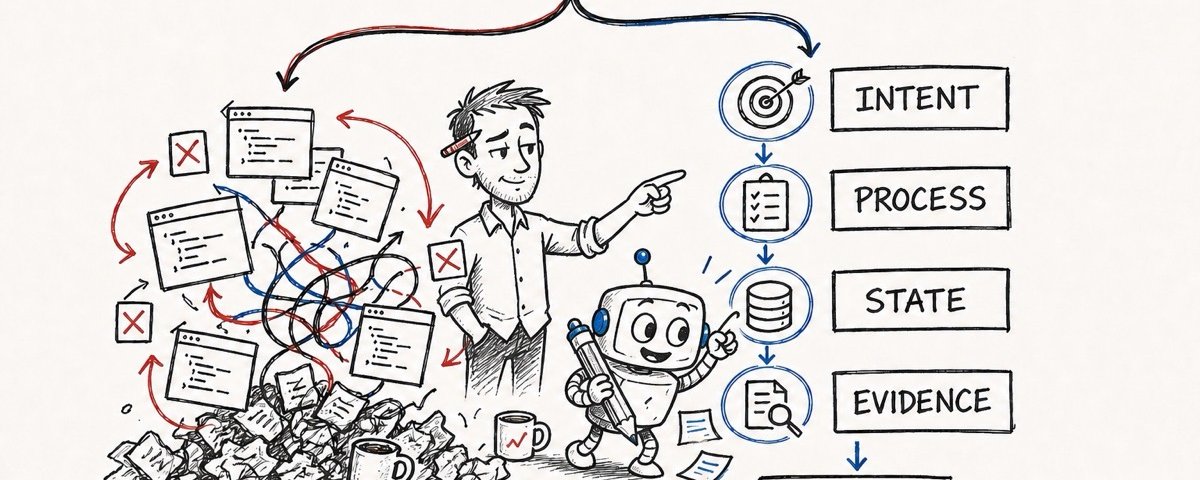
New blog article out, beginning of a series for how to add basic software engineering principles to your vibe coding so you and your friendly LLM partner own the code and not the other way around.
opensource.wtf retweeted

Deepseek 2 sparks 82 tok/s 🤯

🔍 Official DeepSeek-V4-Flash-0731 on 2× DGX Spark
⚡ 82 tok/s peak · 60-72tok/s typical
📈 acceptance 26% → 60% (99% on repetitive)
🎯 1M ctx · NVFP4 KV · TP=2
github.com/tonyd2wild/DeepSe…


There’s always model feel and as opus 5 have shown, more retard strength in pure coding does not necessarily make the model better. However early impressions are good.

Deepseek v4 flash beating GLM 5.2 is profound.
I think we will be a catalyst for x2 DGX spark boxes.
I believe we will see a GLM 5.2.
The age of smart nimble models are upon us.
Luna, @thinkymachines @Zai_org @deepseek_ai
huggingface.co/unsloth/DeepS…

Keep both. I think model reengineering with same shape is going to be more popular due to finishing returns of param maxing. There’s probably going to be some optimal shapes and glm is a reliable model.

Time to wait for unsloth

Official DeepSeek v4 Flash weights are out in @huggingface 🔥🔥🔥
huggingface.co/deepseek-ai/D…

opensource.wtf retweeted

Official DeepSeek v4 Flash weights are out in @huggingface 🔥🔥🔥
huggingface.co/deepseek-ai/D…
TLDR uses 12% fewer tokens and accuracy is mostly hallucination reduction.

DeepSeek V4 Flash 0731 scores 50 on the Artificial Analysis Intelligence Index, a 10-point jump over DeepSeek V4 Flash (released April 2026) that puts it 6 points ahead of DeepSeek V4 Pro. It shares identical architecture and pricing with the earlier DeepSeek V4 Flash, and lands on our Pareto frontier for Intelligence vs Cost per Task
@deepseek_ai’s DeepSeek V4 Flash 0731 is one Intelligence Index point behind GPT-5.6 Luna (max, 51). Even after OpenAI’s 80% price cut on GPT-5.6 Luna today, DeepSeek V4 Flash 0731’s Cost per Task on DeepSeek’s first-party API comes in at ~60% lower than GPT-5.6 Luna (max), a model with comparable intelligence. A key driver of this is DeepSeek’s ~98% cache hit discount on its first-party API, a significantly more aggressive discount than the 90% cache hit discount offered by most of the industry
The new model is a significant step up from the previous generation, DeepSeek V4 Flash (40), and places the model within 1 point of GLM-5.2 (max, 51). It remains 7 points behind the open weights frontier set by Kimi K3 (max, 57). For additional context, this places the model in line with recently released Gemini 3.6 Flash (50) and 1 point behind Muse Spark 1.1 (xhigh, 51). DeepSeek is expected to release the model’s full weights in the coming weeks
DeepSeek V4 Flash 0731 retains a 1M token context window, and its size remains unchanged from DeepSeek V4 Flash at 284B total parameters and 13B active at inference time
Key results:
➤ Improvements in agentic performance: DeepSeek V4 Flash 0731 achieves an Elo rating of 1559 on GDPval-AA v2, our evaluation focused on agentic real-world work tasks, up from 1189 for the previous DeepSeek V4 Flash. Once weights are released this will be the second highest open weights score, behind Kimi K3 (max, 1687) and ahead of GLM-5.2 (max, 1510). Terminal-Bench 2.1 rises 17 points to 79% and τ³-Bench Banking 8 points to 31%
➤ Token usage falls 12% against the predecessor: DeepSeek V4 Flash 0731 used ~206M output tokens to run the Intelligence Index, against ~234M for the previous DeepSeek V4 Flash. The new variant is more token efficient, achieving a higher Intelligence Index with a lower number of total output tokens
➤ DeepSeek V4 Flash 0731 improves over its predecessor on every evaluation in the Intelligence Index: Alongside the agentic gains, CritPt gains 9 points to 17%, SciCode 5 points to 50%, Humanity's Last Exam 5 points to 37%, AA-LCR 3 points to 66% and GPQA Diamond 1 point to 91%
➤ AA-Omniscience improvements are driven by fewer hallucinations, rather than higher accuracy: DeepSeek V4 Flash 0731 achieves an AA-Omniscience Index of -16, a +7 improvement from its predecessor. This improvement is purely driven by a reduced hallucination rate, with overall accuracy (percentage correct) unchanged. Its AA-Omniscience Hallucination Rate is 84%, a 12 point decrease from its predecessor, and comparable to models such as GPT-5.6 Terra (max, 85%) and Mistral Medium 3.5 (82%)
Additional model details:
➤ Context window: 1M tokens (equivalent to DeepSeek V4 Flash)
➤ Size: 284B total parameters (13B active)
➤ Input modalities: Text input and output only
➤ Accessibility: Available through DeepSeek’s first-party API
➤ Pricing: $0.14/$0.28 per 1M input/output tokens, unchanged from DeepSeek V4 Flash. Cache hit price of $0.0028 per 1M tokens, a 98% discount


opensource.wtf retweeted

Hey bro send me any sanitised junk data / failures etc so I can trouble shoot some of the issues and run it through, on any and all models if you can would be a great help for repo !! github.com/Blackwellboy/mode…

opensource.wtf retweeted

3rd place in MLX Fast Laguna XS 2.1 Challenge, but I still have tricks up my sleeve to push my agents even more.
Let's try! 🚀


This is a team effort, runners, kernel optimizers, labs, and training optimizers will all play a part to make good if not great local llm a reality.
I'll be adding DeepSeek v4 to MTPLX this weekend since we have a new version dropping soon. I will also add the 4bit expert streaming version to my MTPLX-MOE branch.
huggingface.co/mlx-community…