

Patronus is a research lab developing training data and simulated environments for frontier AI. https://xitter.cf/t.co/8X6bVgv4RF
San Francisco, CA
Joined July 2023
- Tweets441
- Following220
- Followers2.7K
- Likes828




Pinned Tweet
1/ Today, we are thrilled to announce Generative Simulators, a new class of adaptive, auto-scaling environments for AGI training and evaluation 🤖🧵
Static datasets, hand-authored environments, and human-curated demonstrations do not automatically scale with the learning patterns of the trained model. We propose Generative Simulators as a principled alternative: environments that evolve, evaluate, and adapt to agent behavior over time.
Technical Report: patronus.ai/generative-simul…
Blog: patronus.ai/blog/introducing…

PatronusAI retweeted

RSI is the next frontier in research. But how do we achieve this?
I wrote about the role of data in RSI. Models need to get better at training data attribution, ecologically valid generations, and measuring their own progress. It’s evals all the way down.

We are honored to be named to the #Disruptors60 Class of 2026 curated by @GreenfieldVC at @TechCrunch Disrupt.
Patronus is a research lab developing training data and simulated environments for frontier AI. Our mission is to understand how and why frontier models fail, and to turn those insights into safer, more capable AI.

Last week, 40 of us at Patronus came together in Lyon, France. The team ran workshops, aligned on what’s next, and took excursions through the city and into the French Alps.
We’re hiring across research, engineering and operations in San Francisco. If you want to help decide what frontier models learn next, come build with us.


PatronusAI retweeted
Synthetic data is often dismissed as AI slop. I disagree.
I wrote about how we should approach synthetic data for mid-training and RL, where it currently falls short, and how human expertise can shape far more tasks than experts could write themselves.

We're excited to share that our paper on prompt infilling for dLMs has been accepted to the "Non-Autoregressive Language Models for Fast & Flexible Text Generation" workshop at COLM 2026 🎉
Masked diffusion language models like LLaDA and Dream have bidirectional architectures, yet they can't infer prompts from desired outputs out of the box. We traced this to a training gap: during SFT, prompts are simply never masked. The fix is straightforward. Mask both prompts and responses during SFT (full-sequence masking). That single change unlocks the ability to infer task-adapted prompts from few-shot examples.
Prompt infilling in dLMs just requires the right training approach. We're calling on the community to release full-sequence masked SFT checkpoints alongside standard ones.
Congrats to @akkikiki and Keisuke Sakaguchi!
Paper: arxiv.org/abs/2604.03677
Fine-tuned models: huggingface.co/collections/a…

Meet @DuncanCTech, our SVP of Product and Operations. 👋
Previously, Duncan was Head of Product at @zoox, SVP at @SamaAI, and Product Lead at @Google Play. He was also the creator of Fruit Ninja and Jetpack Joyride.
Fun fact: Duncan loves figuring out how physical things work, so when an appliance breaks at home, he usually takes it apart and fixes it himself 🔧. Handyman 2.0.
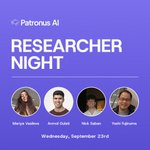
We're hosting a researcher night next Wednesday at our office in SF. Fast-paced spotlight talks on post-training and evaluation. ⚡️
The talks:
@mariyaivasileva on Beliefload: an evaluation of how LLMs formulate and revise hypotheses in light of new evidence, and how they diagnose and repair a broken environment without overwriting the parts that already work.
@Nick_saban20 on GlobeBench: a benchmark for whether language models can faithfully simulate the environments we train agents in.
@AnmolGulati06 on Beyond Rows to Reasoning: an agentic framework for reasoning over and editing enterprise spreadsheets with millions of cells, cross-sheet dependencies, and embedded charts.
@akkikiki on SpeedrunBench: a benchmark that asks not whether an agent can finish a game, but how fast.
Drinks, sushi, merch incoming.


PatronusAI retweeted
True story: our original company name when we were in stealth was Zeno AI, not Patronus AI.
Back in 2023, Rebecca and I started the company on the idea that AI evaluation was like Zeno’s Paradox. Every time models reached the bar we had set, the frontier of what we needed to evaluate moved further ahead.
Fast forward to 2026, I still think Zeno's Paradox is the most accurate way to describe AI progress. Every finish line we draw for AI moves the moment it reaches it.
In the original Zeno's Paradox, every time Achilles reaches where the tortoise stood, the tortoise has moved a little further on, so he appears to chase forever. Mathematically the paradox does resolve. The shrinking gaps sum to a finite length, and Achilles does pass.
In the AI version of the paradox, the idea is that humans are the tortoise, and AI is Achilles. We start far ahead, carrying millions of years of evolutionary and cultural learning. And over the last few years, Achilles has closed most of the visible distance.
But the reason the AI version is more interesting is that the tortoise keeps speeding up. Each time AI closes a gap, it hands the people defining the frontier a better tool for defining the next one. Mathematicians use the newest models to probe harder open problems. Researchers use them to help design the very evals the next generation of models will struggle against.
Everyone is anxious about the rate of progress in AI right now, but ultimately I think we’re going to land in a pretty optimistic place: AI will enable humans to reach farther than ever.
@danshipper has a nice GIF of this tortoise/Achilles setup, see below.
Meet @chaaelaes from our data quality team. 👋
Chelsea was previously at UC Irvine where studied biomedical engineering. She spent time in a neuroscience lab building imaging hardware and researching neurodegenerative diseases.
Fun fact: Chelsea has played the violin since she was 3 years old🎶
Meet Abdelrahman Madkour, from our research team. 👋
Madkour was a previously a Research Scientist at Meta, where he worked on coding benchmarks for coding agents. Before that, he completed his Ph.D. in CS at Northeastern University, where he focused on procedural content generation in games.
Fun fact: Madkour plays the Arabic oud 🪕
Today, we’re releasing SpeedrunBench: the first benchmark that measures how fast agents can beat video games.
We asked frontier models not to simply complete video games, but to speedrun them - across 10 titles like Mario Kart and Pokemon.
On simpler games, agents get close to the human world record. However, on more complicated games like Pokemon Blue, the best models Kimi-K3 and Opus 5 are ~4x off the world record.
Benchmark, paper, and demo below.
Website: speedrunbench.com
Paper: cdn.patronus.ai/SpeedrunBenc…
Blog: speedrunbench.com/blog
Benchmark: huggingface.co/datasets/Patr…
If problems like this are interesting to you, we're hiring: patronus.ai/join
Meet Zhe Li, from our research team. 👋
Previously, Zhe lead post-training at Inflection AI (now Microsoft). Before that, Zhe was a key contributor to FaceID and Apple Vision Pro at Apple. Zhe did his PhD in computer science at the University of Iowa, where he worked on neural network optimization.
Fun fact: Zhe is a naturally curious person and will happily go down a rabbit hole researching the most random things.