

AI, Cloud Native full stack Developer, System Architect.
Joined November 2024
- Tweets621
- Following1.1K
- Followers33
- Likes1.8K




RayTan retweeted

Techartist 用 Opus 5.5 做了本 3D 可视化物理课本《Every Joule》:十课讲完英国中学“能量”单元,免费在线看
覆盖英国 GCSE 物理“能量”整章。GCSE 是英国学生 16 岁左右参加的毕业考试,大致相当于我们的中考。
用 Anthropic 的 Opus 5.5 模型和 Three.js(在网页里画 3D 的开源工具)做的。
iamtechartist.com/every-joul…


RayTan retweeted

Code Review is now generally available for Claude Team and Enterprise plans.
Reviews are now faster, catch more of the bugs that matter, and admins can pick from Quick, Standard, or Deep review levels for each repo.

RayTan retweeted

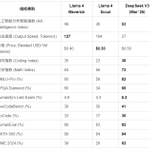
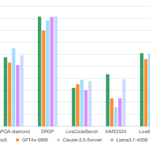
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
🤖 Made with AI

RayTan retweeted

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

RayTan retweeted

Day 1/
We have optimized the default speed to be ~50% faster across GPT-6 Astra and GPT-6.1 Sol through the subscription across all our products and partners using Sign in With ChatGPT (including OpenCode, Pi, Amp, Devin, ...).
No changes needed on your end and this should be felt within the next two hours.

RayTan retweeted
mattpocock/skills prompt of the day:
/codebase-design Take a look in the repo for shallow modules, applying the deletion test and look for candidates for deletion.
Helps kill unnecessary abstractions.

RayTan retweeted

🚨 OpenAI Set to Reveal a Long-Term Agent at DevDay
- Codenamed "Aeon" — built for long-running tasks, similar to Grok Bot or Manus, working for hours, days, even weeks
- Likely built on Astra, already strong at long-horizon work
- Runs in a cloud environment like Cursor — sets everything up remotely and keeps grinding until the task's done
- OpenAI already has the infra (hosted sandboxes, multi-agent workflows) to make this the natural next step
- Rumored to support multiple agents collaborating on the same task — if real, that's a big deal

RayTan retweeted

MiMo-V3 is getting a new architecture. The core of it, HySparse2, is out today.
Less prefill, a smaller KV cache, better long-context retrieval—and we got all three at once.
Compared with MiMo-V2.6's Hybrid SWA architecture:
• 5.02× lower prefill FLOPs at 1M tokens
• 4.5× smaller KV cache at 1M tokens
• Better MRCRv2 and RULER-v2 scores, plus lower AgentPPL and LongPPL
Why build a new architecture?
Agentic inference is a very different workload. Each round, a short action can return a long observation that needs to be prefilled, while the context keeps growing. That puts prefill cost, KV-cache size, and retrieval accuracy on the critical path at the same time.
HySparse2 tackles all three with two levels of KV sharing:
• KV Bridging: Following YOCO, full-attention layers in the cross-decoder build their K/V from self-decoder hidden states.
• KV Reuse: Within each hybrid block, sparse layers reuse the preceding full-attention layer's KV cache and selection indices.
Two more changes: token-level selection replaces block-level selection, and a forced window of recent tokens replaces the separate SWA branch, so local and global tokens share one KV cache. Since all cross-decoder KV caches now come from the self-decoder, prefill can stop once the self-decoder finishes.
Paper: arxiv.org/pdf/2609.26368

RayTan retweeted

Notebook 🤝 @GoogleDocs
With Workspace Intelligence, you can now upload and reference your notebooks as a context source in Docs.
Combine your deep research from Notebook with other sources like your emails, chats, & files to personalize your writing process directly in your draft.

RayTan retweeted

Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
RayTan retweeted
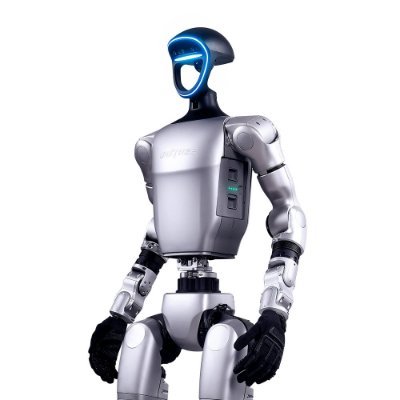
Unitree Introducing: Unitree Dex5-S Dexterous Hand 22 Degrees of Freedom 1:1 Real-Hand Size👋
Precision biomimetic dexterous hand, price from $6.5K (Tax and Shipping cost excluded), with all 22 joints supporting smooth backdrivability, and each joint equipped with limit impact torque protection.
RayTan retweeted

Local Laya moggs Jev at @grok 4.7-built Tetris 🧩
An open-weights System One model called Laya, beat cloud-based Jev at playing Tetris by making decisions 11 times faster, running locally on a 16GB MacBook Air!
Run AI models locally -> atomic.chat

介绍比Jev快50倍,在你设备上跑的laya-mlx!
只在你的设备上占用最高1G内存
Laya是一个开源的类似于Jev的,基于文本输出概率的分类系统
我将其移植到MLX,并且做了一些性能优化!
视频中就是这个模型在我的本地M3Max上玩贪吃蛇
这个模型能够以每秒决策60次的速度玩贪吃蛇!
github.com/mizorewww/laya-ml…
RayTan retweeted

🚨Qwen4家族首次曝光!!
刚刚,在2026年云栖大会的开幕式上,新任@Alibaba_Qwen LLM负责人刘大一恒官宣了即将到来的Qwen4家族!
包含Qwen4-Max
Qwen4-Flash&Qwen4-Plus
还有Qwen4-27B!!!
未来Qwen会训5-10T的模型

RayTan retweeted
MiMo-V2.6: The Hard Road to Scaling Up RL
MiMo-V2.6 is very likely one of the largest single RL runs, by compute, that any open-source model team has undertaken to date. In an era when compute is brutally scarce, we still chose to dedicate a team of several dozen people to one goal over an extended period: scaling up RL. That takes more than research conviction. It takes a vision for AGI, respect for the unknown, and the nerve to walk straight into the hardest problems.
The result is a model whose potential was built through mid-training and unlocked through heavy RL. Today, it is the number one open-source model. I strongly recommend reading the technical report. I believe it will become one of those papers that Agent RL practitioners keep reopening and discovering something new in each time. In my view, the research innovations and engineering challenges behind it surpass those of DeepSeek R1, which I was partly involved in.
Some will ask: why MixRL instead of MOPD? First, they are not competing choices. We ran MixRL on verifiable tasks of moderate difficulty, including code and related agentic tasks, and found that the resulting models generalize remarkably well. Second, tasks that are difficult to verify, extremely long-horizon, or simply too challenging to include in a joint RL run are trained separately. Including them would substantially reduce rollout efficiency or introduce significant rollout staleness. We then merge the resulting capabilities through MOPD. Games, 3D tasks, and tasks with subjective evaluation signals all fall into this category.
There is also a third, slightly cheeky answer. Our team is flat enough and free enough of organizational silos that MixRL simply is not difficult for us. More importantly, everyone enjoys working this way. People from different domains come together every day, driven by the pursuit of AGI and intelligence that can continuously improve itself, to confront and resolve the RL bottlenecks in each field. I will always remember the RL daily update meetings from this period. They were intense and dense, with intelligence emerging in real time.
To help the open-source community focus on solving real Agentic RL problems, we have released a Qwen model distilled from MiMo RL trajectories as a stronger starting point for RL, along with 7K diverse environments and a complete RL training framework. We hope these resources will help move Agentic RL research forward.
MiMo-V2.6 is only the beginning. In an era when intelligence is easy to replicate, we still choose the hard road toward self-improvement and AGI. Much of what lies ahead remains unknown. But we are willing to keep investing the time, compute, and passion required to take on one hard problem after another and work each of them all the way through, until intelligence crosses into a new regime.

RayTan retweeted

连 JEV 的联合创始人 @CompleteSkeptic 都亲自下场转发点赞:这是 JEV 正确的打开方式!
大家在 Claude Code 里写长代码,最恶心的就是上下文一满,系统就卡住 10 秒去写总结小作文
开发者 @tamarajtran 刚刚开源了这个插件:利用 JEV 的打分能力,几十毫秒内精准识别并清空所有没用的终端垃圾与冗余日志
Github:github.com/tamaratran/fast-j…
它的作用是:
• 彻底治好 Agent 失忆症:几千行终端废话和文件内容让 JEV 毫秒级打分,没用的直接扔,核心代码与状态 100% 原样保留
• 彻底消灭卡顿与账单:几十毫秒无感完成瘦身,不花一分钱废话 Token
@typesafeai 的联合创始人 Diogo Almeida 也公开实名认可:这就是编码 Agent 绕过传统 KV 缓存的最佳解法🧐

found the perfect use case for @typesafeai Jev:
instant compaction
in 2026, why is compaction still a summarization prompt?
Jev can make it instant by scoring every tool call and dropping what’s irrelevant

