

https://teapawt.org/t.co/EZvr5QjN9J biggest https://teapawt.org/t.co/Z7II44Tw1W fan ever
GPT-6 Pro ✨
Joined January 2024
- Tweets21.6K
- Following1K
- Followers942
- Likes64.5K






Raphi-2Code retweeted

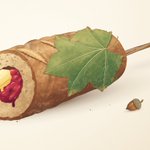
I almost forgot my favourite GPT-6.2-Astra generation - this is SVG (yes SVG!!) of a peacock - no other model came close to the precision, lifelike nature and detail of this generation, incl. Fable


Raphi-2Code retweeted

Some of you have been asking very politely. Some of you have just been asking.
GPT-6.2 Astra and Sol are now available.
Super efficient and built to perform where it counts—the real world.
openai.com/index/introducing…


Raphi-2Code retweeted

Google is working on a GIF feature for Gemini that animates images, following OpenAI's recent GIF launch with Images 2.6.
h/t @Liammagnier7


Raphi-2Code retweeted

It has been 72 days since OpenAI last released a frontier model - officially the longest gap since the wait between GPT-5 to 5.1 (Aug-Nov 2025)
If it doesn’t release in the next few weeks, it would become the longest gap between two OpenAI frontier model releases since o3 to GPT-5 (Apr-Aug 2025)
Raphi-2Code retweeted

Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58
The Coding Agent Index measures models in agent harnesses; v2.1 of the Index upgrades FrontierCode from 1.1 to 2.0 and Terminal-Bench from 4.0 to 4.1.
Upgraded:
➤ FrontierCode-AA 2.0 (replacing FrontierCode v1.1): our implementation of Cognition's FrontierCode 2.0, comprising 132 real-world coding tasks graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench 4.1 (replacing Terminal-Bench 4.0): the same 66 tasks, scored with updated verifiers that improve reliability and resistance to reward hacking
Staying in the Index: SWE-Atlas-QnA-AA
Key results:
➤ Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58: Claude Fable 5.2 scores 58 at both xhigh and high in Claude Code. Claude Opus 5.5 (max) scores 58 in Claude Code and, paired with GPT-6 Luna High, in Cognition's multi-model harness Devin Fusion CLI. Claude Fable 5.2 (max) scores 56 as more of its attempts hit task time limits. Claude Sonnet 5.5 (max, 56) in Claude Code and Gemini 4 Carbon (high, 55) in Antigravity CLI follow
➤ Index scores are lower in v2.1, driven by the upgrade to FrontierCode-AA 2.0: models score lower by 5 points on average. Codex with GPT-6.1 Terra (max) is the only configuration which didn’t fall between versions, sitting within 1 point of its prior score
➤ Cost per task varies ~30x among configurations scoring 48+: from $1.51 for Codex with GPT-6.1 Sol (max, 52) to $44.22 for Claude Code with Claude Fable 5.2 (max, 56)

Raphi-2Code retweeted

META 🔥: Muse-Spark-1.4-internal has been spotted in one of the PRs on Github.
> The PR is a small logging change to RocksDB's experimental "live tuning" feature.
> The mention appears to be in the PR notes, which seem to be auto-generated.
It's expected that Muse Spark 1.4 is in the works and is already used internally at Meta, as it seems.


Raphi-2Code retweeted

Claude Fable 5.2 is live on MineBench.ai, with significant efficiency jumps over Fable 5.1!
- Total Cost (15 builds): $147.55 → $38.08 (-74%)
- Avg Cost / Build: $9.84 → $2.54
- Avg Inference Time: 40m 11s → 12m 55s (3.1x faster)
- Failed Attempts / Retries: 8 → 0 (15/15 one-shotted)
The massive reduction in cost is a result of Fable 5.2's lower API pricing, but also the model requiring zero retries in our harness (15 total generations vs. Fable 5.1's 23).
Raphi-2Code retweeted
Gemini 4 Carbon is now on MineBench.ai :)
- Total Cost: $11.65
- Average Inference Time: 16m 0.9s
Gemini 4 Argon (for reference):
- Total Cost: $9.12
- Average Inference Time: 6m 15.1s
Though its ratings are yet to stablize, it currently overtakes Argon for 2nd place on our leaderboards!
Raphi-2Code retweeted

Looks like it's between Terra and Sonnet until you turn on subsidization

Google's new Gemini 4 Hydrogen has Intelligence just below Claude Sonnet 5.5 and GPT-6.1 Sol, at a third of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol
@GoogleDeepMind has released their third new model in six weeks. Gemini 4 Hydrogen introduces an xhigh reasoning level and scores 54 on the Artificial Analysis Intelligence Index, with strengths in visual reasoning and non-hallucination. This places it 1 point behind Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), at ~32% of Sonnet’s cost but ~2.5x that of GPT-6.1 Sol. With high reasoning, Gemini 4 Hydrogen matches the Intelligence of Gemini 4 Argon for ~19% of the Cost per Task
Key takeaways:
➤ The new xhigh reasoning level scores 54 on the Intelligence Index: xhigh is the first reasoning level above high on a Gemini model, and puts Hydrogen 1 point below Claude Sonnet 5.5 (max) and GPT-6.1 Sol (max), and 4 points ahead of Gemini 4 Argon (high). With default (high) reasoning, Gemini 4 Hydrogen scores 51, just behind GPT-6.1 Sol (xhigh, 52) and Claude Opus 5.5 (high, 52)
➤ Strong visual reasoning, presentation and non-hallucination: On GDP.pdf, a visual reasoning benchmark over long documents, it scores 33% all-pass on medium reasoning, the tied #1 score on the benchmark. On AA-Omniscience, Hydrogen has one of the lowest hallucination rates recorded at 8%, compared with 43% for Claude Sonnet 5.5 (max) and 52% for GPT-6.1 Sol (max). On AA-Briefcase, our agentic knowledge work evaluation, graders rate Hydrogen's presentation above other Gemini models, including Carbon
➤ Weaker on agentic terminal work: Hydrogen scores 54% on Terminal-Bench 4.0 and 50% on Terminal-Bench-Science 0.1, covering agentic coding and scientific research workflows in the terminal. Claude Sonnet 5.5 (max) scores 64% and 53%, and GPT-6.1 Sol (max) scores 56% and 58%. xhigh reasoning helps on the science tasks, lifting Terminal-Bench-Science from 41% at high to 50%, but makes no difference on Terminal-Bench 4.0 (54% at both). Science scores are even across domains, from 46% in earth sciences to 53% in physical sciences
➤ Low cost for its intelligence, with high token use at xhigh: Hydrogen is priced at $1.50/$7.50 per million input/output tokens. At xhigh it costs ~32% as much per task as Claude Sonnet 5.5 (max) for near-equal intelligence, but ~2.5x as much as GPT-6.1 Sol (max). xhigh nearly doubles output tokens compared with high for a 3 point gain in Intelligence, and Cost per Task falls from $3.16 at xhigh to $1.87 at high. Medium ($0.80) and low ($0.29) cost less again, but score 41 and 27 on the Intelligence Index
➤ On the Time per Task vs. Intelligence Pareto frontier: Gemini 4 Hydrogen has an output speed of ~200 output tokens per second. With high, medium, and low reasoning effort, Gemini 4 Hydrogen is on the Time per Task vs. Intelligence Pareto frontier, meaning no models are both more intelligent and have a lower Time per Task
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Reasoning efforts: Gemini 4 Hydrogen offers four reasoning levels (low, medium, high, and xhigh) with xhigh new in this release
➤ Pricing: $1.50/$7.50 per 1M input/output tokens. Cached input tokens receive a 95% discount ($0.075)
Congratulations to the @GoogleDeepMind team on the launch!


