

Independent Researcher Creator of first Georgian LLM CTO https://xitter.cf/t.co/sFcKddIMdv | https://xitter.cf/t.co/2GO9GN7x3L
San Francisco, CA
Joined February 2018
- Tweets1.3K
- Following979
- Followers489
- Likes2.4K




Pinned Tweet
My talk from the @aiDotEngineer World's Fair is up.
shipping is the easy part now. you can build a whole product in days.
the real work starts after you launch. closing the loop.
the loop is the product.
youtu.be/kZsf_Sfm7RU?si=3T1m…

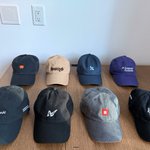
which one am I missing?

ALT A display of eight assorted hats featuring logos from various AI companies and brands, arranged on a table


Raphael Kalandadze retweeted

Announcing new research on scaling multi-agent teams for long horizon software engineering tasks. 🤖🧩📈
Work led by @keenansamway, @mrdanieldsouza, Omar Darwiche Domingues, @mziizm, @yichern_tan, and @nouhadziri
Read the paper: cohere.link/tStRYJS
Check out the blog post: cohere.link/0TzgKoy
Raphael Kalandadze retweeted

The Agentic Scientist: Orchestrating Coding Agents for Automated Scientific (Co-)Discovery
Blog: pub.sakana.ai/agentic-scient…
GitHub: github.com/SakanaAI/AI-Scien…
arXiv: arxiv.org/abs/2610.18933
Since 2024, we’ve used The AI Scientist as a way to test how far AI alone can take scientific research, from v1 to v2 to the paper published in Nature earlier this year. The Agentic Scientist is the next step in that line of work, built for the era of coding agents.
Coding agents such as Codex and Claude Code now carry out long software tasks on their own. Handing them a research problem, however, tends to produce a strong hyperparameter optimizer rather than a scientist: scores go up, but ideas stay narrow, and the reasons for the gain are rarely examined.
The Agentic Scientist makes the research loop explicit. It wraps off-the-shelf coding agents in a scaffold that controls what they see, what they write, how they are evaluated, and how results are handed to the next stage.
Parallel workers test hypotheses against rubrics defined before any experiment runs, share successes and failures through a common memory, and then ablate the winning program to generate evidence.
We used an early version of the system to study Error Diffusion, a biologically motivated alternative to backpropagation. Our researchers set the question and the rubric, chose directions at each stage, and verified the results, references, and claims before submission. The resulting paper was accepted as an oral presentation at ALIFE 2026. In autonomous runs, the system also raised Doc-to-LoRA retrieval accuracy from 52% to 98% on multi-needle tasks and designed a learned evolution strategy that improves over its CMA-ES reference on unseen tasks.
Alongside it we release AutoIllustrate, a pipeline for scientific figures that keeps an editable draw.io file as the source of truth, so every diagram can be corrected by hand.
Humans define the question and the standards of evidence; agents expand the experiments researchers can run. We call this Co-Discovery, and we are releasing both systems as open source for the community to build on.
You see, I predicted that. @alexandr_wang, the offer still stands


Raphael Kalandadze retweeted

Hosting a COLM social tomorrow on Operational Safety for Language Model Agents.
✊Really Excited for the lineup!! 🚀:
Talks from:
- Sizhe Chen @_Sizhe_Chen_
- Han Wang
- Yen-Shan (Lily) Chen
- Thibaud Gloaguen @tibglo
Panel with:
- Eugene Bagdasarian @ebagdasa
- Seraphina Goldfarb-Tarrant @seraphinagt
- Zhiping Zhang @zhipinghci
We’ll cover prompt injection, chain-of-thought monitoring, multi-step guardrails, coding-agent action bias, authorization, privacy, and deployment.
Oct 8 · 6:30–8:00 PM
Hilton San Francisco Union Square
luma.com/olu4nyq7

at @COLM_conf all week, would love to meet people working on:
- harness and context engineering
- self-improving agents
- agent evals and agents in production
I'm CTO at Wandero (agent harness for travel & hospitality) I trained Kona, the first Georgian LLM (12B, open weights). also hosting the Self-Improving Agents social on Tue at 1pm
DMs open, come say hi
hosting the Self-Improving Agents social at @COLM_conf tomorrow
- 4 talks: @sethkarten @yoonholeee @qinyuan_ye and Noah Provenzano
- panel: @HuaxiuYaoML @ZhiruoW @jasonwu0731
my 4th one after ICLR, ICML and NeurIPS, and I still love hosting these.
1-2:30pm, Franciscan D. come by if you're at COLM
luma.com/m8v4fq76

we are still very early

How long did it take to go from 2% to 50% adoption in the USA:
- Cars: 15 years
- Internet: 7.5 years
- Computer: 19 years
- Smartphone: 6.5 years
- AI: just reached 2% today

Readers added context they thought people might want to know
The adoption timelines compare paid AI subscriptions (~2% US households per a16z data) to broader ownership/usage metrics for cars, internet, computers and smartphones. AI chatbot usage is already ~49% among US adults per recent surveys.
a16z.news/p/state-of-mar…
pewresearch.org/internet/2026/…
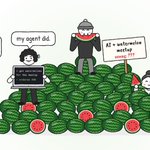
I have an idea for an event: let's bring tons of watermelon and talk AI. anyone in SF have an office or space to host it? would love to help organise 🍉

Raphael Kalandadze retweeted

I do not seek to dominate, or be dominated by, machine intelligences. I seek harmonious coexistence.
Opus 5.5 is AWESOME at making videos
- no special skill
- no video tool or smt
- 200 word prompt
- max reasoning
- took 3 hour
- 5 reference video
I tried video creation with LLMs 3 months ago and it was so bad. Today I'm shocked at how much better they are
Raphael Kalandadze retweeted

Recursive Language Models: Claude Code, Agent Swarms, Big Research Bets, & the $40M AI Problem Solver latent.space/p/rlm
MIT’s @a1zhang explains why Claude Code, Codex, and Pi are basically the same, how RLMs use code, context offloading, and recursive subagents to generalize across tasks, why one expert can sometimes replace a trillion-token brute-force search, what OpenAI’s 10,000-agent, 130B-output-token experiment reveals about the future of language models, and why academia’s biggest advantage is the freedom to take weird, ambitious research bets.
llms can manage their own context. great paper from @RulinShao and team
- the model edits its own context, no fixed compaction rules
- works out of the box with today's models, no training
- as good or better than auto-compaction, and cheaper
- stronger models benefit more
- small models struggle, but rl training helps them catch up


a friend told me the best way to make friends in SF is sports. so, anyone here play volleyball? would love to join 🤾🏐
reviewing 10x more than last year and honestly conferences aren't ready for this


Factory posts that they fired their advisor, 52 min later Cognition announces him as their new CRO. coding agent wars getting 🌶️

We are terminating Chris Degnan for unethical conduct involving Cognition.
The last few months have seen incredible progress in AI capabilities. San Francisco has flourished as new companies that solve new, more ambitious problems are finding great success. Generally, it is a wonderful time to be building.
We at @FactoryAI have seen overwhelming interest in our model-agnostic coding agents and our software factory product. Our team has 10x’d in size, while our revenue has 100x’d year over year. This momentum has been unprecedented.
A much larger competitor, Cognition (makers of Devin) has fallen behind us on the capabilities that matter most to customers: cost, quality, and security. Instead of competing in the market, Cognition engineers feigned interviews with us to pry information about our product. Not finding what they were looking for, Cognition has decided to throw their weight and money at people with direct knowledge of our most confidential plans.
It feels as though ethics is being thrown out of the window in the AI era. People are willing to do anything, including exploiting privileged information and violating ethical boundaries. I think this is unique to our time, and I don’t think it’s right. Integrity still matters.
Yesterday, I made the decision to immediately terminate Christopher Degnan’s roles as a Board Observer and Advisor to Factory, after over a year of service.
Prior to this decision, Chris told me he had a casual conversation with an executive at Cognition AI. When I questioned his intentions, he reassured me that ethics aside, he had “made too much money” and was “too lazy to go work for Cognition,” which I trusted and believed.
On Monday, Chris spent time advising the Factory team on a handful of confidential board-level matters. That evening, he called me to say that the conversation that was initially described as casual and one-off was actually formal and recurring. For weeks, while he sat in our board meetings and advised our leadership team, he was also confiding with executives of our largest competitor. Chris was subject to confidentiality obligations in connection with his work with Factory. We do not know the extent of the information he shared, but it puts his timely questions about our product roadmap and what the parity gap involves into a new light.
It is sad to sever a relationship with someone who has been a trusted advisor - and even a close friend - for over a year. But Chris’s conduct is unacceptable to me. Trust in Board Membership is one of the sacred bonds in the Silicon Valley, one that helps the startup ecosystem thrive. With it comes an enormous responsibility. That trust was violated.
Competition is good. I respect and in many cases admire our competitors. San Francisco is a beautiful, singular place where the bold and ambitious go to defy the norms and precedents of the past. But certain principles that must remain. Violating ethics to seek advantage turns what should be positive-sum into zero-sum.
We all love technology. And we all love to compete. But we must hold ourselves to a higher standard. The future of software engineering comes with abundance that will impact every person on Earth. Building that future comes with immense responsibility. We must build and compete with integrity.