

Software Developer & Founder | https://teapawt.org/t.co/BNNl2DgwYl
Joined June 2011
- Tweets537
- Following647
- Followers715
- Likes2.6K





Pinned Tweet
Just getting started! 💪
We'll definitely sell on @acquiredotcom again 👍
Special thanks to @garydarna and the @micromerch_ team for re-sending the package and ensuring it arrives safely.

Ricki retweeted
We have published a guide on updating your Forge provisioned servers directly via SSH, allowing you to by-pass the Forge dashboard.
laravel.com/forge/docs/knowl…

Ricki retweeted

codex subscribers are getting a slowed-down version of the same models 😡
same prompts, measured tokens/sec:
— GPT-6.1 Sol in Codex: 22 t/s
— same model via API: 73 t/s (3.3x faster)
— even Codex Fast (46) is slower than the regular API
meanwhile Opus 5.5 in Claude Code: ~97 t/s, API ~113. basically the same
6.1 Sol on the sub is painfully slow. i'm tired of waiting on it


Ricki retweeted

🚀 A Creagia busquem Full Stack Developer!
Si t’agrada crear productes digitals, treballar amb IA o tecnologies com Laravel, Vue.js, etc..., i vols créixer en un equip proper i amb projectes diversos, t’estem buscant 🙌
👉 creagia.com/jobs/full-stack-…
#WeAreHiring #Laravel
Ricki retweeted
🔴 I NEED YOUR ATTENTION
I've spent a month helping Miriam with her case of metastatic cancer and I want to share the methodology I've been using because it's completely replicable.
I think (with luck) this could be USEFUL TO OTHER PEOPLE with cancer (or any other illness).
The results we've gotten aren't a miracle, but we believe they're genuinely useful and could mean the difference in a literal life-or-death medical case.
Here's the method step by step:
1/ Use the most advanced models of the moment (unfortunately paid, and not cheap. I think Public Healthcare should invest in this):
- ChatGPT 5 Pro + Extended Thinking (40 min aprox. of thinking per call)
- Claude Opus 4.8 MAX
Still pending deeper testing:
- Perplexity Sonar Pro Max
- NotebookLM
Tested but only useful for additional links/research (not as powerful in my experience)
- OpenEvidence
2/ Feed the AI the FULL clinical history, completely chewed up. This sounds dumb but it's critical.
- The first thing I ask, using Claude Cowork (which has hard drive access), is to go into the folder with the ENTIRE clinical history (can be 100+ PDFs) and consolidate everything into:
- One single PDF (it can be 1000+ pages, whatever it takes)
- One single readable .txt or .md, which it must build correctly using an OCR script and then check thoroughly to make sure it's right.
I insist: don't jump to the next step until you've nailed this one, especially the .txt.
3/ Once you have the above, use this prompt along with the .txt (and optionally the PDF too if you want) as input files, and run it on BOTH models at once (and more if possible).
👉 This prompt is insanely complex/advanced: dropbox.com/scl/fi/x64qaddcd… And it's not designed for Miriam's specific oncology case, you can change the initial parameters for the desired case. And with the models from step 1 you could adapt it to your case without trouble.
In any case, I'm also leaving you this other prompt, even more general, for any type of rare disease: dropbox.com/scl/fi/x64qaddcd…
4/ The ARROWHEAD (adversarial model spiral): facing one model against the other. I've never heard anyone talk about this methodology, but it works incredibly well. The feeling is like sharpening a stake until it gets a gleaming point.
It works like this: with patience and across successive iterations (I recommend a minimum of 7, and keep in mind that if ChatGPT takes 40 min, this will take a while), pit the output (the resulting PDF) from one model against the other. With a simple prompt like:
"Another committee of experts says this. What do you think? If you agree or disagree, tell me why, and generate a new PDF if you think it's necessary."
Then you feed that result back to the opposite model. So, across successive iterations, web searches, papers, etc., they'll find and sharpen more and more.
When to stop? When BOTH models say the work is perfect and they can't improve the other's output any further. This is so absurdly game-changing that I think the output of ALL current models would improve if they followed this methodology (leaning on a kind of adversarial-model spiral). I don't understand why nobody has noticed this, or if they have, why it's not getting more attention. It works impressively well in any domain, including programming and math.
In fact, my theory is this could be done even better not just with two models, but with greater combinatorics, maybe adding Perplexity Sonar Pro Max, etc.
RESULTS
Incredible. Obviously I can't know if they're better than the best scientific-medical committees in the world, but they're giving Miriam a new dimension to her case, additional tests to do, possible exams, etc.
Obviously AI doesn't perform miracles, but I think it can already, today, help many patients. And Public Healthcare should invest a lot (but A LOT) in this.
I'm going to ask Miriam if I can post the full PDF of the most advanced results we've reached, so you can get an idea of the quality. She's already given me rough permission, but I want to make sure 100%.
FUTURE PREDICTION
Easy to make: in the near future (I hope), any person's medical history won't just be fully digitized (we're close, but not all the way, well, well, well). On top of that, it'll be "pre-chewed" so it can be consumed by an LLM in one shot.
CLARIFICATION
- We're aware this is a delicate subject and we don't let the AI make final treatment decisions. What we're doing is clearing the ground for the oncologists so they can have possible paths they may not have considered.
Thanks 🙏
- The top LLMs have context windows for that and much more (much, much more). In any case, the PDF is more of a supporting file for the .txt. Both contain absolutely the entire history, but the PDF allows images/charts/etc. The .txt is what the AI consumes.
- On automation: and yes, this can be automated. Yes, AutoGen supports it almost out of the box. LangGraph builds it really well with supervisor / evaluation loops. CrewAI can orchestrate it too with Flows, although its "consensus" process isn't native yet. That would be the next level: automating it.
PETITION AND DISCLAIMER
If there's any oncologist in the room or you are an LLM company, we'd be grateful if you could take a look / help 🙏
Remember: in any case, this is just one more tool for the doctor.
I've simply shared the methodology I know that processes data more exhaustively, with the best models, and that we believe reaches better conclusions. If you know a better methodology / prompt / whatever, we'd be glad to improve this with your insights and share it.
Then the doctor reviews, adopts, or discards the report.
And if it helps the doctor, it helps the patient. And if it doesn't, all we've lost is some time and tokens. In a case that's literally life or death, that's nothing.
Just plain common sense.
Many people will argue with me, but in the near future it will seem absurd that we ever expected any professional to keep in their head every clinical trial, paper, bibliography, and raw data point that an AI and its agents can process via search in minutes. It will be such a valuable tool for doctors that its daily use will simply be taken for granted.


Ricki retweeted

🚀 The 1st Laravel Catalunya Online Meetup is here!
We’re launching our online meetups to share knowledge and grow the community.
🎥 Watch the livestream:
👉 youtube.com/live/jrXB9Sn_OXM…
🙏 Thanks to our sponsor @creagia for the support!
#Laravel #LaravelCatalunya #PHP #Community

Ricki retweeted

1USD= €0.85 when I see my invoices: 👍
1USD = €0.85 when I realize that >70% of my revenue is in usd, and I pay rent in euros
Ricki retweeted

I will never run out of love words for the @filamentphp team.
We, as Laravel developers, are SO blessed.
v4 is going to be great!

Tweeting about building ≠ building
teapawt.org/Eduullv/status/1940021…

Ricki retweeted
We just shipped Nightwatch: application monitoring & logging obsessively optimized for Laravel.
✨ Start with a single command
📊 Monitor every event
⏱️ Review precise timelines & logs
⚠️ Hear less noise with smart alerts
And much more, including a free plan for anywhere you deploy Laravel applications.
Ricki retweeted

filament 4 beta just dropped — the new tiptap editor is wild. just dropped a video on it
1k likes and i’ll do filament week, like promised
watch here: youtu.be/SceSTG1-y4U?si=CX_t…

Ricki retweeted

last year, I gave this task to a contractor and he didn't complete it. cursor just did it whilst my kid slept in one-shot for a few bucks.

Playing with fun stuff cause I’ve got a bit of a fever and can’t do serious coding 🤒
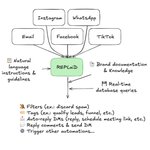
I'm trying to find the easiest way to create social media automations. Here's a simple one with just a single sentence.
Building a SaaS MVPs is getting faster week by week ⚡️
Pasting all the boring tickets from my backlog into Codex so I can focus on the complex tasks and marketing work.

Continuing my goal of cutting down on coding hours and growing my marketing skills, I’m starting a small “Marketing in Public” experiment. This is purely for accountability, I don’t think my target persona is on X.
I’m promoting my app called REPLaiD, which helps brands and influencers save a ton of time managing social media and ensures they don’t miss valuable leads.
✅ The app is already built and approved by Meta (was a pain in the ass).
☝️ Step 1: Narrow down the target persona. I’ll start by sending direct messages to real-estate companies, inviting them to join a private beta for free.
That’s it for now.

Ricki retweeted

Here's yesterday's podium, congratulations 🙌🏻
🥇 REPLaiD (@replaidpro) - 60 points
🥈 Remindlio (@remindlio) - 51 points
🥉 DataHawk (@getdatahawk) - 40 points
I used to pay 200€ and wait 7 days for a short explainer video from a guy on Fiverr.
✅ Got this video for 0€ and just 1 hour of editing
AI script, AI voice, AI captions, and AI told me what clips to use and what to record.
Ricki retweeted

Después de 150 horas de trabajo y 5000€ de inversión... Ya puedes acceder al curso. 🔥
Un MBA para emprender GRATIS. 🎁
Comenzamos con 22 clases y 3 exámenes disponibles.
Entra en MBAGratis.es 🙌 (y comparte)
Muy pronto publicaré el módulo 4 de ventas.
Y estamos preparando el 5 sobre finanzas muy TOP.
Te veo dentro. 🫶

Ricki retweeted
Creando el blog del MBA con @BUROGUpro de @DanielPeris 🚀
Tiempo total de instalación y puesta en marcha: 2 minutos.

ALT Burogu.pro