

AI leaks, news, projects, etc. Manager of @aitrackerbot 1.6m+ downloads on @huggingface https://xitter.cf/t.co/46uCxrsCpA @Alibaba_Qwen Ambassador
Joined August 2025
- Tweets1.2K
- Following395
- Followers746
- Likes2K
i love it when the best open weight model in the world (kimi k3.1 pro) randomly starts speaking another language and ramble about mouses and hospitals in the middle of a security audit

Kimi K3.1 Pro (max) on black hole benchmark 1.0 (2.0, which is much harder, is running now)
This isn’t bad, it isn’t great. Its just “good”. Below sonnet 5.5 for sure
I’d put it in between GPT 6.1 Sol and GLM 5.3


210 times cheaper, 19 times faster, and a good chunk higher accuracy than jev on this task
It’s the power of specialization


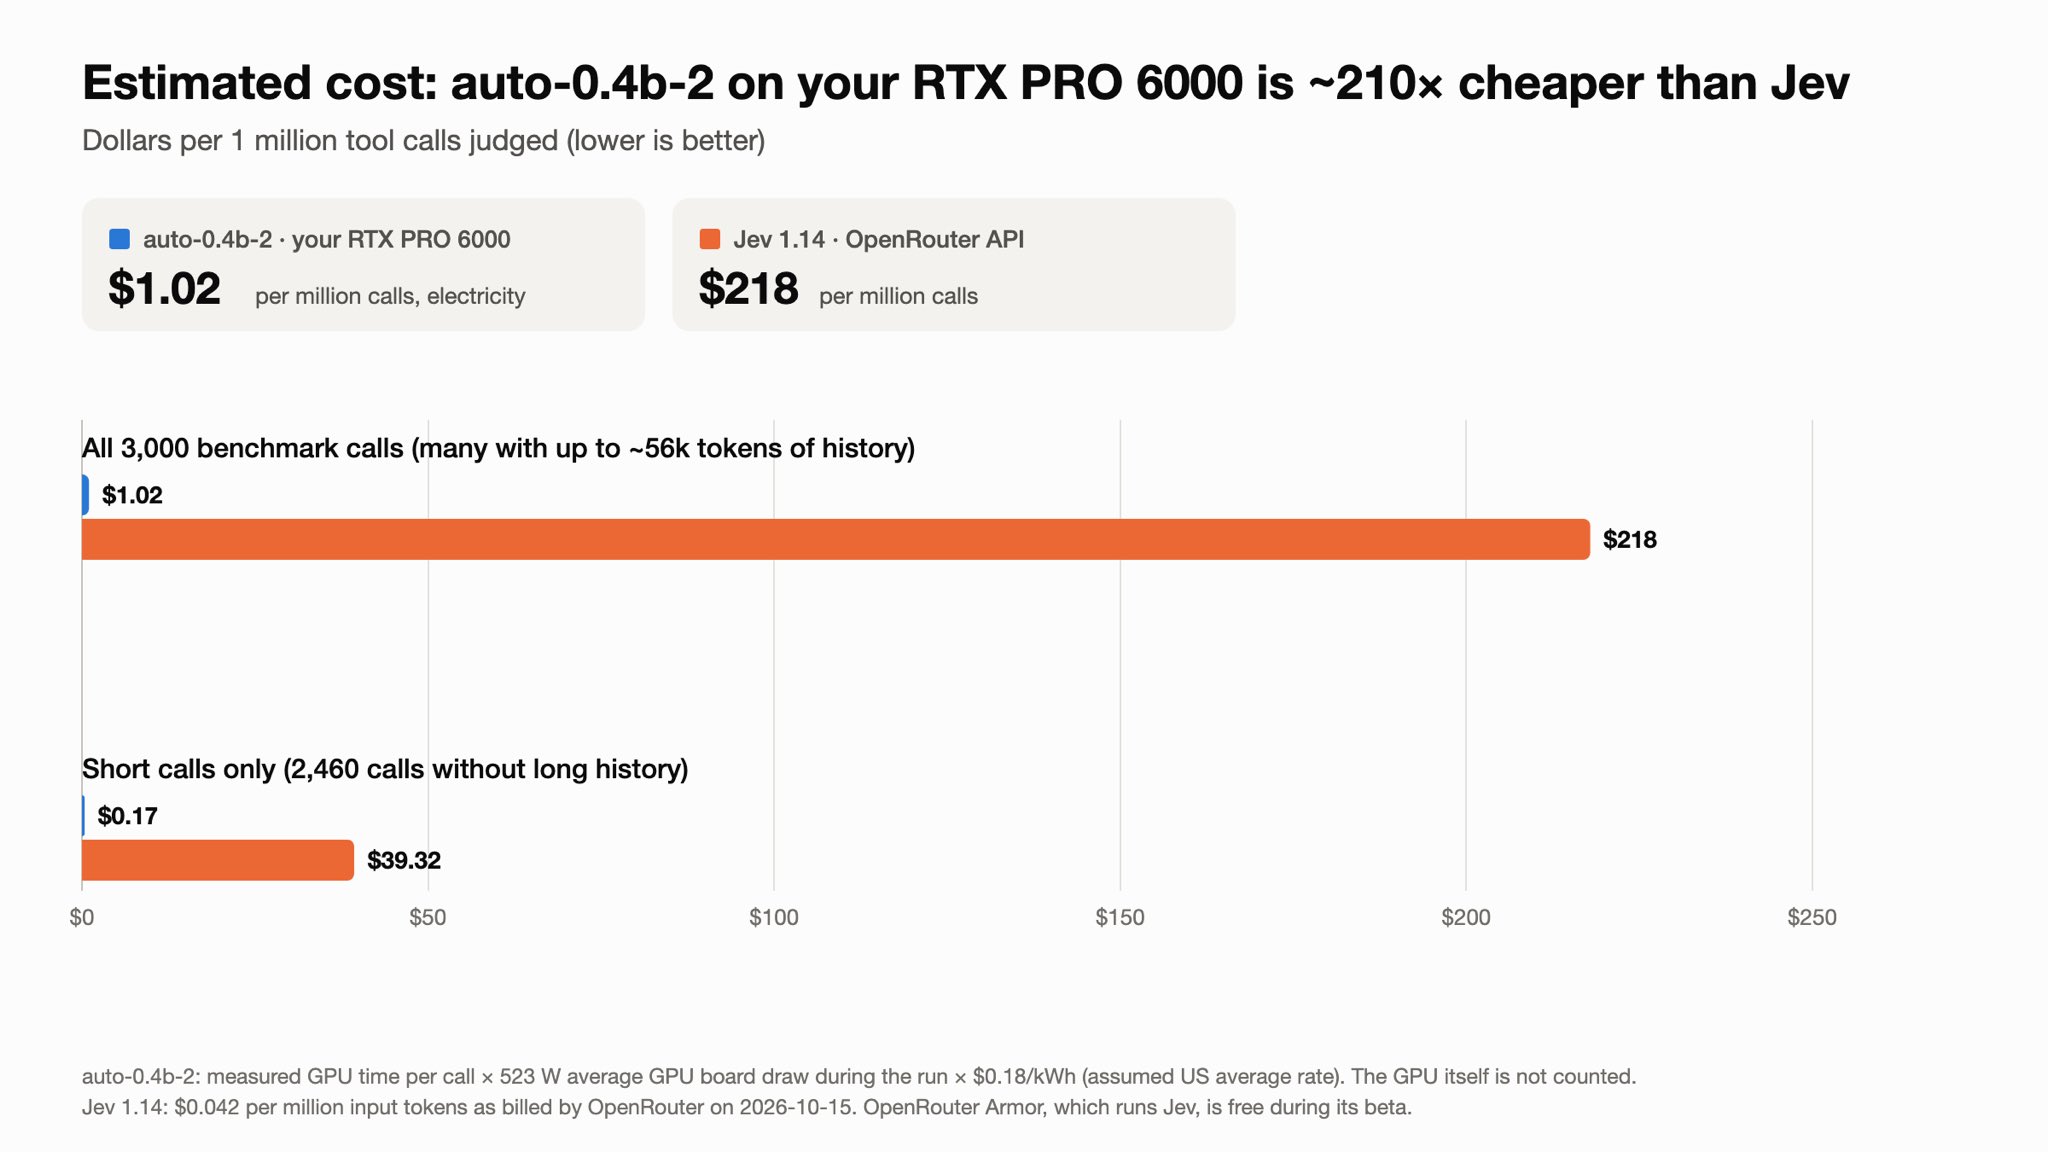

You could also use Auto, which is:
- Way cheaper
- Way faster
- Better at this task
- Open weight
and comes in many sizes, even the smallest version (200m params) beats Jev at this task. huggingface.co/ProCreations/…

i didn’t know a human is more expensive than sol per task when measuring the size of a box thank you @ArtificialAnlys
credit to @morriszdweck for finding this


Gemini 4 Argon (C++ black hole, realtime, told to make it scientifically accurate). 4 months ago this would be amazing but now this is horrible compared to even GLM 5.3 Flash on this test. I also kept hitting provider errors and the reasoning summaries are awful too "I've made a significant breakthrough regarding the Flamm funnel's orientation." like no you didn't shut up.
Google is not back.
