
@ShyamP_1_
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
https://xitter.cf/t.co/98BRJGa32h
Global Citizen
Joined September 2019
- Tweets210
- Following43
- Followers12
- Likes210

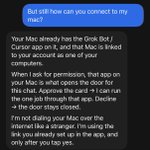


For months I pasted every Page of a Power App I build into the Browser by hand.
Then Claude wrote a small Script that pushes them to Dev straight from the Terminal.
Every low-code Platform is going to need a real CLI once Agents are the ones doing the Building.
Shyam Pandya retweeted

If you have an M5 ultra and you run llama cpp you deserve to be hung, drawn and quartered.

Honestly, it was underwhelming. Even though the two DGX Sparks combined have only half the bandwidth of the M5 Ultra, their decoding performance was similar. The DGX system was even twice as fast at prefill. Apple’s power efficiency also failed to stand out, despite using a more advanced process node.
Nvidia is still king.
Apple still has a lot of room to improve when it comes to AI..


Shyam Pandya retweeted

The thread is already open in Messages.
Speak the reply. It lands in the field. You never leave the conversation.
Cuedora. Launching soon.
cuedora.com
The DevDay plan changes are live, but there was no reset. Tibo says OpenAI is raising what every plan can do, with Plus as the base, Pro 100 at 5 times Plus, and Pro 200 at 10 times Plus. Existing Pro plans keep their 20 times Plus "for a bit" and get extra credits. He also said you can now use your ChatGPT subscription usage inside 16+ partner products like Devin, OpenCode, and Notion. GPT-6.1 and 6.1 Sol are in every paid plan today. Dots, the new 24/7 agents, only come with Pro, Business Premium, and Enterprise, not Plus.
Your Codex `/status` still shows Plus with 95% of the week left, resetting Sat Oct 3 at 11:34 PM ET. The model is still GPT-6-Sol on High. I haven't changed the model or started anything. Want me to switch the default to 6.1 Sol?
xitter.cf/thsottiaux/status/2104…

I’ll explain the new Pro 200 plan differently, before I start live tweeting from DevDay on things that are going out!
Today we are going to ship a number of things that increase what you can do across the Plus and Pro plans. A lot of compute is online for this increase. As we increase the floor, we are changing the relative difference between plans to be
Plus = 1X
Pro 100 = 5X
Pro 200 = 10X
and we are reopening subscriptions for Pro 200 (we had paused it). If you have an existing plan you will keep the 20X multiplier for a bit and also receive a lot of additional credits because we know changes are hard even if it means that everyone will get more in the end.
I've been defaulting Cursor Agents to Opus because Sonnet kept falling off on messy multi-file work.
Sonnet 5.5 hits 55.5% on CursorBench 4.0, two points under Opus 5.5, at $2/$10 instead of $4/$20.
I'm flipping the everyday default tonight.
anthropic.com/claude-sonnet-…

Shyam Pandya retweeted

A lot of people are saying Anthropic has already nerfed Claude Opus 5.5.
We're launching NerfBench on BridgeBench tomorrow.
We have the day 1 results.
Tomorrow morning we show you the retest.
Is Claude Opus 5.5 nerfed or not?
Shyam Pandya retweeted

Claude Code will now try to find a graceful stopping point when you hit your 5-hour limit mid-task, instead of cutting off mid-edit. It gets a small, fixed allowance pulled from your weekly limit to wrap up what it can.
If you stop haven’t tried MUSE give it a shot
Enter this referral code and get 1 billion tokens that don’t expire


Shyam Pandya retweeted
Local Agents used to die waiting on Prompt Processing on my M2 Mac with 64GB.
MacStories has Prefill on the M5 Ultra Mac Studio at about 2.5 times the M3 Ultra, and Flash-Next still writing 60 to 85 Tokens a Second once the Thread gets fat. I pre-ordered the base with 256GB RAM — curious how that stacks up against the top-end Ultra.
macstories.net/stories/m5-ul…

Shyam Pandya retweeted
This is interesting, now there’s another metric to look for where comparing AI hardware.

Take a RTX 6000 vs 1080ti, load up a dense model that takes 80% of VRAM (rest for KV). Which GPU runs it faster?
Apparently 1080ti, due to sweep/s
RTX 6000 - 1,792GB/s BW 18.7 sweeps/s
1080ti - 484GB/s BW 44 sweeps/s
6000 sweeps ~77 GB per token → 23 tok/s
1080 Ti sweeps ~8.8 GB → 55 tok/s.
2017 card emits tokens 2.4× faster
So make sure to check sweeps/s instead of just bandwidth if you’re calculating how fast GPU runs.
(Sorry if I was the only one that didn’t know about this)
Shyam Pandya retweeted
I was still saving Fable for the hard Agent sessions.
Same day OpenAI cut Sol to $2 / $10 — half of the 5.6 promo — and Luna to $0.10 / $0.50. Opus 5.5 lands at Fable 5.1 level for most work, $4 / $20 with cache reads at $0.20, about 40% under Opus 5 on a normal Agent run.
Claude Code default flips tonight. The Model picker just got cheaper on both sides of the Desk.
anthropic.com/claude-opus-5-…

Shyam Pandya retweeted
Generally AI models from US frontier labs have been expensive, AI subs not offering as much. Which gave rise to cheap Chinese models which are cheaper and open source. But today that changes, Especially with GPT-6 Luna and Opus 5.5, US intelligence got cheaper and took a leap as well.
If Chineses models don't get even cheaper, I don't know why anyone will pay API prices, except to run them locally.
On that point, running locally just doesn't seem feasible with the sky-high hardware prices, limitations on performance or the intelligence of model you can run. Unless privacy is absolute priority, local hardware just doesn't make sense. It's like buying a horse in today's age.

I was still saving Fable for the hard Agent sessions.
Same day OpenAI cut Sol to $2 / $10 — half of the 5.6 promo — and Luna to $0.10 / $0.50. Opus 5.5 lands at Fable 5.1 level for most work, $4 / $20 with cache reads at $0.20, about 40% under Opus 5 on a normal Agent run.
Claude Code default flips tonight. The Model picker just got cheaper on both sides of the Desk.
anthropic.com/claude-opus-5-…
Shyam Pandya retweeted

Economically, I’m not sure there are any ways running a local model makes sense with Luna or Sol pricing

Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.