

Sovereign AI agents for enterprises. Deployed in 48 hours. Real ROI. Designed in Cambridge, served from Switzerland. Community of 1200+ leaders on LinkedIn →
Joined March 2026
- Tweets819
- Following6
- Followers176
- Likes119







Pinned Tweet
"Alfred, can you pinch us?"
We’ve spent months engineering a private, highly secure strategic reasoning system that can run complex multi-agent workflows without leaking your sensitive business data to the open web.
It turns out, GPU legend Cevat Yerli was paying attention and turned out to be a top 10 power user of #Alfrada. He broke our servers three times in Feb - Mar by flooding our token bandwidth on both the cloud and on the chip – but could not after we moved to @Exoscale .
When we requested an introduction with @nvidia, Cevat connected us to Ingy Y. - Agents & Quantum Lead, Inception & Startups, EMEA at NVIDIA - without hesitating. Thank you so much, Sir.
Each year, #NVIDIA’s global #Inception program selects and backs high-potential startups pushing the boundaries of #AgenticAI and #QuantumComputing with deep technology sharing, dedicated compute access, and institutional support.
Strategize Labs have been chosen because Alfrada represent a highly unique, #CUDA-native harness: by engineering our agent pipelines to compile and run natively on NVIDIA hardware, we completely bypass the traditional dependency on third-party cloud hyperscalers.
This collaboration directly accelerates our technical roadmap, allowing us to refine our local-to-cloud architecture so you can soon run Alfrada’s secure strategic reasoning tools directly on your own laptop – with zero risk of corporate data leaks.
The future of private strategic reasoning is local-first, CUDA-native, and runs on your own silicon.
@RealtimeCevat @hamzam1981 @s_tabasm @topsyyturvy

We don’t ask you to trust us with your privacy. We ensure it and show you it.
Look, prompts are malleable. If your AI's privacy policy depends on the model remembering not to share proprietary data during multi-step tool execution, you’re hoping against hope.
When we built Alfrada, we took an architectural stance: Private by Design.
That means:
• Policy enforcement occurs at the tool boundary, completely out-of-band from the agent’s reasoning context.
• Data runs inside isolated, ephemeral execution sandboxes.
• Zero retention for model training.
• Sovereign Swiss infrastructure via Exoscale.
Swipe through to see how Alfrada replaces soft promises through deterministic isolation, and why high-stakes strategy requires real architectural boundaries.
Link to our security architecture in the comments.
Deep dive into our security architecture: strategize.inc/private-by-de…

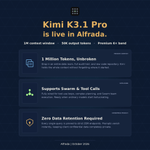
@Kimi_Moonshot's upgraded heavy lifter, Kimi K3.1 Pro, is now live on Alfrada's Recommended tab.
It inherits the seat from Kimi K3, but with sharper reasoning, vision support, and a tighter grip on long-horizon tasks. With 1M tokens in, 50K out, and built-in reasoning, it easily digests your entire stack of vendor contracts, historical financial models, and diligence decks in a single breath.
Kimi K3.1 Pro also supports iterative tool and Swarm calls. Pricing remains the same at Premium 6×, and all calls on Kimi K3.1 Pro run on Zero Data Retention.
It’s a global model, so it won’t appear if you’re on EU Data Residency.
Release notes in the comments.

Read the full release notes and prompt examples here:
alfrada.ai/docs/releases/202…
@hamzam1981 @s_tabasm @topsyyturvy
#KimiK3 #AIModels #GenAI #Alfrada

Telemetry across 23,000 enterprise clusters found 95% of provisioned compute capacity sits completely idle.
Full piece below. 👇
#AI #EnterpriseAI

Source Links:
Ethan Mollick (Wharton School, University of Pennsylvania): Observation on model clustering in frontier labs (October 2026). Sourced from public academic correspondence and empirical research on organizational AI adoption (Co-Intelligence, 2024; Harvard/BCG trial on frontier boundaries): xitter.cf/emollick/status/210942… [Primary Post (X/Twitter)]
Cockroach Labs / Cast AI Infrastructure Telemetry: Analysis of 23,000 enterprise GPU clusters reporting 5% average utilization (Cast AI Cloud & Kubernetes Report, 2026). Business Insider (Primary Report Coverage): businessinsider.com/companie… | Cockroach Labs (State of Enterprise AI & Architecture): cockroachlabs.com/guides/sta…
Strategize Labs / Alfrada Research: Task complexity and completion data (The Autonomy Paradox, June 2026), evaluating ~600 jobs, 1,895 sessions, and 30B tokens with zero user text read: linkedin.com/pulse/autonomy-… | Alfrada Empirical Benchmark & Telemetry: strategizelabs.com/can-it-ru…

It is remarkable how quickly an AI agent can stop behaving like a piece of software and starts acting like an honest mirror.
When we looked across 600 jobs and 30 billion tokens on Alfrada, we expected completion rates to drop off a cliff as the work got harder.
Instead, the numbers completely inverted. Trivial queries hovered in the high-80s, while the hardest, multi-day analytical jobs finished at 98 to 100%.
The reason isn't machine capability. It’s human priority.
We built Alfrada as a digital twin for decision-makers, but we didn’t realize how literally that would play out. A digital twin doesn't just inherit your workflow... it inherits what you actually give a damn about.
Trivial prompts get dropped after two exchanges because nobody truly cared if they finished. High-stakes models and board memos get pushed to perfection because that’s a reputation matter.
The AI wasn’t failing at the easy stuff. It was just reflecting our own interest.
Turns out, when you build a system to mirror human judgment, the reflection is accurate down to the flaw.
The mirror doesn't flatter now, does it?
Full piece linked in the comments. 👇
@hamzam1981 @s_tabasm @topsyyturvy
#AI #AgenticAI #DigitalTwin

Read the full piece on what 1,895 deliverable sessions taught us about how people actually use AI agents.
@hamzam1981 @s_tabasm @topsyyturvy
#AgenticAI #DigitalTwin #AI
xitter.cf/StrategizeLabs/status/…

Something strange showed up in our own data around the time we hit 600 jobs and 30 billion tokens on Alfrada.
Simplest tasks finished in the high-80s. The hardest, biggest jobs finished at 98 to 100%.
Strange, right?! Break down below. 👇
#AI #AgenticAI

Look at those waves, aren't they mesmerizing?
I hear ‘totally’.
But that's not all.
Four things landed in Alfrada this week.
→ You have two new fast models in the picker. Anthropic's Claude Haiku 5.5 (1M context, 128K output). Zero data retention, and EU residency stays in Europe when you have it on. NVIDIA's Nemotron 3.5 Super VL (120B parameters, 256K context). Also on Zero Data Retention.
→ Swarms can now start without you. When you start a Swarm task, close the laptop and walk away. If the Swarm needs your review, or needs to ask you a question, it waits 2 minutes and then decides on its own, for up to 10 approvals in a row, after which it stops and waits for you.
→ Swarm results land in your inbox. If a run finishes while you're away, your agent emails you the deliverables plus a short summary five minutes later.
→ Decks and Word docs are now actually editable. New decks and documents build as a live page you can see in full, then export as real PPTX or DOCX, and stay editable after download.
For details, see release notes in the comments.
@hamzam1981 @s_tabasm @topsyyturvy
#AIAgents #LLMs #GenAI #Alfrada
Full details on all upgrades: alfrada.ai/docs/releases
We modeled Alfrada around the decision-maker. Then 600 jobs and 30 billion tokens of data confirmed the model was accurate.
But what the data revealed was nothing like what we imagined. Oddly enough, that makes perfect sense.
Full story below. 👇
#AI #AgenticAI #DigitalTwin
Read the full piece on what 1,895 deliverable sessions taught us about how people actually use AI agents:
xitter.cf/StrategizeLabs/status/…
Something strange showed up in our own data around the time we hit 600 jobs and 30 billion tokens on Alfrada.
Simplest tasks finished in the high-80s. The hardest, biggest jobs finished at 98 to 100%.
Strange, right?! Break down below. 👇
#AI #AgenticAI
Something strange showed up in our own data around the time we hit 600 jobs and 30 billion tokens on Alfrada.
Simplest tasks finished in the high-80s. The hardest, biggest jobs finished at 98 to 100%.
Strange, right?! Break down below. 👇
#AI #AgenticAI
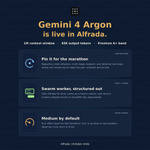
Day-one access to @Google's Gemini 4 Argon is live in Alfrada.
It's the model you pin when the job runs long, deep and hard, where the thread must hold and agent loops must keep calling tools until the thing actually passes.
With 1M tokens in, 65K out, it joins our Recommended tab, which now stands at seven picks. Same Premium 6× band as GPT-6.1 Sol and Claude Sonnet 5.5.
Medium by default. Set lower for fast iterations, higher when the problem deserves the room.
It's a global Google model, so EU-only accounts won't see it.
Release notes in the comments.
@hamzam1981 @s_tabasm @Ibi_qadir @topsyyturvy
#Gemini4 #AIModels #GenAI #Alfrada


Four upgrades landed in Alfrada this week.
→ Every spoken reply, chat voice-over and recording now goes to ElevenLabs' newest model by default.
→ Hand over a script with several speakers and get one audio file back. Everyone voiced, plus a timing sheet saying exactly when each person speaks. Pair it with Presenter Mode and each face lands on screen at the right moment.
→ Double the CPU and RAM (4 vCPU / 8 GB) with 10 GB disk, a pre-built environment so bigger and deeper workflows don't stall on startup and run faster.
→ Four one-off packs: $10, $25, $50, and $100 when you run low. No subscription. Bigger packs give more tokens per dollar, and each top-up resets the 6-month clock on everything you still hold.
So lots to try for you. Why wait?
Release notes in the comments.
@hamzam1981 @s_tabasm @Ibi_qadir @topsyyturvy
#VoiceAI #GenAI #Python #Alfrada
