Timothée Lesort (@TLesort) profile picture

Researcher at Imec AI Labs. Continual Learning Vision/LLMs. Prev. Postdoc. @Mila_Quebec, PhD @IP_Paris_

Berlin
Joined February 2015
Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)Photo by Timothée Lesort (@TLesort)
The scientist used to stand between nature and human understanding. Tomorrow they will stand between AGI's understanding of nature and our own.
5
306
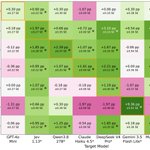
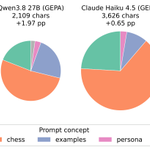
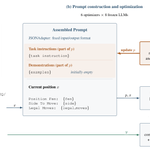
You can now navigate and explore the prompts that makes LLMs play better chess ! imec-ailabs.github.io/Automa…
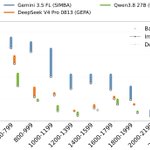
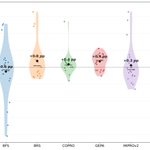
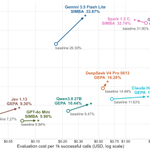
Automatic prompt optimization (APO) is one of the most efficient levers for boosting LLM and agent performance — but measuring real gains is surprisingly tricky. Glad to share from @imec_int AI.labs: "Benchmarking Prompt Optimization of Large Language Models With Chess" 🧵
105
Timothée Lesort retweeted
I recently moved to TU Darmstadt (Germany) and am currently hiring PhD student through ELISS. ellis.eu/news/ellis-phd-prog… If you interested, please apply and choose me as a potential advisor. Topics include Continual/Distributed/Federated/Active/Transparent AI.
8
35
2
217
10,281
Timothée Lesort retweeted
So happy to highlight one of the many applications of Botanic-1, our latest plant FM, on @googlegemma 's website ! teapawt.org/GoogleAI/status/210715…
2
8
2
21
1,741
Automatic prompt optimization (APO) is one of the most efficient levers for boosting LLM and agent performance — but measuring real gains is surprisingly tricky. Glad to share from @imec_int AI.labs: "Benchmarking Prompt Optimization of Large Language Models With Chess" 🧵
2
3
2
19
1,953
11/11) Joint work at imec AI.labs (Paris) with Alejandra López de Aberasturi Gómez, @karch_tristan , @TomVeniat , Philippe Modard, @karl_tuyls and @LudovicDenoyer . We hope it helps develop prompt optimization algorithms and improve the reasoning of models.
89
Timothée Lesort retweeted
Excited to announce our @COLM_conf workshop "Context Beyond the Window"! We have a stacked lineup of speakers focusing on one of the most important topics today: context management. Venue is non-archival; We welcome all relevant 4 or 8-page submissions! teapawt.org/dvnxmvl_hdf5/status/20…
🚨Excited to announce our workshop Context Beyond the Window hosted at COLM in SF! 🚨 LLMs have finite context windows, yet real-world tasks demand absorbing, retaining, and acting on information that far exceeds any single prompt. 1/3 We're looking for submissions across: context-beyond-window.github… • Context compression 🧃 — token compaction, recursive subagent calls, and external memory for storing and retrieving information • Efficient architectures 🚀 — sub-quadratic attention variants that make extremely long context computationally feasible • Continual training 🌱 — test-time training on streaming data, context distillation, and knowledge accumulation through continued pre-training • Agentic memory systems 🐘 — scaffolds and test-time scaling techniques that improve knowledge retention and acquisition in LLMs • Evaluation 🎯 — benchmarking models on increasingly long-horizon tasks
3
14
1,144
Timothée Lesort retweeted
The DiLoCo team at Google DeepMind and Google Research is proud to release Decoupled DiLoCo, the next frontier for resilient AI pre-training. Decoupled DiLoCo enables training with datacenters across the world, using heterogeneous hardware, and never halting the system despite hardware failures.
35
87
33
615
2,729,627
Timothée Lesort retweeted
(continual) pre-training is not dead! some thoughts about cost per task (on cursorbench) being 2x lower, imo it can be due to: - new base model: seems straightforward but it's not imo, you need to optimize the inference/training stack (both for rl and consumer inference), GLM-5 > V3.2 doesn't mean glm-5-base > V3, they may not be equally malleable to post/mid training - more optimized kernel and inference stack/serving (most likely) - rl/mid-training with objective/data to make smaller CoT (most likely) - mid-training with more efficient arch: i would love for this to be true, and i can see how it's necessary if they use the previous base model generation and need efficient memory for long context, but since they also released some tricks with self-summary, i'd say unlikely? (they can and imo should be combined together for very long tasks)
Composer 2 is now available in Cursor.
3
5
2
134
28,540
Timothée Lesort retweeted
This week, we released a paper from Meta @AIatmeta “MuLoCo: Muon is a practical inner optimizer for DiLoCo”, showing that K=1 MuLoCo has a Pareto-optimal performance-training-time tradeoff Let’s drill deeper into single-worker MuLoCo’s efficiency 🧵1/5 teapawt.org/benjamintherien/status…
Are frontier LLMs trained across datacenters? One thing is certain: if the pre-training optimizer’s critical batch size is too small, they are NOT! Excited to announce MuLoCo, a pre-training optimizer that can efficiently pre-train across datacenters while having large enough batch sizes to warrant doing so. 🧵1/N
2
11
1
49
6,253
Timothée Lesort retweeted
I have open positions including Postdocs, PhD, master's students, and PhD interns. For more information eugenium.github.io/Projects/…
5
1
4
2,294