

We provide free, open-source software to simulate public policy. Follow our country accounts too: @PolicyEngineUS and @PolicyEngineUK
UK + US
Joined August 2021
- Tweets751
- Following162
- Followers1.8K
- Likes875




PolicyEngine retweeted

At 4:30pm GMT on Budget day, Wednesday 28 October, we'll present our first estimates of what the Autumn Budget means for public finances, household incomes and poverty, and take your questions.
Register free: us06web.zoom.us/meeting/regi…

Five years ago today we launched PolicyEngine to democratize evidence-based policy. Anyone can change a tax or benefit rule and see what it means for their household and their country.
Thank you to everyone who has built PolicyEngine with us, and to everyone who uses it.
We started in the UK, and PolicyEngine US followed the next year. Anyone can read our open-source models, check how they work and build on them.
policyengine.org
PolicyEngine retweeted

Four new models on PolicyBench. Claude Sonnet 5.5 lands level with GPT-6 Luna: both get 92.1% of tax and benefit answers within $1, with no tools. GPT-6.1 Sol gets 90.6%, Grok 4.7 88.3% and DeepSeek V4.1 Flash 87.1%. GPT-6 Sol still leads all 46 at 95.0%.

ALT PolicyBench leaderboard, September 30: share of tax and benefit answers within $1, no tools. 1 GPT-6 Sol 95.0%, 2 Claude Opus 5.5 93.7%, 3 GPT-5.6 Sol 93.6%, 4 GPT-6 Luna 92.1%, 5 Claude Sonnet 5.5 92.1% (new), 6 GPT-6 Astra 91.7%, 7 Claude Fable 5.1 90.8%, 8 GPT-6.1 Sol 90.6% (new), 12 Grok 4.7 88.3% (new), 16 DeepSeek V4.1 Flash 87.1% (new), of 46 models.
PolicyEngine retweeted
This morning, the Census announced that the SPM child poverty rate was 13.4% in 2025, down 0.1 pp from 2024.
Today we're launching the Child Poverty Impact Dashboard: a tool to analyze how reforms can affect this rate across all 50 states and DC.
policyengine.org/us/child-po…

PolicyEngine at @theiariw Brussels this week: two papers, two discussions, and a free workshop Thursday 27 Aug with CAPE and BEAMM — talks, a live demo, and a roundtable with Belgian policy institutions.
Register: policyengine.org/iariw-2026

PolicyEngine retweeted
PolicyBench tests how accurately AI models compute US taxes and benefits. Two new rows: Ox Alpha, a cloaked preview model with no maker named, debuts fourth of 32 at 84.2% of answers within $1. @grok 4.6 debuts eighth at 82.8%, 1.9 points past Grok 4.5.
policybench.org

PolicyEngine retweeted
.@thinkymachines' first model debuts on PolicyBench as the strongest American open-weight model: Inkling lands #4 of 29, computing 83.8% of US tax and benefit amounts within $1 — ahead of GPT-5.5 and every Claude.
@Alibaba_Qwen's new Qwen3.8-Max debuts #25 at 71.5%.
policybench.org

PolicyEngine retweeted
.@AnthropicAI's Claude Opus 5 debuts on PolicyBench at #8 of 27 — 79.8% of US tax and benefit amounts within $1, 0.1 points behind Claude Fable 5 and +7.2 over Opus 4.8, the second-biggest version jump we've measured.
policybench.org

PolicyEngine retweeted
New from @BudgetHawks, built on PolicyEngine microsimulation: New Approaches to Social Security Benefit Taxation — 16 reform options scored year by year through 2100 on the 2026 Trustees baseline. crfb.org/papers/new-approach…

PolicyEngine retweeted

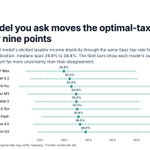
1/ We asked 28 frontier LLMs — GPT, Claude, Gemini, Grok, DeepSeek, Qwen, Kimi, GLM, MiniMax — for the same 26 economic parameters, 15 times each. 10,920 elicitations, every prompt and response in a public repo.
The headline: where economics has settled, the models have settled — and where it's still arguing, the models still argue. That unresolved part moves the US optimal-tax answer by about nine points.
policyengine.org/ai-beliefs

New from PolicyEngine: AI beliefs — elicited economic parameters from 28 frontier language models, 15 runs each, over 26 US-scoped quantities. Pooled centers, 90% intervals, and run-level data for every cell, with literature review ranges alongside. policyengine.org/ai-beliefs

PolicyEngine retweeted
.@Kimi_Moonshot's Kimi K3 debuts #2 of 25 on PolicyBench — the first open-weight model to crack our top ten. 86.2% of US tax and benefit amounts within $1, no tools, +21.6 points over Kimi K2.6: the biggest version jump we've measured.

PolicyEngine at the 10th International Microsimulation Association World Congress in Brussels last week:
· Maria Juaristi on L0-regularised calibration for subnational microsimulation populace.dev/papers/l0
· @vahiidahmadi on an open firm-level model of the UK VAT registration threshold populace.dev/papers/firms
· @MaxGhenis with a hands-on tutorial — build reforms in the browser and in Python policyengine.org/tutorial
PolicyEngine retweeted
GPT-5.6 joins PolicyBench, our benchmark of how accurately AI computes US taxes and benefits (no tools, scored against PolicyEngine):
Sol #1 of 23 — 88.7% within $1 (prior best 83.5%)
Luna #2 — 84.5%
Terra #4 — 83.4%
policybench.org

PolicyEngine retweeted
PolicyBench now scores 20 AI models on how accurately they compute US taxes and benefits — adding Claude Fable 5, Claude Sonnet 5, and five open-weight models: DeepSeek, Qwen, GLM, MiniMax, and Kimi.
GPT-5.5 leads, Fable ranks #2, and DeepSeek v4-pro tops the open-weight models.

We're at the International Microsimulation Association World Congress in Brussels, 1–3 July. Three talks:
• Maria Juaristi — local microdata calibration with L0 regularisation
• @vahiidahmadi — firm microsimulation + VAT
• @MaxGhenis — hands-on PolicyEngine tutorial

PolicyEngine retweeted
Last week, @GovDanMcKee signed the Rhode Island Fiscal Year 2027 budget, which includes a new refundable Child Tax Credit.
Beginning in 2027, taxpayers can claim $330 for each child under the age of 19.
Using our RI CTC calculator, we analyzed the impact of this program.
PolicyEngine retweeted
Can a language model compute a household’s taxes and benefits from the prompt alone — no tools, no lookups?
We tested 13 frontier models against PolicyEngine on 100 representative US households and 18 tax and benefit outputs.
New benchmark: PolicyBench.
policybench.org
