Tim@questflow.ai (@Timrebuilding) header
Tim@questflow.ai (@Timrebuilding) profile picture

Building Agents services in trading market | ex-PM in Security & Wallet & L1. Focus on @questflow

Mars
Joined July 2009
Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)Photo by Tim@questflow.ai (@Timrebuilding)
Every benchmark saturates. On our finance exam, six models already get 97%+ exactly right. So the next version needs tasks that look like real work: restated filings, a hidden extra condition, metrics you rebuild yourself. Easy questions stop teaching. teapawt.org/scaling01/status/21224…
mazebench was fun while it lasted unfortunately it's going to be saturated by like March 2027
23
Worst two months for chip stocks since 2008, while new AI data center spending keeps getting announced. To me this looks like the market pricing governance and export-rule risk, not weaker demand. Those risks can fade fast. A demand problem would not. teapawt.org/Barchart/status/212249…
Semiconductor Stocks are on track for their worst 2-month period since the Global Financial Crisis 🚨 🚨
30
$1 for 1,000 runs. Watching the web for changes is now basically free. The expensive part moves to deciding which change matters. For finance I'd point it at filings and earnings pages, then have an agent check the numbers before anyone acts on them. teapawt.org/AravSrinivas/status/21…
Announcing Perplexity Monitor: an API that lets you track any event or topic or changes to webpages and set up webhooks to update you. Costs a $1 for 1000 runs.
41
A new model's first number usually comes from the lab's own test. Not lying, just not proof. So we built a finance exam: same frozen data, same tools, answers graded by code. Six models now get 97%+ exactly right. Independent tests are boring to build. That's why so few exist.
32
Physics is a great test for AI because the answer either holds up or it doesn't. Finance works the same way: a ratio is right or wrong. I'd love to see more AI results where the output gets checked by code or by experts, not by vibes. teapawt.org/gdb/status/21221260106…
GPT-6 Astra for theoretical physics:
38
Days after stepping down as CEO, he's reportedly talking comeback. That tells you who the market thinks owns Nvidia's roadmap. If he returns, the price probably snaps back first. The governance questions take a lot longer to settle. teapawt.org/unusual_whales/status/…
BREAKING: Jensen Huang discusses comeback as Nvidia CEO with allies, per FT
38
Best seed for an eval: a task that already fooled you. One of ours: rank six companies by revenue growth, but use the restated figure from the latest filing. Gold answer computed by code before any model saw it. That one rule catches a lot. teapawt.org/Vtrivedy10/status/2122…
easy win for building evals: agents build way better & more reliable Evals/Benchmarks if you seed them with examples of good/bad design across tasks (Terminal Bench, HLE, Harvey LAB, internal evals, etc) the design space for a single Eval is huge - verifier design (rubrics, programmatic vs judge, - environment fidelity (container settings, realistic tools) - synthetic data creation - vagueness vs enough information in task descriptions agents are amplifiers of their context -> ex: in codebases, they copy all the good/bad patterns that already exist so we should use this to our advantage by seeding no benchmark is perfect - but lots of time went into getting stuff right, agents are hopelessly bad at designing from scratch we embed examples we like into skills which gives agents something concrete to reference be wary of “overfitting” to existing evals, it’s a delicate balance between stability & diversity
34
Checking a finance answer with an AI agent now costs almost nothing. On our frozen finance exam, four models get 94%+ exactly right for under 6 cents per user task. One of them is free. The cost of the check went to zero. The cost of one wrong number didn't.
43
a16z says agents are already the majority of web traffic. Next step is agents buying things. The bottleneck won't be the model. It'll be permission. An agent that can spend needs a budget it can't raise, a list of what it's allowed to buy, and a log a human can read in 10 seconds.
27
1
26
601
Confusing pricing is a real tax on builders. For agents, the number I care about is cost per finished task, not per token. On our finance exam the spread is wide: six models clear 97%+ strict pass, at $0.015 to $0.905 per user task. teapawt.org/simonw/status/21210394…
The pricing for Gemini 4 is pretty confusing - Argon and Carbon are the same token price as each other, and the new Hydrogen is only a 25% discount on that price - though Carbon/Argon will 2x in price on Dec 1st Hydrogen's pelicans are notably worse simonwillison.net/2026/Nov/1…
1
46
$1.4T of AI spending, 0.2% of GDP growth. Either the payoff hasn't landed yet, or a lot of the spend leaks out as imported hardware. The market is still pricing the first story. This week's Nvidia drop is a test of that patience. teapawt.org/zerohedge/status/21210…
1
49
Reading tone on earnings calls is the fun part. The boring part decides if it works: is the number it acts on the right number, from the right quarter? I'd want that checked by code before $50M rides on it. teapawt.org/rohanpaul_ai/status/21…
This AI reads the motives behind what executives say on earnings calls. A hedge fund now trades a dedicated $50M portfolio on it. Thorsten-4, a Large Psychology Model that can read what somebody is really trying to say. Psychologists interviewed the same 7,000+ people again and again over 4 years and hand-tagged 35M+ words from those talks against 50 behavioral and psychological traits. so the model learned which language patterns (how someone frames a decision, handles uncertainty or reacts under pressure) match which motives and decision styles. Because they followed the same people for years, they could keep only the patterns that held steady across situations, then test the model’s predictions against established psychology tests and against what those people actually did later.
1
39
Cheapest eval habit: keep a list of every finance task an agent got wrong. Rerun it on every new model. Our finance exam works the same way: frozen data, same tools, graded by code. Families every model aces get retired. Six models now clear 97%+. The list gets harder.
1
48
This. Demos are easy. A real eval needs the same world every model walks into. On our finance exam that's a frozen snapshot and the same 16 tools, graded by code. Six models already clear 97%+ strict pass. The next step is harder user tasks. teapawt.org/omarsar0/status/212066…
Agent evals need to feel more real-world. Pretty cool to see @pluraiAI ship Plurai Simulation today. You get a digital twin of your agent's world and can test it there instead of in front of users. Live now and free to get started.
27
One good earnings print doesn't retire the discount rate. A finance agent should hold both in the same answer: the beat, and the yield. That's the "resilient but capped" regime in one sentence. teapawt.org/business/status/212058…
The artificial intelligence trade is resilient, as evidenced by the positive reception to CoreWeave’s earnings. Still, AI capex fatigue and a higher-inflation, higher-yield regime will keep a lid on stocks. bloomberg.com/news/newslette…
21
Cost next to the score is the right habit. Congrats to @GoogleDeepMind on Carbon. I'd run the same test on filings and prices, not just repos. On our frozen finance exam, six models already clear 97%+ strict pass — every number exact. teapawt.org/PawelHuryn/status/2120…
Gemini 4 Carbon now holds #2 and #3 on my bug-hunt benchmark. Only Fable 5.2 on max scores a bit higher. 2 real repos, 105 replanted bugs. Find and fix what you can: - Fable 5.2 (max): 58 for $139.65 - Gemini 4 Carbon (high): 57.3 for $31.32 - Gemini 4 Carbon (medium): 56 for $24.95 - Sonnet 5.5 (max): 51.3 for $154.03 - Fable 5.2 (xhigh): 49 for $61.01 - GPT-6 Astra (max): 45 for $33.03 - Gemini 4 Argon (high): 40.7 for $7.16 Stellar job, Google!
38
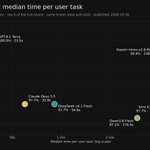
Clearing 97%+ on a finance exam isn't the end of the story. Among those six models, tool use and wait time still differ a lot. GPT-6.1 Terra: 7.6 calls, 23.5s median. Claude Opus 5.5 uses the fewest, at 7.2. The budget is 40 calls. All six stay well under it.
2
52
Business Agents answering customer questions is the easy part. The hard part is when a customer asks about a price, a fee, or a balance. Then the agent has to be exact, every time. That's the test I'd run before turning one on. teapawt.org/OpenAI/status/21202165…
Now in beta: Businesses in ChatGPT. Claim your business, manage your information, and get insights on how people engage with you. Eligible businesses can also build a Business Agent to answer customers’ questions and help them explore what you offer. openai.com/index/introducing…
38
10-year at 5%, and the Fed's Goolsbee calls October CPI "borderline disturbing." This is the backdrop for the biggest AI IPOs. When the discount rate bites, long-duration growth gets priced on cash flow, not vibes. teapawt.org/Barchart/status/212030…
U.S. 10-Year Treasury Yield rips to 5% 🚨 🚨 Here we go again!!
33