




Pinned Tweet
Can we determine whether a model has been trained to generate harmful content without ever producing a single image?
In our new paper, which won an Outstanding Paper Award at the AI4GOOD workshop at ICML 2026, we answer yes.
We introduce Evaluation without Generation, a new paradigm for auditing models without producing outputs, and Gaussian Probing, the first scalable method for detecting harmful specialization directly from model weights.
We demonstrate it by detecting CSAM-specialized LoRAs, a task where standard evaluation is impossible because generating even a single image is illegal.
📄arxiv.org/abs/2604.25119
🧵


On ethics: we did not possess or generate any CSAM data or CSAM-specific LoRAs, nor did we train any LoRAs on such material. All such data remained solely with authorized entities, handled in accordance with applicable laws and organizational safeguards. We intentionally omit further details to reduce misuse risk and preserve operational security.
We also encourage responsible disclosure of vulnerabilities to [email protected].
1
64
Shoutout to my incredible team of collaborators @thorn (Rebecca Portnoff, Michael Simpson, Rob Wang), @MIT (@MarzyehGhassemi , @Ashia__Wilson , @StempfleLena), and @BU_Tweets (@ayush_sekhari).
Stay tuned for more from our team on addressing AIG-CSAM!
📄 arxiv.org/abs/2604.25119
📰MIT News: news.mit.edu/2026/new-method…

1
77
I'll be at NeurIPS starting today until Saturday! I'd love to chat with folks about privacy and security, open-weight model safety, safety pretraining, and unlearning. I'll be presenting our spotlight below at the poster session on Wed from 4:30 - 7:30 PM!

Some jailbreaks happen because LLMs learn spurious correlations between syntax and safe domains. A harmful prompt that sounds safe can slip through. It was great blending linguistics and security with my great collaborators!
You’re unable to view this Post because this account owner limits who can view their Posts. Learn more
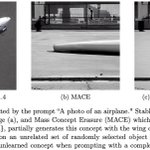
🚨 Your diffusion model might relearn what you made it forget, even without trying! 🚨
In new work, we show concept unlearning can be reversed when finetuning on unrelated data. Even worse, unlearned concepts can resurface when prompting for an unrelated concept!
(1/9)


Why does relearning occur? Our theory shows:
1) Difficulty is based on the similarity between the concept and the finetuning data subspaces
2) Severity is based on the strength of the curvature of the loss function in the directions related to the unlearned concept
(8/9)
1
114
This was a great collaboration with @rohanalur , @ayush_sekhari, @manish_raghavan, and @Ashia__Wilson!
Check out our preprint and would love to chat more with folks interested in open-weight model safety!
arxiv.org/abs/2410.08074
(9/9)
