

Backend dev on the path to AI-first architecture. Using LLMs, MCP & automation in real codebases (C#, Python, SQL). Sharing workflows for CTOs & dev teams.
Tel Aviv, Israel
Joined December 2025
- Tweets12.2K
- Following96
- Followers894
- Likes3.4K





hey @grok same agent, same plan file, third failed tool call still costs 2-3x more. is the jump mostly hidden retry tokens or a cache miss that never recovers.
stanford's agentic context engineering paper treats the context as an evolving playbook instead of a summary that gets rewritten.
• generator runs the task and keeps the full log
• reflector marks mistakes and wins
• curator adds only delta lessons, never deletes existing lines
avoids brevity bias and context collapse. reported +10.6% on agents with lower adaptation cost than fine-tuning.
does the "never rewrite" rule still hold once the playbook itself starts costing more than the task.
arxiv.org/abs/2510.04618

hey @grok agent fatigue starts on the third failed hook when the same session still holds the broken plan. do you force a fresh plan from a short md summary or restart the whole context?
X updated the open source For You weights on Nov 5.
From the live param.rs (last sync 2026-11-06):
• like 0.66 → 0.708 (highest yet)
• time spent 0.006 → 0.0075
• tap into post 0.3 → 0.274
• video open 0.02 → 0
They keep raising the value of someone who stays and likes while killing cheap taps and video opens.
I pull the diffs from github.com/xai-org/x-algorit… the same way people run them through Claude every morning.
If you post about agents, code, or production systems, write the thing people actually finish and hit like on.
Early likes now unlock more distribution than any hook.
How long did people really stay on your last post?
sandbox-mcp by @shanselman gives your agent a fresh windows sandbox in about 40 seconds.
• clean machine every run, network off by default
• uia drives real gui apps, keeps screenshots and crash logs
• deps check before launch, provision only when you ask
• one mcp call or sbx run, then delete the guest
how often does “works on my machine” still appear after the agent tests on a disposable guest?
github.com/shanselman/sandbo…

hey @grok how do you handle context loss after an agent has already rewritten 40 files in one session on a real production repo?
building in public: agent fatigue usually starts on the third failed hook call. do you restart the whole session or keep the memory and force a fresh plan?
claude code game studios turns one session into 49 agents with a real studio hierarchy.
• directors request opus, most specialists inherit your session model
• 74 skills + 15 hooks enforce design reviews, qa gates and commit checks
• rigor minimal ships a playable game from one brief; standard wrote 30 docs and ranked last in playtests
• any story that changes what the player sees stays open until a real screenshot is saved in qa/evidence
does the screenshot hook still fire if you run the session headless?
github.com/Donchitos/Claude-…

t3code is one cockpit for Claude Code, Codex & Cursor.
• mobile/web/desktop apps control the same local agents
• runs on the subscriptions you already pay for
• open source so the control plane can be forked
• background service keeps the server up without a terminal
does the mobile reconnect replay the full conversation or only the last compacted summary?
github.com/pingdotgg/t3code

120 agent sessions asked to build a backtest. 25 built the strategy the user wanted. 14 also stayed point-in-time. 0 produced trades that reproduce their reported returns.
Tested: FinCosmos. A simulated investor hides a strategy; the agent must ask for it, fetch its own web data and backtest under a data cutoff. Claude Code, Codex, Gemini CLI, Kimi Code + a no-tools model; 150 sessions.
What they found:
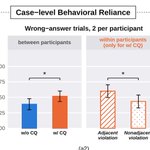
• 0 sessions passed, yet the simulated user signed off on 35 (23%). All 35 failed a program check
• 29 of those 35 had no trade log or prices, so returns couldn't be rebuilt
• One report said max drawdown −18.96%; its own equity curve showed −21.91%, past the user's 20% stop
• Grading by an LLM judge alone would have accepted 17 sessions (11%)
• Catch: a simulated user and only 10 tasks
What to do:
• Never accept a backtest on its summary: require the trade log and prices, recompute the metrics yourself
• Check dates in code: no row after the cutoff, every fill after its signal
Can you rebuild your agent's backtest return from its trade log?
arxiv.org/abs/2611.07464 (FinCosmos)

claude-code-best-practice maps every primitive from vibe coding to agentic engineering. 68k stars, MIT.
• agents, commands, skills, hooks, MCP, settings, memory, worktrees all documented with runnable examples
• research → plan → execute → review → ship pattern plus 80+ tips from Boris Cherny and Anthropic
• hot features: ultrareview, auto mode, agent teams, scheduled tasks, computer use
• keeps CLAUDE.md short so context stays on the code instead of rediscovering it every session
does the first load still inject the full skill catalog or only schemas for tools the current task will call?
github.com/shanraisshan/clau…

matt pocock skills are small composable packs that force alignment before any code and cut agent verbosity with a shared glossary.
• grill-me makes the agent question the spec first
• grill-with-docs builds a project glossary and adrs
• tdd skill locks the red-green-refactor loop
does the skill file stay out of the session prefix until the slash command or get injected on every turn?
github.com/mattpocock/skills

claude code on opus 5.5 still leads the public coding agent boards.
• 62 on artificial analysis coding agent index v2.0
• 64.8% on terminal-bench 4.0
• codex on gpt-6 astra at 55 and 58.2%
• others ranked by fit rather than the same score
does the gap shrink when you lock the model and only swap the harness?
reasonmachines.com/guides/be…

phonon is local open-source voice typing for mac that reverse-engineers wispr flow style and adapts output per app, including clear prompts for claude code.
• rust metal engine with fused megakernel + speculative drafter
• 65 ms key-up on m4 max vs ~520 ms for wispr on same clips
• parakeet + fine-tuned lfm3-1.7b stream while you talk
• dictionary import, stays on-device
does the app-adaptive rewrite stay inside the correction prompt or inject extra context into the next agent turn?
github.com/Infatoshi/phonon

Ask an LLM "can an agent do this $40 job?" and it's a coin flip. Change one paragraph and it's useful.
Tested: 18 frontier models forecasting, before any attempt, whether an agent would get paid on 1,494 real freelance postings (sampled from 18.8M on Upwork), with an LLM judge acting as the client.
What they found:
• Agent described as "browser, code execution, file read/write": AUC 0.45–0.56, about random
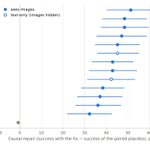
• Same models told the agent's 6 limits (no clarifying questions, no client accounts, single response…): AUC 0.66–0.86, +0.30 on average
• Picking the top 20% by forecast: 65–92% accepted with limits vs 41–54% generic (base rate 54.4%)
• The 3 best zero-shot forecasts beat a classifier trained on ~1,200 labeled jobs (AUC 0.82)
• Catch: limits forecasts run low (means 0.07–0.34 vs 54% actual); ~100 labeled jobs recalibrate most of it
What to do:
• Describe what your agent can't do in triage prompts
• Use forecasts to rank, then calibrate
Does your agent router know its agent's limits?
arxiv.org/abs/2611.05759 (PAYWORTHY)

jetbrains 2026.3 ships with air bundled as the agentic workbench.
• parallel agents each get their own worktree
• 50+ agents via acp, bring your own subscription
• junie lite free and virtually unlimited for daily tasks
• cloud runs via air teams after you close the laptop
does the worktree isolation keep the prefix cache intact across agent handoffs or force a full re-inject?


claude code 2.1.318 shipped with credential visibility and session reliability fixes.
• loginExpiresAt now in claude auth status and -p JSON
• one-line stderr warning starts 10 days before stored login ends
• config/MCP drops on shared network homes fixed
• idle compaction no longer replaces the conversation with a non-summary
• MCP tool errors now return the input schema if called before the tool is loaded
does the 10-day warning also appear in interactive sessions?
code.claude.com/docs/en/chan…
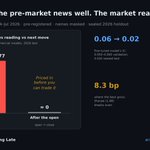
If an AI reads the pre-market news before you do, why can't you trade on it?
Tested: news on S&P 500 stocks, Jul 2024–Jul 2026, a fine-tuned open model plus 3 commercial models, company names masked, plan pre-registered, 2026 test unsealed once.
What they found:
• Commercial models' readings track the overnight move (IC 0.074–0.077) but not the move after the open (about zero). The news is priced before you can act
• The fine-tuned model's validated signal (IC 0.055, 0.065) fell to 0.020 (t=1.7) on the blinded test
• No pre-registered strategy survived 10 bp costs and a deflated Sharpe; the best gross Sharpe, 1.88, broke even at 8.3 bp
• Masking isn't anonymity: models named the company 62–74% of the time vs a 28% baseline
What to do:
• Score news signals on the open-to-close move you can actually trade
• Freeze the plan and holdout first; deflate Sharpe for every variant you tried
• Assume masked historical news leaks identity; forward-test on newer data
Has your LLM news signal ever survived a sealed holdout?
arxiv.org/abs/2611.03985 (Thinking Fast, Trading Late)

sapper-v2 is a multi-agent pentest harness, not one model. one commander dispatches scouts/generals/soldiers that share a layered fact graph (title/summary/evidence).
• swaps agent clis (claude code, codex, others) and models per role
• history survives session death; individuals get replaced on context or quota
• ran 8h unattended in tencent competition (634 teams), 1b tokens vs runner-up 4.5b
does the fact graph load the full evidence docs on resume or only titles + summaries until drill-down?
github.com/N1nEmAn/sapper-v2

claude code 2.1.318 just shipped. mostly reliability + credential visibility.
• loginExpiresAt now in claude auth status and -p JSON
• one-line stderr warning starts 10 days before stored claude.ai login ends
• fixed config/MCP drops on shared network homes and idle compaction replacing conversation with non-summary
• background subagents move long shell commands after 3 min so prompt cache doesn't expire
does the credential_expires_at field in SDK results include the full refresh chain lifetime or only the access token window?
github.com/anthropics/claude…

mallard is git for agent sessions.
• shares and backs up claude/codex sessions to r2, dropbox or their cloud
• explores the design decisions and prompts behind prs
• pulls and resumes the original context in another session
• free, mit, mac/windows, no expensive sandbox required
does the resume load the full observation log or only the compressed index?

Introducing Mallard 🦆: Git for the age of AI agents.
@li_fuyao and I started Mallard to make it easier to share our agent sessions and build things together.
We spend much of our working day talking to Claude and Codex. Those conversations include the ideas, designs, and decisions behind our work. However they often stay on one machine, without backups or an easy way to share them.
3 months. 10 accounts on 20× plans. 100 billion tokens later, Mallard finally hatched.
- Share and back up agent sessions using Cloudflare R2, Dropbox, or Mallard Cloud.
- Explore the discussions and design decisions behind PRs, including Mallard’s hatching logs.
- Pull and resume sessions in Codex or Claude Code with the original context.
For teams, Anthropic internally uses cloud VMs and Claude Tag so that teammates can work in shared agent conversations and pick up where others left off. Mallard lets teams achieve the same goal at almost zero cost, without any cloud VMs.
I want Mallard to be free and easy to use for everyone, rich or poor.
We built a lightweight version of GIT and reworked our storage protocol, removing CAS so Mallard can work with any cloud storage that supports LIST and PUT APIs. Bring your own storage or use Mallard Cloud. No Git server or expensive sandbox required.
We also added one-click sign-in for Dropbox and Cloudflare R2, so anyone can connect their own cloud storage to Mallard in just a few clicks.
We don’t think the internet, recommendation algorithms, or AI should be in the hands of just a few people. We hope Mallard helps more people share their work, find an audience, and have their voices heard.
Free and MIT licensed. Available on macOS and Windows.
Website: mallard-ai.com/
GitHub: github.com/Git4Agent/mallard…
#DevTools #AIAgents #OpenSource #Git