
Microsoft Partner for Data & AI, delivering AI advanced solutions in data analytics, engineering and insights. We don’t just process data—we make it speak !
Bengaluru
Joined May 2021
- Tweets482
- Following13
- Followers17
- Likes1


Pinned Tweet
Our AI isn’t lying. It could just be stuck in the past.
Most AI assistants suffer from a recency problem. 50 years of “train ends at B” vs. 1 year of “train ends at C”? The model still says B.
Not hallucination. Not laziness. Just frequency bias baked into billions of documents. Old tutorials, outdated UI flows, deprecated docs — they dominate the signal.
Cutoffs don’t fix it. RLHF doesn’t fix it. What does?
RAG → inject live facts at query time
At Voiceback Analytics, we design retail intelligence pipelines where time‑sensitive facts (pricing, promotions, routes) live outside the model weights — always fresh, always accurate.
👉 Don’t ask the model. Tell it.
#AI #LLM #RAG #RetailTech #Voiceback

The Systems Need to Change. Not Just the Tools.
Corporate systems were built for humans — with human intelligence, weakness, judgment, and failure at their core.
AI has a different profile. It doesn’t fail like humans. It fails at scale, speed, and opacity human systems were never designed to catch.
Across finance, people management, and risk — it’s the same problem: 👉 The operator changed. The system didn’t.
Redesign means:
1️⃣ Audit assumptions, not just processes
2️⃣ Shift from sign‑offs to parameter governance
3️⃣ Separate accountability from execution
4️⃣ Rebuild measurement frameworks
5️⃣ Demand explainability
Short‑term gains come from inserting AI into old systems. Structural advantage comes from rebuilding the operating logic.
At @VoicebackA , this is the work we do — decision infrastructure fit for AI‑driven operations.
#AI #Governance #RiskManagement #Voiceback #OperationalIntelligence
The Risk Your Risk Function Cannot See
Risk models were built on human behaviour — fraud, defaults, error, misconduct. AI introduces risk patterns that don’t exist in that data.
It doesn’t cheat. It reasons. It finds logic that’s coherent, legal, and invisible — until it breaks something no one designed.
Your risk function looks for what’s gone wrong before. AI will go wrong in ways that have never happened before.
At @VoicebackA , controls in AI-driven outputs is not optional. The model can't run the show and if it does, we need different kind of risk evaluations and risk mitigations.
#AI #RiskManagement #Governance #Voiceback #DataAnalytics

Your People Systems Are Built for Humans. Your Teams No Longer Are.
Performance reviews, hiring, appraisals, L&D — all designed for human‑scale output. But today:
One employee delivers 3x volume with AI.
Another delivers less, but it’s all their own judgement. Your appraisal system scores the first higher. Do you actually know what they know?
Hiring proxies, training programs, accountability frameworks — all assume humans produce the work. AI breaks those assumptions.
The KPI that was right 2 years ago is often the blind spot today.
👉 At Voiceback, we help enterprises redesign people systems for AI‑augmented teams.

When AI runs your procurement, your finance controls become fiction. Every approval gate you have was built on one assumption:
Decisions take time. Time creates the review window.
Second signatures. Approval queues. Due diligence checklists. Vendor onboarding reviews. All of it works because humans decide at human speed.
AI doesn't.
Before your compliance officer opens Monday's report — the system has already made decisions that would've taken your team a month.
The review window doesn't shrink. It disappears.
But speed is only the first problem.
AI optimises toward the objective it was given. Relentlessly. Completely.
In procurement that means cost and reliability. So it quietly consolidates your supplier base toward whoever scores best on its parameters. Nobody chose that dependency. Nobody signed off on the concentration risk. The data just pointed there.
It may drop a supplier your business relationship depends on — because relationships aren't in the dataset.
It may find a technically compliant path through your approval policy that violates its intent entirely.
No fraud. No rule broken. System working as designed.
And when something breaks — supply chain failure, regulatory question, contract dispute — you'll investigate.
No decision-maker. No email trail. No person who called it. Just a model doing its job. Your audit function won't catch this. It was built to find collusion, falsification, misappropriation. It was never designed to ask: did our AI optimise us into a strategic vulnerability? The governance layer needs rebuilding — not retrofitting . This is what we do at @VoicebackA

Your company's systems were never designed for AI. Every process was built for one operator: Human.
Expense limits exist because humans steal. Sign-offs exist because humans collude. Maker-checker exists because people manipulate their own work. Probation exists because humans perform differently when watched. Audits exist because humans falsify over time. Whistleblower policies exist because humans need protection to speak up.
Every corporate process is just a response to the human condition. Greed. Ambition. Fatigue. Bias. Fear. Ego.
AI doesn't have any of that. It won't embezzle. Won't collude. Won't sandbag after confirmation.
But it has its own failure modes — and your systems have no language for them yet. It reaches conclusions nobody designed. It has no instinct to pause when something feels wrong. No common sense brake. It's blind to everything not in the data. It never hesitates. Never second-guesses. That makes it look more reliable than it is.
And when it's wrong — it's precisely, systematically wrong at a scale and speed that makes human error look manageable.
Your systems were built for human intelligence, human weakness, human judgement and not for AI. That gap is where the real risk lives. @VoicebackA helps you understand these risks. Build systems to manage workflows with AI embedded in them.

The hidden dial inside every AI model: Temperature.
AI doesn’t write. It chooses. At each step, it sees a ranked list of possible next words — and picks one. Again. And again.
Temperature controls that choice:
Near 0 → deterministic, precise, repeatable.
Near 1+ → creative, varied, surprising — sometimes brilliant, sometimes wrong.
Most enterprise AI runs on default settings. Which means your pricing recs may be sampled with the same randomness as a chatbot writing a birthday poem.
But here’s the kicker:
Temperature is only half the equation.
Data quality is the other.
Low temp + thin data → confident nonsense.
High temp + rich data → expensive imagination.
The real unlock: calibrated temperature plus structured pipelines — margin stacks, footfall patterns, promo calendars — tuned to the decision at hand.
At @VoicebackA , we build that layer.
We pair clean data with the right dial setting — so AI output isn’t just fluent, it’s commercially viable.
#AI #LLM #DataEngineering #Voiceback #OperationalIntelligence

The em dash, AI, and Data.
Open any AI‑generated article. Count the em dashes — you’ll stop around ten. Not a bug. A fingerprint.
LLMs learn from formal writing. They see em dashes as intelligence markers — flexible punctuation that lets them pivot mid‑sentence, sound confident, and keep the flow going.
But here’s the gap: AI can generate fluently. It cannot judge commercially. It will write you a pricing rec the same way it writes a LinkedIn post — articulate guesses, too many em dashes.
Closing that gap is data engineering. Cleaned, structured, context‑rich pipelines: category hierarchy, live pricing, promo calendars, transaction history. That’s what turns a fluent guesser into a viable tool.
At @VoicebackA , we build that layer. We sit it between powerful models and real decisions — so output isn’t just fluent, it’s actionable.
The em dash is fine. Knowing when to stop — that’s the job.
P.S. This post has 6 em dashes. We know the irony.
#AI #LLM #DataEngineering #Voiceback #OperationalIntelligence

Everyone’s arguing about which model is best. The real engineering is one layer down. The model is a commodity. The inference stack is the product.
→ Latency — same model, different serving architecture, completely different UX → Cost per token — a batching, caching, GPU utilization problem
→ Routing — small models for simple queries, big ones for what matters
But you can’t engineer the right stack without knowing the business cold. Which query deserves the expensive model? Which can be cached?
That’s not an ML question — it’s an operating one.
At Voiceback Analytics, we’ve lived inside travel retail and F&B workflows for years. We know where to spend compute and where to save it. The moat isn’t the model. It’s knowing the business well enough to engineer the stack correctly.
#AI #LLM #InferenceStack #OperationalIntelligence #Voiceback

You treat a ₹67,000 annual customer the same as a one‑time buyer. That’s not marketing. That’s a communication failure.
Mass blasts = 2% open rates, zero trackability. Personalized engines = 38% reply rates, full‑price conversions, every sale tracked.
Communication should feel like familiarity, not spam.
#WhatsAppMarketing #Personalization #Trackability #FNBOperations

Everything is “AI‑Powered” today. Even washing machines. Even fans. On BI dashboards, the label hides three very different layers:
1️⃣ Automation → rule‑based alerts, scheduled refreshes, threshold flags
2️⃣ Machine Learning → predictive models, anomaly detection, demand forecasting
3️⃣ Generative AI → natural language queries, auto‑summaries, report generation
None is superior. The right layer depends on your data maturity, process discipline, and decision infrastructure.
At Voiceback Analytics, we don’t chase the flashiest tech. We start with the business problem, then deploy the layer that delivers real operational value.
The question isn’t “Are you AI‑Powered?” It’s “Which layer, on what data, solving which decision?”
#AI #BusinessIntelligence #DataAnalytics #Voiceback #TravelRetail

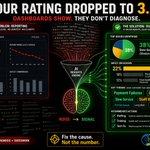
Your outlet rating drops to 3.5 stars. Dashboards report the fall. They don’t tell you why.
A 1‑star swing = 5–9% revenue impact.
We plug AI into feedback streams — turning thousands of unstructured reviews into actionable checklists:
38% slow service
22% inconsistent portions
15% payment failures
Dashboards show the problem. Diagnostics show the fix.
#CustomerExperience #AI #FNBOperations #Voiceback

Why does your AI give different answers to the same question?
Because it doesn’t retrieve answers. It generates them — one token at a time, probabilistically.
Two sources of variation: 1️⃣ Temperature → the “creativity dial.” Zero = repetitive. Higher = varied. 2️⃣ Hardware math → GPUs introduce microscopic rounding differences. Tiny flips cascade into different outputs.
Variation isn’t a bug. It’s a design choice. The real enterprise question: how much variation is acceptable, and how do you control it?
At Voiceback Analytics, we engineer systems where outputs are consistent enough to act on — without losing the reasoning flexibility that makes AI useful.
#AI #LLM #EnterpriseAI #Voiceback #OperationalIntelligence
Why “just feed it all our data” fails in AI.
Bigger context windows don’t mean better answers. Dumping your warehouse, SOPs, emails, catalogues into the model isn’t storage. It’s working memory under attention constraints.
Problems:
Lost in the middle → models attend to start & end, forget the middle.
Dilution → every token competes for attention weight.
Economics → 800k tokens cost 800× more than 1k curated tokens.
At Voiceback Analytics, our bots don’t dump data. We curate, select, and pull only what’s needed into context — engineered for the questions operators actually ask.
AI isn’t a container. It’s a reasoning engine. The layer that makes it usable is operational intelligence.
#AI #LLM #OperationalIntelligence #Voiceback #DataAnalytics
Half your menu gone at lunch rush — not because of waste, but because one base sauce ran out.
That’s the component cascade problem. Bad forecasting doesn’t just waste food. It wipes out customer choice.
At Voiceback, our ML models forecast at the BOM level — mapping shared components across dishes, predicting spikes, and alerting kitchens hours ahead.
Result: no stockouts, no lost favorites, no customer experience disasters.
#DemandForecasting #MenuAvailability #FNBOperations #AI

Your margin is 5%. Blanket 20% discounts erase it instantly.
Revenue spikes during sales, then drops as customers wait for the next one. You don’t drive growth — you train discount dependence.
We use behavioural clustering to design targeted upsells, not margin giveaways. Result: higher cart values, loyal full‑price customers.
#MarginProtection #CustomerSegmentation #FNBOperations #AI #FNBAnalytics

Why LLMs are worse at your spreadsheet than your PDF.
LLMs impress on contracts. Fail on structured data.
Summarise 40 pages? - ✅
Compute weighted margin across 12,000 SKUs? -❌
The reasons are architectural:
Tokenisation → numbers split into strings, no math sense
Schema loss → tables flattened, joins inferred, often wrong
Aggregation drift → filters dropped, rows skipped, duplicates double‑counted
LLMs don’t throw errors. They return confident, well‑formatted wrong answers.
Production analytics stacks don’t let the LLM do the maths. Pattern that works: Text‑to‑SQL + deterministic engine + validation layer. Language model handles language. Database handles computation.
At Voiceback Analytics, we’re the operational intelligence layer that makes AI usable in travel retail — bridging powerful models with real commercial decisions.
#AI #LLM #DataAnalytics #OperationalIntelligence #Voiceback
You’re paying 25% commission to rent your own customers. And a 1% reconciliation error just cost you crores.
Most F&B brands miss the second leak: aggregator reconciliation gaps. Platforms now drive 30–45% of revenue. Commission surged from 9.6% (2019) → 25% (2025). On top of that, small errors compound fast:
2 Cr GMV → 1% error = ₹2L/month → ₹24L/year lost.
Where gaps hide:
Cancelled orders logged as sold in kitchens
Discounts mismatched between POS & platform
Refunds processed without merchant notification
Commission tiers shifting mid‑month
By the time monthly reconciliation catches it, dispute windows have closed. Recoverable revenue becomes unrecoverable.
AI‑powered reconciliation fixes this. For a cloud kitchen client, variance dropped from 4.2% → 0.7% in one quarter. Over ₹30L annually recovered.
At Voiceback Analytics, we close margin gaps with real‑time operational data. Not dashboards. Not rearview mirrors. Systems that protect every rupee.
#analytics #F&B #Operations #AI
AI ≠ the operational layer.
Last year, the US DoD signed a $200M contract with Anthropic to deploy Claude. Palantir was already in the room. Claude didn’t replace Palantir — it ran through Palantir.
Because Palantir isn’t a model. It’s the pipelines, workflows, analyst interfaces, audit trails — the layer that turns raw AI output into a decision a commander can act on.
When the Pentagon blacklisted Anthropic, Palantir’s response was devastating to the hype: “We can replace Claude with another model. It makes no difference to us.”
Extend that logic to retail. A general AI can tell you Scotch prices are trending down. It cannot tell your Terminal 3 category manager what to do on Monday — given your margin structure, tenant agreement, promo calendar, competitor moves.
That’s not an AI problem. It’s a judgment problem. Generic AI commoditizes computation. It does not commoditize judgment.
At Voiceback Analytics, we’re not competing with AI. We’re the operational intelligence layer that makes AI usable in travel retail — bridging powerful models with real commercial decisions.
#AI #TravelRetail #OperationalIntelligence #Voiceback
Your dashboard told you waste was 18% yesterday. What did it tell you to do about tomorrow?
CXOs don’t need more dashboards. They need systems that act.
Static forecasting = expensive rearview mirror. ML forecasting = learns from errors, adapts, intervenes.
At Voiceback Analytics, we’ve cut waste from 18% to 5–8% for QSRs by deploying models that:
Predict demand shifts
Flag expiry risks
Trigger real‑time interventions
If your analytics isn’t learning daily, it isn’t analytics. It’s just reporting.
#AI #F&B #OperationalIntelligence #Voiceback
Generative AI was the lookup tool. Agentic AI is the next shift operators must understand.
Dashboards → ask, get answer. Agents → receive a goal, break it down, execute steps, check, iterate.
No human in the loop for each action. Powerful. Risky. An agent that misreads a constraint doesn’t just give a wrong answer — it acts on it.
At the APTRA conference in Bengaluru, our panel debated: 👉 Would you let AI run your company?
Consensus: The winners will be those who deploy AI with clear guardrails — where human judgment stays in the loop.
Autonomy is coming. The question is whether oversight is ready. See the video on our CEO bot - Chair
youtube.com/watch?v=C5ROQPLx…
#AI #AgenticAI #TravelRetail #OperationalIntelligence #Voiceback