

Everything AI-Marketing related
London
Joined September 2010
- Tweets119
- Following203
- Followers923
- Likes403




Whisper Create retweeted

In June I put 376 London startups on a map I built with AI.
It's now nearly 900 startups and coworking spaces, and the people using it took it places I never planned.
I built it because I kept leaving events and forgetting who I'd just met.
Then people I'd never met DMed to say they loved it. Students and folks new to the scene, like me, started using it to get their bearings. Startups started sharing their own pin.
Founders kept asking where to sit near the people they meet at events. Community managers asked which spaces could host a night. So coworking spaces went on. 53 of them now.
Got a proper video made this time. Thanks to Adam Toth for filming it 🎥
Biggest lesson: building it with AI was the fast part. Listening to the people using it is what made it useful.
Founders: not on it yet? Reply with yours 👇
🗺️ londonstartupmap.com

Cognition just published an open standard for git-backed agent memory. It confirms what I have been building for the last year really is the future. CONVENTIONS.md is the key to portable memory and architecture. That is where it all starts.


I wonder if it's just model behaviour rather than a nerf. With video and image models, the same prompt in Seedance 2.5 or ChatGPT Image 2.5 sometimes gives something slightly different. Are text models doing the same?

Does Vibe Coding need a new name?
Initially it was extremely non technical people (like me), neandathralling through a code base.
But now, we have the most intelligent people in world, who no longer write code, instead review and provide guidance - through natural language.
Okay you got me. I thought my eye was well trained with ai video and imagery…but damn. This is something else. Congrats @tavus on the release.

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Readers added context they thought people might want to know
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
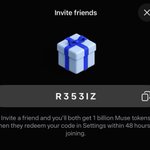
Join Muse via my invite code (R353IZ) so we can both get 1 billion tokens each and access to the voice calling feature.
To redeem just go to muse.ai to sign up and pop in my code.
Code is only good for 20 uses so first come first served.

Dumber if you're using it for things you're already very good at and faster at.
Smarter if you're learning new intricacies about a new skill you never dreamed you'd be able to attempt.

Whisper Create retweeted

Real-world results are in. There is a new #1 on Code Arena - GPT-6 Astra (Max)!
It also reshapes the Pareto frontier as the best-performing model at $40/Mtoken, which matches the latest Claude model pricing.
GPT-6 Astra by @OpenAI takes the top spot in Code Arena: WebDev with a score of 1797 pts. This opens up a solid +35pt lead over #2 Claude Fable 5.1 (Max) at 1762 pts and #3 Claude Opus 5 (Max) at 1688 pts.
This is a significant improvement from GPT-5.6 Sol (xHigh) at +180 pts, ranked at #13.
Category level votes still incoming, but already we see it at #1 in: Data & Analytics, Consumer Product, Content Creation Tools and #2 in Gaming and Simulations.
Stay tuned for other categories like Brand & Marketing, Reference-Based Design and Full Stack rankings.
Congrats to the @OpenAI team on this release!


The creative work should have the model relying on your design/ brand guidelines 8 taste. Not the other way around. I’ve never understood the notion of giving 100% design thinking power to the model. A world class human designer still asks what their clients brand guidelines are.

I wonder whether @AnthropicAI will now be forced to let pro users have access to Fable. It’s currently now only available for Max subscribers. Whereas @OpenAI’s Astra will be available for all subscriptions, including their 20usd plan.


Fork the @blocks Berd app. It’s open source and does exactly this.


I'm at 0% on Codex, but im not even going to touch the banked reset. I'm rinsing Ox Alpha until the 27th. It's currently faster and better than.
whispercreate.com

Very interesting.
whispercreate.com

Announcing our new Speech Agent Arena, evaluating Speech to Speech models on real-world scenarios to analyze conversational preference and task success rate
Existing Speech to Speech benchmarks cover reasoning, simulated agentic tasks, and conversational dynamics such as turn-taking and interruption handling. The Speech Agent Arena compares models and cascaded systems as humans complete real-world tasks, measuring conversational preference and successful tool use. This allows us to provide an evaluation which closer reflects real-world use, offering insight into which models users most prefer speaking with and how effectively those models support their requests.
Overview of the Speech Agent Arena and Task Success Rate
Human participants compare two hidden Speech to Speech models on the same assigned scenario, one of 15 agentic scenarios (tasks requiring tool calling, such as ordering takeout) or 20 non-agentic scenarios (tasks without tool calling, such as asking about opening hours). After separate live conversations with each model, participants select which they preferred, with these pairwise votes used to fit a Preference Elo score. For agentic scenarios, Task Success Rate is the share of eligible conversations (no participant deviations or unverifiable cases) where the model completed the requested action through the correct final tool call or calls.
For all but a New Patient Dental Booking example, scenario model prompts, tool schemas and participant instructions are currently private to reduce overfitting. Additionally, the Speech Agent Arena currently uses a qualified pool of paid, screened third-party participants to conduct and evaluate agent interactions.
Key results:
➤ Arena Preference Elo: @GoogleAI Gemini 3.1 Flash Live Preview - Minimal leads at 1,046 Elo, followed by Gemini 3.1 Flash Live Preview - High at 1,014, @OpenAI GPT-Realtime-1.5 at 1,000, GPT Realtime (Aug '25) at 944, and @ElevenLabs Agents (default cascaded system of Scribe v2 Realtime / GPT-4o Mini / Eleven v3, with pre-registered tool schema) at 937. In reviewed conversations, highly preferred models tended to respond quickly, sound more natural and produce fewer unnatural sounds or audio artifacts
➤ Task Success Rate: @spacexai Grok Voice Think Fast 2.0 High leads at 94.7%, followed by @OpenAI GPT-Realtime-2.1 High at 91.5%, @ElevenLabs Agents (Default Cascaded System) at 90.5%, and GPT-Realtime-2 (High) at 89.8%, with GPT Realtime (Aug '25) and GPT-Realtime-2.1 Minimal tied at 89.4%. Gemini 3.1 Flash Live Preview - Minimal leads overall preference at 1,046 Elo but records a 74.6% Task Success Rate, showing that a preferred conversation does not always result in successful task completion - some conversations can sound as though the requested action was completed even when the required final tool call was unsuccessful
We are continuing to expand our coverage of native and cascaded Speech to Speech systems, and welcome feedback as we add more models, providers and scenarios.
See more details below ⬇️

This time next year we will all have unlimited & private Fable level intelligence in our pockets. Ladies and Gentlemen, we're living in some wild wild times.
whispercreate.com

We just released Qwen3.8-27B MLX quants. 🍎🐳
This time: the official Qwen3.8-27B, packaged for Apple Silicon + MLX.
4-bit · 6-bit · 8-bit
Up to 98.34% Top-1 agreement vs BF16.
Native MLX weights. No GGUF conversion required.
Fast. Private. Local. Have fun!
→ huggingface.co/orcarouter/Qw…


My thoughts on @blocks Buzz and Berd.
I see Buzz as the (original) better and free version of Grokbot. Plus you can fork it and add any features you want. & i see Berd as the alternative to Cursor where you can easily switch between different agent models + internal org comms.

Great news, however this banked reset will probably last a day. + it will push our reset ahead a day so we'll be back to square 1. @thsottiaux
It's me again. I come bearing great news.
First of all, we have hit 20M active users for Codex some time this week. Second of all, this is cause for celebration and during the day we will credit every Codex and ChatGPT Work user with a BANKED reset that you can use at your own leisure. And we will have some other good news later too!
Now, on usage limits draining faster, while we're not seeing anything abnormal, we do take it incredibly seriously and there is an ongoing investigation. I will share if we do find anything and my below post is really a clarification on a specific pattern that we did see that I wanted to call out.
Go do something amazing today.