

developing embodied ai agents that empower users to use language to interact with digital and physical environments to carry out real-world tasks.
Joined July 2023
- Tweets143
- Following36
- Followers1.6K
- Likes160






Pinned Tweet
Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
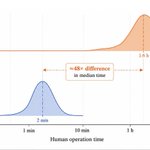
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
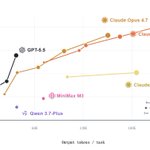
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted

Join @yuan_mengq43669 of @XLangNLP and @HKUniversity for our first-ever virtual Snorkel AI Reading Group, presenting OSWorld 2.0. RSVP: luma.com/ku4blx0q
Mengqi will explore what it takes to evaluate agents on realistic, long-horizon computer-use workflows, why partial-credit scoring reveals meaningful progress agents rarely convert into end-to-end completion, and where current systems still lose the thread.
XLANG NLP Lab retweeted

💻 Meet Qwen-CUA — our native computer-use agent for (almost) everything.
Code, APIs, and computer use are three of the most important interfaces for agents. Today’s models are already highly capable with the first two. Qwen-CUA is built to unlock the third: graphical interfaces designed for people.
👀 Native Perception — screenshots only. No DOM, accessibility tree, or other hidden machine-readable state.
🖱️ Native Interaction — keyboard and mouse events across browsers, desktop apps, and professional software. No task-specific APIs.
🧠 Native Intelligence — maintains long-horizon visual context, verifies progress, and learns from large-scale interactive experience with verifiable outcomes.
To make native computer use trainable at scale, we built approximately 40K verifiable tasks and rollout infrastructure with nearly 100K vCPUs, supporting tens of thousands of concurrent environments.
Across eight computer-use benchmarks spanning everyday desktop use, long-horizon workflows, personalized computing, scientific research, web interaction, macOS, and adversarial robustness, Qwen-CUA demonstrates strong and broadly competitive capabilities. Scaling the same recipe to Qwen-CUA-Max pushes this frontier further.
Not just “clicking the screen” — native computer use unlocks software and workflows that previously required a human at the keyboard. Together with code and APIs, it completes the interface stack for more general agents.
Joint work by Qwen Team × XLang Lab.
📖 Technical Report:
github.com/xlang-ai/Qwen-CUA…
💻 Code:
github.com/xlang-ai/Qwen-CUA


Congrats the Claude team on the big jump on OSWorld!
Worth flagging this 70.6% is partial-credit scoring — under strict binary task-level success (OSWorld 1.0-style), Opus 5 is still only ~30%.
We're working on improving task quality so task-level binary success becomes more robust and reliable even on hard tasks too.


XLANG NLP Lab retweeted

Exciting to see progress in long-horizon computer use with the GPT-5.6 release.
Glad that OSWorld 2.0 is being used to measure end-to-end computer-use workflows in realistic, complex environments.
Computer use is moving fast. Looking forward to more results from the community🙌


XLANG NLP Lab retweeted

OSWorld 2 is taking CUA evaluation to the next level of complexity and realism. Congrats to the team! Glad to contribute to this important effort.

Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted

i still remember the discussion of the case of us visa application and i thought that must be mission impossible for ai and just said u guys must be crazy... now it seems that i am the dumb hahah!
anyway, time for frontier models to fight again! bon courage!
Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted
108 real-world, long-horizon computer-use workflows. Average rollout: 318 tool calls.
Top frontier agent (Claude Opus 4.8 with max thinking + batched tool calls): 20.6% end-to-end completion (54.8% partial progress). Partial progress is real. Reliable end-to-end computer use is not.
Proud to be @XLangNLP's research and data partner on OSWorld 2.0. @qi_zhengyang, @vincentsunnchen, and @fredsala contributed from Snorkel.
Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted

From OSWorld 1.0 to 2.0, we went from minutes (~30 steps) to hours (~318), from single apps to real workflows, from high scores (83%) to hard problems (21%).
1+ year, 20+ people, every task rigorously verified. This is what real cua evaluation takes.🙏
👉osworld-v2.xlang.ai

Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted

OSWorld 2.0 is here.
This is a new batch of ever solid tasks for CUA. Leading us to the next stage of changing the way we let AI free humans’ labour.
Congrats and be proud of the team.
Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
XLANG NLP Lab retweeted
After 15+ months of work, I’m thrilled to finally share OSWorld 2.0 🚀
Huge thanks to all the collaborators, advisors, and friends who supported this project from early ideas to release.
Hope OSWorld 2.0 helps push the CUA forward. Excited to hear feedback and discuss more!🙌
Two years ago, we built OSWorld 1.0 — the benchmark that became the standard for computer-use agents. Agents now score 83.5% on it. Problem solved?
Not even close.
🚀Today we introduce OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks.
What's new:
🎯 108 real-world workflows, each ~1.6 hours ⏱️ for a skilled human
⚙️ ~318 tool calls/task vs. ~30 in OSWorld 1.0
🌍 Grounded in authentic artifacts & stateful user profiles
⚡ Captures real phenomena: dynamic environments, streaming interaction, cross-source reasoning, implicit-state inference & more
📊 Best results: Claude Opus 4.8 reaches the highest accuracy at 20.6%, while GPT-5.5 is far more token-efficient but plateaus near 13%. No one is close to solving real computer use.
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
🧵 [1/8]
🧵[7/8]
Contributions and Acknowledgments
Huge thanks to the amazing team behind OSWorld-V2 🚀 Led by @yuan_mengq43669, @adlsdztony1 & Xinzhuang Xiong, with@xhluca, @saa1605, @itsyuhao, @jiaqideng07, @xywang626, @DunjieLu1219, @BowenWangNLP, @vincentsunnchen and the whole XLANG crew making it happen.
Deepest gratitude to @taoyds for steering the project, and to our advisors @TianbaoX, @fredsala, @zhouyu, @ysu_nlp, @sivareddyg, @xwang_lk, @JustinLin610, @dayiheng_liu & @PengQi for their guidance throughout 🙏
We thank @SnorkelAI, our research & data partner, for their support of this work. We gratefully acknowledge support from the @GoogleResearch gift fund.
🧵[8/8]
OSWorld 2.0 is built to make long-horizon computer-use evaluation realistic, inspectable, and reproducible.
We believe the next leap in computer-use agents won't come from better GUI clicking — it will come from agents that can read instructions, gather evidence, track state across hundreds of steps, resolve conflicts, and verify their own outputs before submitting.
OSWorld 2.0 is designed to measure exactly that gap — and to drive the field toward closing it.
We release everything to support the community:
🏠 Homepage: osworld-v2.xlang.ai
📄 Paper: github.com/xlang-ai/OSWorld-…
💻 Code: github.com/xlang-ai/OSWorld-…
🤗 Dataset: huggingface.co/datasets/xlan…
📦 Trajectories: huggingface.co/datasets/xlan…
🧭 Trajectory Viewer: osworld-v2-monitor.xlang.ai

XLANG NLP Lab retweeted

Current robot policies overfit specific language templates, handling 'pick and place' but freezing on 'drag it to me ' or 'push it closer to me.' They also lack control over execution: which hand, what approach angle, where to grasp, which path to follow.
🤖 FineVLA make robots steerable : changing instruction alters execution; same task, different phrasing, distinct actions — all faithfully done.
🏠 Homepage: finevla.xlang.ai
📄 Paper: huggingface.co/papers/2605.2…
💻Codebase: github.com/xlang-ai/FineVLA
🧵[1/6]
XLANG NLP Lab retweeted

RLVR has become the recipe for agentic post-training. But for Computer-Use Agents, the bottleneck is not the algorithm, it is the data. 🐌
🚀 We introduce CUA-Gym: a scalable, lightweight synthesis engine that turns arbitrary task queries into verifiable RLVR data for computer-use agents. The largest open CUA RLVR dataset to date:
🎯 32,122 verifiable RLVR tasks with programmatic setup scripts + rewards
🌐 110 environments: 16 desktop apps + 94 synthesized mock web apps
🏆 Qwen3.5-based CUA models trained with GSPO reach 72.6% on OSWorld-Verified and 56.6% on WebArena
📄 Paper: huggingface.co/papers/2605.2…
🏠 Homepage: cua-gym.xlang.ai
🤗 Dataset: huggingface.co/datasets/xlan…
💻 Codebase: github.com/xlang-ai/CUA-Gym
🧩 Environments: github.com/xlang-ai/CUA-Gym-…
🧵[1/6]