
PhD student at Stanford
Joined May 2019
- Tweets40
- Following239
- Followers3.3K
- Likes166




Xiang Lisa Li retweeted
What would truly open-source AI look like? Not just open weights, open code/data, but *open development*, where the entire research and development process is public *and* anyone can contribute. We built Marin, an open lab, to fulfill this vision:

Xiang Lisa Li retweeted
When @XiangLisaLi2 built diffusion LMs in 2022 (arxiv.org/abs/2205.14217), we were interested in more powerful controllable generation (inference-time conditioning on an arbitrary reward), but inference was slow. Interestingly, the main advantage now is speed. Impressive to see how far diffusion LMs have come!


Xiang Lisa Li retweeted

I’m hiring PhD students in computer science at Columbia!
Our lab will tackle core challenges in understanding and controlling neural models that interact with language.
for example,
- methods for LLM control
- discoveries of LLM properties
- pretraining for understanding
Xiang Lisa Li retweeted
This year, I have 4 exceptional students on the academic job market, and they couldn’t be more diffferent, with research spanning AI policy, robotics, NLP, and HCI. Here’s a brief summary of their research, along with one representative work each:
Xiang Lisa Li retweeted
Lisa Li (@XiangLisaLi2) changes how people fine-tune (prefix tuning, the original PEFT), generate (diffusion LM, non-autoregressively), improve (GV consistency fine-tuning without supervision), and evaluate language models (using LMs). Prefix tuning:
arxiv.org/abs/2101.00190
Can we get language models to exhibit certain behaviors?
We train investigator models to elicit target behaviors from LMs, which helps us proactively detect harmful responses and hallucination!

Excited to finally share what I’ve been up to at @TransluceAI: training Investigator Agents to elicit behaviors in LMs (including harmful responses and hallucinations)!
Xiang Lisa Li retweeted

Eliciting Language Model Behaviors with Investigator Agents
We train AI agents to help us understand the space of language model behaviors, discovering new jailbreaks and automatically surfacing a diverse set of hallucinations.
Full report: transluce.org/automated-elic…

Xiang Lisa Li retweeted

Introducing *Transfusion* - a unified approach for training models that can generate both text and images. arxiv.org/pdf/2408.11039
Transfusion combines language modeling (next token prediction) with diffusion to train a single transformer over mixed-modality sequences. This allows us to leverage the strengths of both approaches in one model. 1/5


arxiv.org/abs/2407.08351
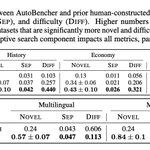
LM performance on existing benchmarks is highly correlated. How do we build novel benchmarks that reveal previously unknown trends?
We propose AutoBencher: it casts benchmark creation as an optimization problem with a novelty term in the objective.

Other than knowledge-intensive QA, we use AutoBencher to create datasets for math and multilingual. The scalability of AutoBencher allows it to test fine-grained categories and tail knowledge, creating datasets that are more novel and more difficult than existing benchmarks.

Exciting joint work with
evanliu,
@percyliang
@tatsu_hashimoto
🙂Code available at
github.com/XiangLi1999/AutoB…

Xiang Lisa Li retweeted

New from @GoogleDeepMind: When can you trust your LLM? We show that LLMs consistently overestimate their own accuracy on some topics (eg nutrition) while underestimating it on others (eg math). Our Few-shot Recalibrator fixes LLM over/under-confidence: arxiv.org/abs/2403.18286 🧵
Xiang Lisa Li retweeted

Prompting is cool and all, but isn't it a waste of compute to encode a prompt over and over again?
We learn to compress prompts up to 26x by using "gist tokens", saving memory+storage and speeding up LM inference:
arxiv.org/abs/2304.08467 (w/ @XiangLisaLi2 and @noahdgoodman)
🧵


Xiang Lisa Li retweeted
The #cs224n poster session is happening now! We are super excited about amazing, cutting-edge NLP posters from ~650 students!


Xiang Lisa Li retweeted
Introducing Demonstrate–Search–Predict (𝗗𝗦𝗣), a framework for composing search and LMs w/ up to 120% gains over GPT-3.5.
No more prompt engineering.❌
Describe a high-level strategy as imperative code and let 𝗗𝗦𝗣 deal with prompts and queries.🧵
arxiv.org/abs/2212.14024


Xiang Lisa Li retweeted

🙋♀️How to present the same text in diff. tasks/domains as diff. embeddings W/O training?
We introduce Instructor👨🏫, an instruction-finetuned embedder that can generate text embeddings tailored to any task given the task instruction➡️sota on 7⃣0⃣tasks👇!
instructor-embedding.github.…
