

We make tinygrad; sell tinybox for the GPU middle class. Our mission is to commoditize the petaflop.
San Diego / Hong Kong
Joined June 2023
- Tweets5.2K
- Following210
- Followers84K
- Likes951







The 10-411: Compilers for Machine Learning course will be aggressively tested by LLMs by the time it's ready for students. GPT thinks week 4 will be the hardest.


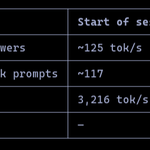
Now benchmarked at 3200 tok/s prefill and 220 tok/s decode on a $19k base model tinybox red flash. Test API available to everyone with access to our network. More benchmarks incoming. This deal will not last!

GLM-5.3-Flash now at 3200+ tok/s prefill, 155+ tok/s interactive decode on a $19k tinybox red flash. Get yours before prices go up!


GLM-5.3-Flash now at 3200+ tok/s prefill, 155+ tok/s interactive decode on a $19k tinybox red flash. Get yours before prices go up!
With the MI355X generation and great software improvements, AMD is now NVIDIA tier. And with NVIDIA pulling the 5090, their consumer GPUs are competitive too.
It's a damn shame Intel doesn't have people to antagonize on Twitter. They could be next, but alas, no leadership.


It's so nice to finally have a usable model running on hardware we built in tinygrad. Works end to end in pi.
Getting 300/53 tok/s prefill/decode, should be at 2000/100 soon. 5000/250 is doable with speculation and more work.
In 6 months, when everyone is running GLM-5.3 flash sized models at home and the required box costs $50k, you are going to be mad you didn't buy one of these now.
It is sad that @finkd @alexandr_wang @Meta felt the need to nerf their open release so badly. I mean, it's fine as a statement to the wannabe intelligence rent seekers, but they had an easy option to be the top open source model on @ArtificialAnlys and they didn't take it.

Accelerator companies focusing on inference and tok/s at the expense of fundamentals is a serious mistake. LLMs are just a small part of all the things that will be built with AI in the future.
By the end of week 5 in 10-411, you'll have written an MNIST trainer and Qwen3 runner using your compiler. Week 6-10 will focus on GPU usage and performance. Guess the line count?

Simple specs can give rise to huge complexity. Buffers are initialized with 0. What's in result after this runs?

Ours is $19k with 192GB of VRAM


Local AI is good enough for a startup. A 10-person startup built its own 128GB-VRAM AI server for $18,000.
One Threadripper box sitting locally with
🎮 4× Radeon AI PRO R9700 32GB
💾 128GB total VRAM
🧠 Qwen3.8 + DeepSeek V4 Flash
👥 16 concurrent AI sessions
And they're actually pushing it.
Qwen3.8-Flash-Next with 16 simultaneous sessions:
📚 48K context/user
⚡ 538.5 tps aggregate decode
At 128K context per user
⚡ 365 tps aggregate decode
The GPUs are even undervolted to under 210W each.
Link in ALT

ALT https://www.reddit.com/r/LocalLLaMA/comments/1x2u742/building_a_4x_r9700_setup_for_a_10_person_startup/
We shipped the simple configuration for the most commonly chosen builds + the brand new $19k tinybox red flash. Compare the GPU RAM and GPU bandwidth to the NVIDIA version, AMD is a good deal!

Sorry, I got the price wrong for the GLM-5.3 flash machine. 250 tok/s should be doable with decent software. Buy today!

These AMD GPUs have the same RAM and similar power to 2x RTX6000s but are $26,000 cheaper. tinygrad.org/
