


Albert Gu retweeted

Releasing FLAT: Flash Linear Attention on TPUs 🚀
Pallas training kernels for Linear Attention, Mamba-2 and GLA. On one TPU v6e, forward + backward is up to 3x faster than FLA on an H100 for GLA, and 1.5x faster for Mamba-2.
🧵

transformer inference has had dozens of tricks optimized by the entire ecosystem, there are still many ideas and optimizations waiting to be discovered for alternative architectures!

ReplaySSM now runs in production in GLM-5.3-Flash and Kimi-K3, and ships in TensorRT-LLM, vLLM, FlashInfer, and SGLang!
It speeds up standard decoding (up to 1.47x) and speculative decoding (up to 2.1x), and now also enables a low-precision SSM state whose rounding error never propagates through the recurrence.
Building on our earlier ReplaySSM work, we collaborated with @NVIDIA to pin down what the method really unlocks. Caching SSM inputs instead of the state is what ReplaySSM does. What it changes is that computing the output and updating the state can be separated during decoding. All three gains follow from that separation.
Joint blog post, paper, and code with @NVIDIA and @tri_dao 👇

really excited to see an application built on top of Hydra (bidirectional Mamba arxiv.org/abs/2407.09941)!
at small scales we had done some DNA language modeling and found evidence that Mamba is better than Transformers and convolutions; this paper from a serious bio group shows that it allows modeling at higher nucleotide resolution and improves performance on various genomic prediction tasks


This week we're releasing a preprint exploring state space models for long-sequence genomic prediction, alongside Cerberus, a set of open PyTorch models built on this work. biorxiv.org/content/10.64898…


chat with your model with a single identity across languages and accents!

Introducing Multilingual Voices
We partnered with Baklavastory, our neighbor in the Mission, to show what it sounds like when a business's character and warmth stay consistent, no matter who calls or what language they speak.
It's easy to translate speech, but much harder to preserve a single identity across languages. Every language has different rhythms, tones, and emphasis. When you change the language, identity tends to get lost in that shift, and your voice ends up sounding like someone else.
With Multilingual Voices, pick a voice and keep one brand identity in every market you serve: cartesia.ai/voices

misleading paper title, and even the phrasing in the tweet is still a misnomer. this is not about "post-training" but "retrofitting" (cross-architecture distillation)
fwiw i've been bearish on distilling Transformers to recurrent models for a while, they're too different; architectural innovations just need to be trained from scratch

Simple beats complicated:
We show that switching to a sliding-window attention mask with attention sinks (at no cost) beats linear attention post-training.
Huge thanks to my collaborators @RheaSukthanker, @CameronPashmina, and @Emy_Aze.
Paper: arxiv.org/abs/2608.28444
Albert Gu retweeted

Cartesia Sonic-3.6 is the #1 TTS model on the Voice Arena US English 🇺🇸 Leaderboard.
It debuts at 1085 Elo, in a statistical tie with Google DeepMind's Gemini 3.1 Flash TTS, and ahead of its own Sonic-3.5, Simba 3.2 and Grok TTS. It holds the top spot as a real-time model.
Sonic-3.6 is the latest TTS model from @cartesia. The model has been highly preferred among raters on @voicearena_ai.
Results backed by 1,400+ blind, head-to-head listener votes across two languages 🧵

sonic-3.6 is out, with a large improvement over (the already #1) sonic-3.5 in just a few months! the research team's focus on fundamentals is accelerating progress at the frontier of architectures and audio
Sonic-3.6 is now generally available.
In January we made a bet: stop tuning the existing paradigm, rebuild from the architecture up.
How we topped our own best model in two months → cartesia.ai/blog/sonic-3.6/?…
Albert Gu retweeted

Introducing Sonic-3.6: our most lifelike TTS yet, and another step change in naturalness across 44 languages. Just three months after our Sonic-3.5 launch, we've made fundamental model improvements based on feedback from the teams building on Sonic.
We're #1 on @ArtificialAnlys across both the provider and controlled voice streaming leaderboards — best-in-class voices + the best underlying model.
Available in beta today. Hear it for yourself 👇


the team continues cooking 👩🍳
this is now an unprecedented gap on both the super competitive Provider Voices leaderboard as well as the newer Controlled Voices leaderboard (a stronger benchmark that can't be benchmaxxed, requiring truly better algorithms)
Cartesia's TTS model is not only the best, it continues improving at a faster rate than the competition - Sonic 3.5 was released only 3 months ago. ig Sonic now means both the fastest model and the fastest team 💀


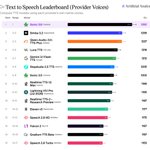
Cartesia's Sonic 3.6 takes the #1 spot on both the Provider Voice and Controlled Voice Artificial Analysis Speech Arena leaderboards, surpassing Speechify AI's Simba 3.2 and Alibaba's Qwen-Audio-3.0-TTS-Plus, with Sonic 3.5 holding #2 on Controlled Voice
Sonic 3.6 is the latest TTS model from @cartesia, supporting 40+ languages including English, Hindi, Spanish, French, German and Japanese. In the TTS Arena, the model has been preferred by voters and has demonstrated natural speech and adaptive pacing across conversations.
Key takeaways:
➤ Controlled Voice: Sonic 3.6 takes #1 on the Controlled Voice Arena with an Elo of 1,144 (+18/-18) across 1,339 appearances, ahead of Cartesia's own Sonic 3.5 at 1,099 and ElevenLabs' Eleven v3 at 1,060
➤ Provider Voice: Sonic 3.6 also takes #1 on the Provider Voice Arena with an Elo score of 1,286 (+19/-19) based on 1,300 arena appearances, placing it ahead of Simba 3.2 at 1,238 and Qwen-Audio-3.0-TTS-Plus at 1,237
➤ Pricing: At $49 per 1M characters via the Cartesia platform, Sonic 3.6 is the most expensive of the top three models on quality, roughly 5x Speechify AI's Simba 3.2 at $10 and nearly double Alibaba's Qwen-Audio-3.0-TTS-Plus at $27.59, though still half the price of ElevenLabs' Eleven v3 at $100
➤ Speed: Sonic 3.6 processes 136.1 characters per second of generation time, compared to 46.7 for ElevenLabs' Eleven v3 and 24.2 for Google's Gemini 3.1 Flash TTS
Albert Gu retweeted
A very happy 80th Independence Day to India, from team Cartesia! 🇮🇳
Coming closer to home with Sonic 3.6, we're making every one of India's languages more natural, expressive, and accurate:
- Hindi that flows the way you speak it
- Hinglish that switches without missing a beat
- Naturalness gains across all 9 existing Indic languages
- Plus two new languages: Urdu and Odia
Every voice in this video generated by Sonic.
Albert Gu retweeted

Excited that @cartesia is in @cursor_ai's India campaign with some of the most ambitious founders of Indian origin (including in Delhi where I grew up)
featuring amazing folks @amanrsanger, @vipulved, @tankots, @mukundjha, @ManishaRaisingh, @regards_rishi, @_sankyy

Albert Gu retweeted
Our London office is growing quickly, reach out to @_albertgu or me if you’d like to work on a very different, new and exciting research agenda to advance multimodal models

Good night DeepMind. Wow.
FT: "Google is shifting control of its AI effort from London back to Silicon Valley"
"executives and board members remained concerned by its weaker position in coding models and enterprise AI, where Anthropic and OpenAI have established an early lead."
"Several current and former DeepMind employees said the reorganisation had sent shockwaves through the London-based lab, with some fearing it marked the end of the research culture that Hassabis has long protected. One former DeepMind executive at a rival company said they had already received calls from multiple staff who said they were ready to jump ship."
"Over the past year, Hassabis has devoted more time to Isomorphic Labs, the AI drug discovery company he founded"
Evaluations are difficult and vague for all generative models, and benchmarks only capture a small slice. Our blog post dives into the nuances for TTS
"Is this TTS model good?" gets harder to answer as models improve.
"Good" is at least five axes: correctness, naturalness, contextual correctness, robustness, and most evals only capture the first.
We wrote up the failure modes that make TTS eval hard: cartesia.ai/blog/is-this-tts…

Albert Gu retweeted
.@_albertgu and I are organizing a research happy hour in London on Monday July 13th.
Come hang out!
luma.com/3p1u9pgf

Cartesia is hosting an ICML party tomorrow (Thursday) night! it'll go late, but come early or i may have to bounce you again
luma.com/gy1b4ryq

Albert Gu retweeted

We will be at ICML in Seoul to present dnaHNet in Oral + Poster sessions! Swing by and say hi if you wanna learn about the current SOTA in DNA foundation models :)
Oral session: Hall D2 at 10 AM, Jul 7
Poster session: Hall A #900 at 2 PM, Jul 7

Most genomic AI models use fixed rules to process DNA into chunks, imposing arbitrary boundaries on a sequence with its own biological structure.
@arnavshah0, @victor_ljz, and team developed dnaHNet, a tokenizer-free foundation model that learns its own segmentation from scratch, supervised by @_albertgu, @genophoria, and @BoWang87.

Transformers are better at copying, while RNNs are better at modeling "meaning-bearing words—the nouns, verbs, & adjectives that say what a sentence is about"

