Research Fellow & Final-year PhD candidate @SheffieldNLP. Previously NLP researcher at @hitachi. Views are my own. #NLProc
Sheffield, England
Joined March 2019
- Tweets520
- Following453
- Followers503
- Likes1.3K
Pinned Tweet
A last piece of my PhD work is out!
arxiv.org/abs/2609.39827
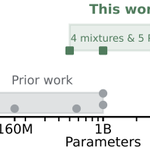
We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale.
This is the largest ever PPT study! (1/5)
Atsuki Yamaguchi retweeted
Excited to present our paper at #EMNLP2026: "When Tokenizers Fail: Byte-Level Chunking for Zero-Shot Transfer to Low-Resource Languages" (Main Conf)!
With @_gucciiiii & @nikaletras (@SheffieldNLP).
🎯 Final-year PhD @CSE_IITBombay: seeking Postdoc/RS roles for mid-2027. 🧵👇
I'm attending EMNLP in person next week. If you are around, let's have a chat!
With #EMNLP2026 just around the corner, a reminder of the EMNLP papers from Sheffield NLP!
If you're attending, do check out our papers and say hi to the authors! Looking forward to seeing everyone at EMNLP!
Atsuki Yamaguchi retweeted
There's going to be a little army of us coming to #EMNLP2026 from @sheffieldNLP 😅 Come say hi!
With #EMNLP2026 just around the corner, a reminder of the EMNLP papers from Sheffield NLP!
If you're attending, do check out our papers and say hi to the authors! Looking forward to seeing everyone at EMNLP!
Emails sent to [email protected] are often quite rude. Before pressing send, please keep in mind that ARR is run mostly by volunteers. PLEASE TREAT US WITH RESPECT!
#ARR @ReviewAcl
We have just implemented a self-assessment checker for this and now deployed at aclrollingreview.org/qualifi….
Atsuki Yamaguchi retweeted
📢 ARR Reviewer Qualifications Checker is Live!
For the Oct cycle, each submission must name a qualified service contributor to be guaranteed review.
Before submission, you can quickly verify your status: openreview.net/group?id=aclw…
Policy: aclrollingreview.org/sustain…
#ARR #NLProc
Delighted that our paper received an Outstanding Paper Award at COLM 2026! 🏆
Though I couldn't make it to SF, stop by our oral at 3:30 PM and poster session at 4:30 PM today, presented by @joelniklaus!
@COLM_conf
Congratulations to the authors of the 3 outstanding papers!
arxiv.org/abs/2607.01077
arxiv.org/abs/2604.08510
arxiv.org/abs/2604.13977
Atsuki Yamaguchi retweeted
In San Fransisco for #COLM2026 🌉 If you are here come say hi and check out our poster tomorrow (Wed 7th). @danaesavi and I will be presenting, “Reasoning Dynamics and the Limits of Monitoring Modality Reliance in Vision-Language Models”. Poster link: colm.cc/virtual/2026/poster/…
Atsuki Yamaguchi retweeted
Super excited to share that FinePhrase has been selected as an Oral Spotlight at #COLM2026!
I will present on Wednesday afternoon next week. First in Oral Session 4 at 3:30PM PT and then in Poster Session 4 between 4:30 and 6:30PM (Poster F-4-126).
If you're in SF, I am looking forward to seeing you at the talk or in the poster session!
What is FinePhrase all about?
Synthetic data is a standard component in training large language models, yet systematic comparisons across design dimensions, including rephrasing strategy, generator model, and source data, remain absent.
We conduct extensive controlled experiments, generating over one trillion tokens, to identify critical factors in rephrasing web text into synthetic pretraining data.
Our results reveal that structured output formats, such as tables, math problems, FAQs, and tutorials, consistently outperform both curated web baselines and prior synthetic methods.
Notably, increasing the size of the generator model beyond 1B parameters provides no additional benefit.
Our analysis also demonstrates that the selection of the original data used for mixing substantially influences performance.
By applying our findings, we develop FinePhrase, a 486-billion-token open dataset of rephrased web text.
We show that FinePhrase outperforms all existing synthetic data baselines while reducing generation costs by up to 30 times.
We provide the dataset, all prompts, and the generation framework to the research community.
Listen to the paper to learn more: alphaxiv.org/abs/2604.13977v…
Thanks to all my collaborators without whom this work would not have been possible! @_gucciiiii, Michal Štefánik, @gui_penedo, @HKydlicek, @eliebakouch, @_lewtun, @edwardbeeching, @thibaudfrere, Colin Raffel, @lvwerra, @Thom_Wolf
Atsuki Yamaguchi retweeted
Happy to be part of your final PhD work~!
The paper explores how well pre-pretraining(PPT) works across various settings
大規模学習を山口さんがたくさん頑張ってるのを傍目で見ながら、データ整備周り等を少しお手伝いさせてもらいました!
A last piece of my PhD work is out!
arxiv.org/abs/2609.39827
We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale.
This is the largest ever PPT study! (1/5)
Atsuki Yamaguchi retweeted
Prior work studied pre-pretraining (PPT) on small models and token budgets only. We scale it up to 7B parameters and 100B pretraining tokens across 4 data mixtures and 5 PPT tasks.
We conclude that PPT is beneficial at larger scale, saving at least 21B PT tokens at the 3B scale.
Listen to our paper to learn more: alphaxiv.org/pdf/2609.39827
A last piece of my PhD work is out!
arxiv.org/abs/2609.39827
We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale.
This is the largest ever PPT study! (1/5)
Atsuki Yamaguchi retweeted
Pre-pretraining still works when scaling to 7B models but not for the reasons that it works in smaller models (up to ~1B) 👇
A last piece of my PhD work is out!
arxiv.org/abs/2609.39827
We ask whether "pre-pretraining" (PPT) (i.e., training on synthetic non-natural language data briefly prior to pre-training on natural language data) helps at scale.
This is the largest ever PPT study! (1/5)
We also conduct various pre-training data sweep experiments. For details, please check out our preprint: arxiv.org/abs/2609.39827
Code is available at github.com/gucci-j/verify-pp…
Models and data are available at huggingface.co/verify-ppt
(4/5)
Work done with @Ina_pfgt @joelniklaus Michal Štefánik @AlineVillav @nikaletras (5/5)
P.S. We are adding more experiments (e.g., more PPT tasks) now. Stay tuned.
We have just implemented a self-assessment checker for this and now deployed at aclrollingreview.org/qualifi….
Please don’t use the form if you don’t have at least 10+ reviewing experience in ARR or any other listed venues. Any non-listed venues are not considered. It’s just a waste of time for you and for the ARR team.
#ARR #NLProc
On the ARR manual verification route: Please do NOT apply if you do not meet the current criteria: aclrollingreview.org/qualifi…
Any invalid applications just waste our ARR team members' time.
Atsuki Yamaguchi retweeted
We’ve been locked out of this account for a while😅 but we’re back, with some good news! 🎉
We have a bunch of new Sheffield NLP papers at @emnlpmeeting @aaclmeeting CIKM and INLG 📚
Congrats to everyone involved! 👏
More details below 👇