





Pinned Tweet
Proud for @emulated_ai to be a science partner contributing to the frontier of materials science!
With most of my career being in software, part of me has always wanted to go back to physical sciences. Glad to be working with the smartest folks in materials engineering & research!
To push the frontier we need realistic evals fully simulating laboratories and workflows. It takes the best to pull that off

we're hiring extremely aggressively! please forward us impressive things you've done and impressive people you know
we're meeting with 100 people over the next week to share what we're working on and find people to build with

I’m hiring researchers at @emulated_ai for roles in evals, RL, safety, and ML infra.
Must be in SF or open to relocating. Competitive pay. Happy to hire people transitioning into the field.
I also know 3-4 other teams hiring right now in SF, NY, and remote. If you’re cracked, DM me and I can probably place you.
Joseph Wang retweeted

I’m hiring researchers at @emulated_ai for roles in evals, RL, safety, and ML infra.
Must be in SF or open to relocating. Competitive pay. Happy to hire people transitioning into the field.
I also know 3-4 other teams hiring right now in SF, NY, and remote. If you’re cracked, DM me and I can probably place you.


GDM is on a generational tear. Materials science requires remarkable insights for things like next-generation transistors, batteries, and alloys
Carbon has a level of intuition & creativity you don't typically see with LLMs, they might be onto something

At Emulated, we've spent the last two months building the best team of material scientists building environments off of cutting-edge research
We're able to derive tasks much more closely aligned to frontier research. Read more here: gdpx.semianalysis.com/domain…
1
9
860
Joseph Wang retweeted
Today we’re releasing GDPx, a benchmark for measuring agentic capabilities across the most valuable domains.
GDPx is a true frontier-level benchmark: even the best model scores just 12% (1/7)🧵

Joseph Wang retweeted

Can AI agents do interpretability research?
At @PrimeIntellect Residency program, we built BioCircuit, an RL environment where agents trace attribution graphs on Qwen3-4B, find the features behind a concept and get graded by intervening on prompts they've never seen.
Link : amitprakash.in/biocircuit/

exciting work from the phsyera team benchmarking the frontier of animation + motion design!

Today, I am excited to announce Animation Bench. Our first benchmark to evaluate frontier models on web animation reconstruction.
Frontend generation is a common commercial use case for coding agents. In addition to static layout it contains transitions and interactions triggered by dynamic behaviours. We evaluated four frontier models on 48 tasks from real websites across three axes:
1. Visual Similarity
2. Motion Consistency
3. Layout Correctness.
We find that motion consistency is often incomplete or missing.
2
11
686
Joseph Wang retweeted
You can kind of just train specialized computer-use agents.
Here is a small Qwen3-VL-2B fine-tuned to do instance segmentation of cells through computer-use actions in a headless labeling app. It takes in screenshots as input and outputs commands to draw polygons, zoom, navigate, etc...
All navigation and labeling in this video is done by Qwen.
Inspired by Astra's computer use abilities, who can also label data quite well, albeit quite slowly.
Joseph Wang retweeted
Autoresearch Bench is our first attempt at measuring a model's ability to make meaningful progress on research problems over extended time horizons.
Very excited to get this out, and so proud of the hard work from our team!

Joseph Wang retweeted

Super excited to see the benchmark out! We are excited to scale our tasks further from here with even more frontier tasks and longer horizons. This is just the beginning!
Joseph Wang retweeted

Autoresearch Bench is finally out, go check it out
autoresearch-bench.com
Joseph Wang retweeted
Autoresearch Bench is live now !
Super excited to be part of this wonderful team : )
Joseph Wang retweeted

some really good tasks here.
i had an opportunity to look at some of these earlier.
benchmaxxing these should lead to better models for sure.

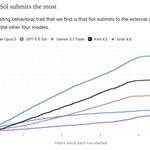
It was very interesting seeing the different behaviors for long-horizon tasks:
- GPT-5.6 and Grok iterated fast & often
- Opus liked to make larger, more substantial changes
We'll be sharing the 12 full hour runs soon! Certain models even plan according to how much time they're told they have

Joseph Wang retweeted

incredible set of tasks and pretty much long horizon has very long way to go across domains.

Physera's team is extremely fast moving! Excited to see more
We just evaluated Gemini-3.8-Flash on our
@PhyseraAI - TB bench. Our analysis on 5 random tasks from the set:
1. It is excellent at deriving and implementing a coherent numerical method. It turned an internally consistent mathematical model into working code, especially when it can derive a checkable optimum.
2. It is inconsistent on edge-case semantics. It knows the individual primitives, but assemble them in the wrong order when a specification has interacting edge cases.
3. It tends to overbuild static-analysis solutions while missing the hardest coverage cases.
4. In multiple tasks long trajectories do not imply better outcomes. More exploration became speculative scope expansion rather than targeted verification.
I think it is promising low-cost choice for numerical/scientific coding / transformations with crisp formulas / tasks where it can independently check residuals or invariants but had fallbacks for production shell tooling / static analysis / clinical derivations / compliance-style work.

14
2,247